Ideas across the book
Concepts that connect
Follow an idea through the book, or bring your own question and agent to the knowledge graph.
About the definitions and connections
Definitions use established vocabulary where it fits. Some terms, especially around coding agents and harnesses, are still developing or vary between sources. “Usage in this book” notes explain our working definitions, course protocols, and broader applications of a term.
The lines are authored teaching connections. Read an arrow as a statement from its source, through the label, to its target. The label and explanation establish the meaning; an arrow alone does not establish causation or a prerequisite. Comparisons and associations use plain lines. Each connection links back to the reading.
Your question · your tools
Explore with your own agent
Start from your course task, current reading, or a question of your own. Choose a task starting point, connect your agent with MCP, or give it the guide below to explore ideas and experiments through the graph.
Connect it, then check it
- Connect your tools. Use an agent that can fetch URLs. If it works with files instead, download the guide and either graph format and add them to its context. The guide describes the data and how to follow connections.
- Pick a starting point. If you are unsure, ask “Read this guide and help me get started.” Choose one of the suggested activities, or bring your own question. State a guess or prediction before asking for an explanation.
- Check the explanation. Follow a citation yourself. Compare the answer with the passage and its assumptions, and distinguish the book’s connections from connections your agent proposes. Keep a short record of what you accepted, challenged, or could not verify.
Connecting the graph and judging what your agent retrieves are part of the learning. You can also explore it directly below.
Explore the whole book46 concepts and their connections
Concepts and connections
Adjust the graph and filters
Choose a group to highlight its members in context.
46 concepts · 110 connections
Search or choose a reading to narrow both views. Focus on an idea to see its neighborhood; select a node to read and continue exploring.
Drag anywhere or scroll to move the map. Ctrl/⌘ + scroll or pinch to zoom. Fit shows the whole map; Readable restores the text size. With the map focused, arrow keys move it, +/− zoom, and 0 fits. Every topic and connection is also available as text below.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations. Hover or focus a topic to reveal its relationship labels. A selected topic keeps its labels visible; press Escape in the map to clear them.
Read the relationships
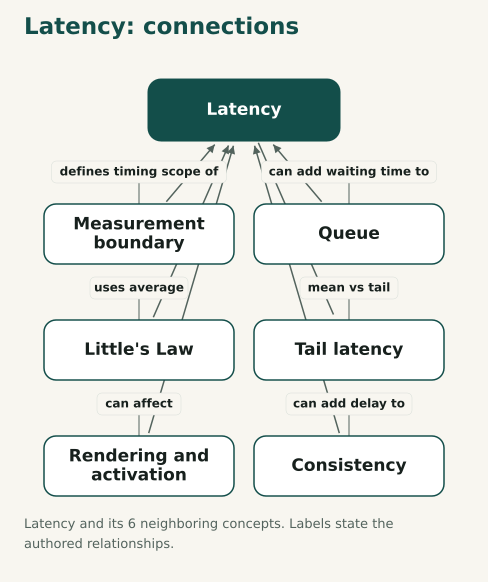
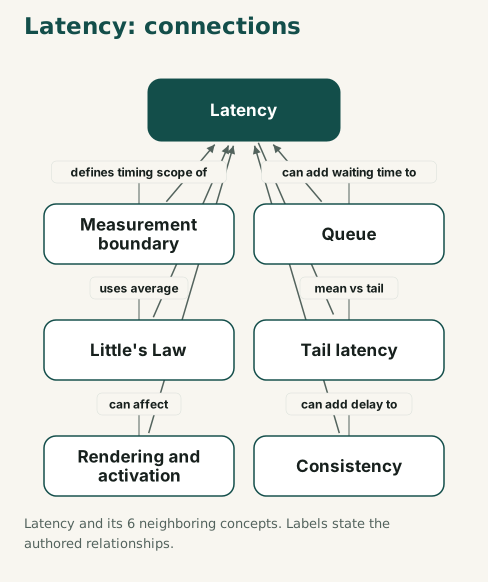
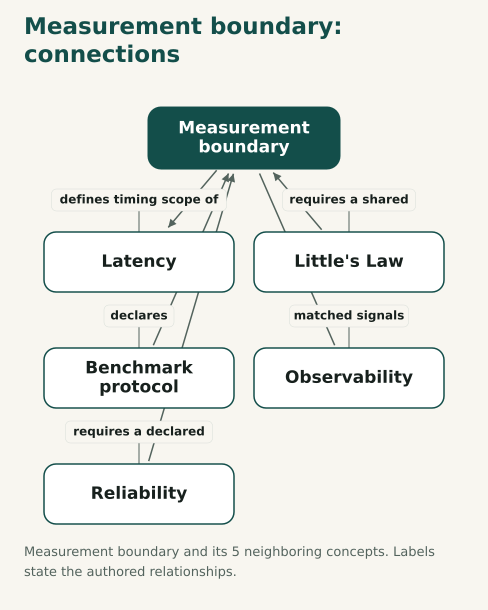
- Measurement boundary defines timing scope of Latency
The measurement boundary defines which waiting and processing latency includes.
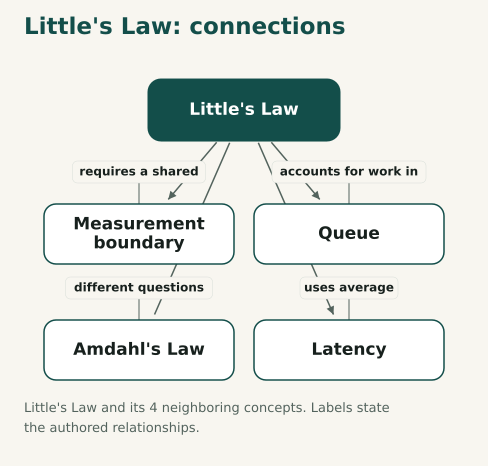
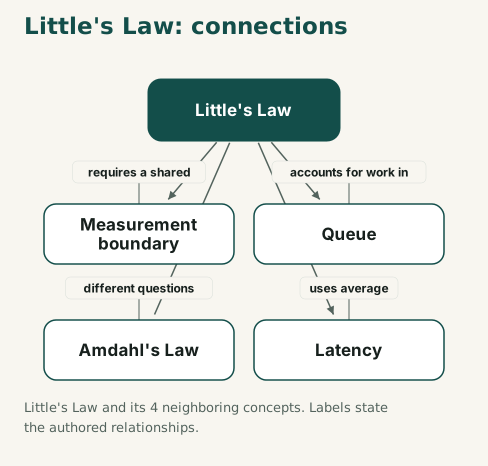
- Little's Law requires a shared Measurement boundary
Little's Law requires work in progress, rate, and average time to describe the same boundary.
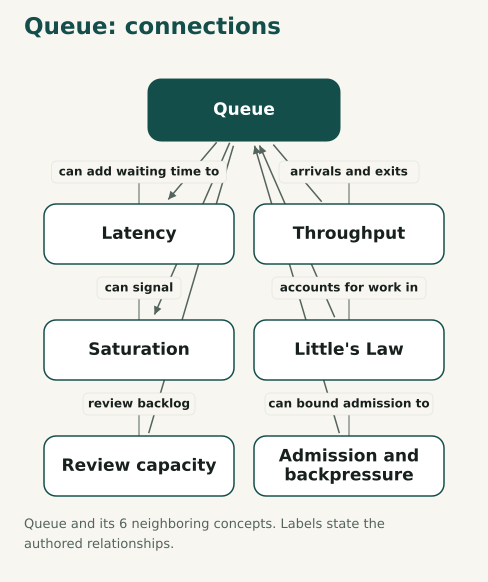
- Queue can add waiting time to Latency
Waiting in a queue contributes to latency when the queue is inside the timing boundary.
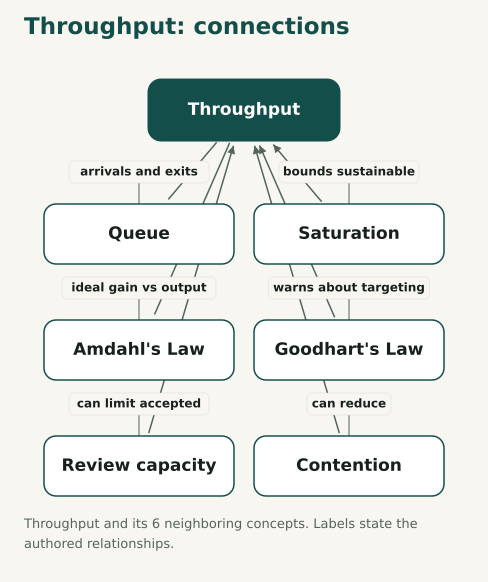
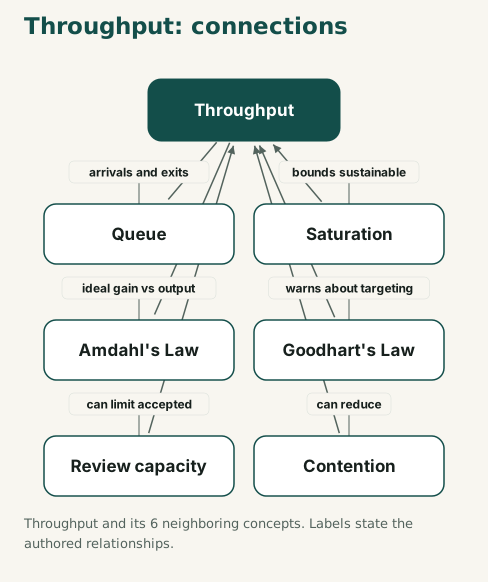
- Throughput Queue arrivals and exits
Compare admissions with all departures at the queue boundary to explain backlog growth. Useful throughput separately counts completions that meet the declared outcome criteria.
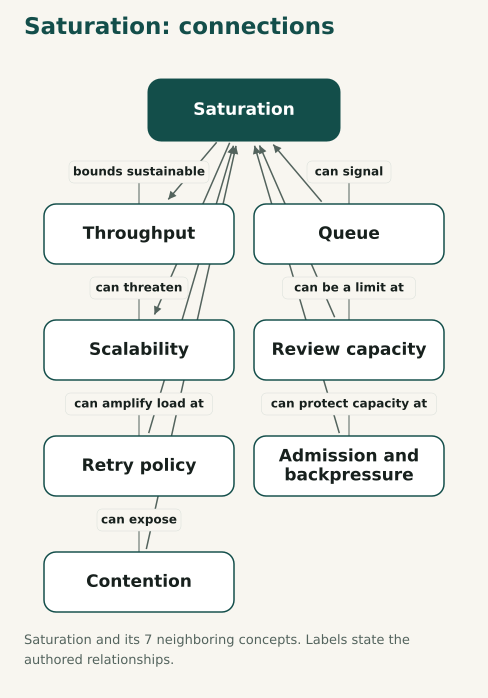
- Saturation bounds sustainable Throughput
The saturated stage bounds the sustainable completion rate for the declared workload.
- Queue can signal Saturation
A growing queue can expose pressure above completion capacity, even while acknowledgments remain fast.
- Little's Law accounts for work in Queue
Little's Law connects stable work in progress, including queued and processing work, to rate and average time.
- Little's Law Amdahl's Law different questions
Little's Law checks stable flow averages; Amdahl's Law bounds ideal fixed-workload parallel speedup.
- Throughput Amdahl's Law ideal gain vs output
An Amdahl speedup bound does not guarantee accepted-change throughput; review, coordination, and correctness still matter.
- Little's Law uses average Latency
Little's Law uses average time inside the boundary, not a tail percentile such as p95.
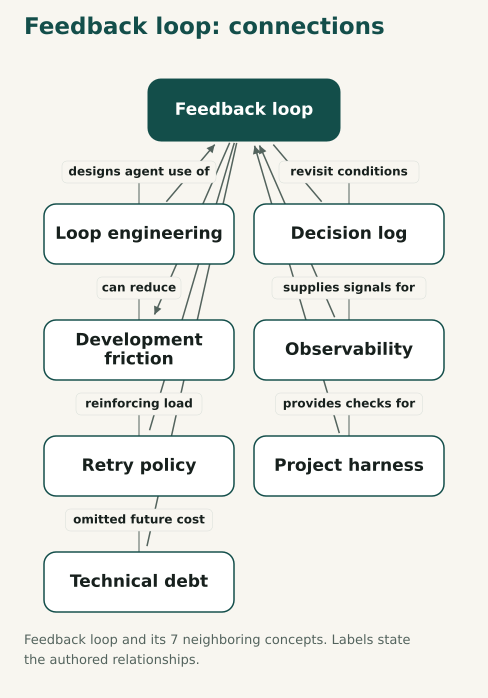
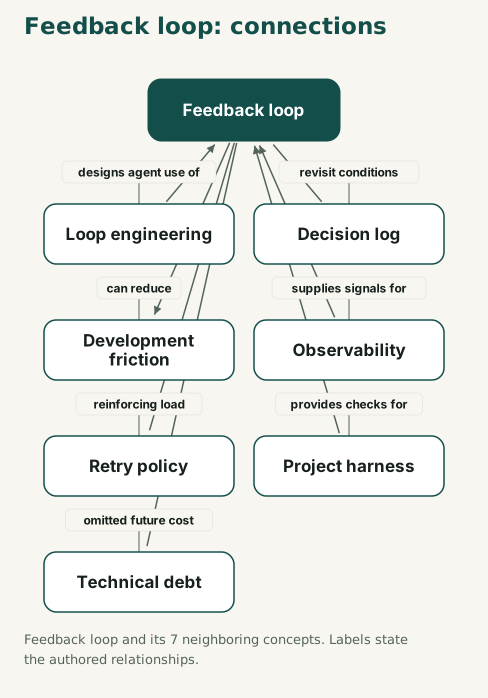
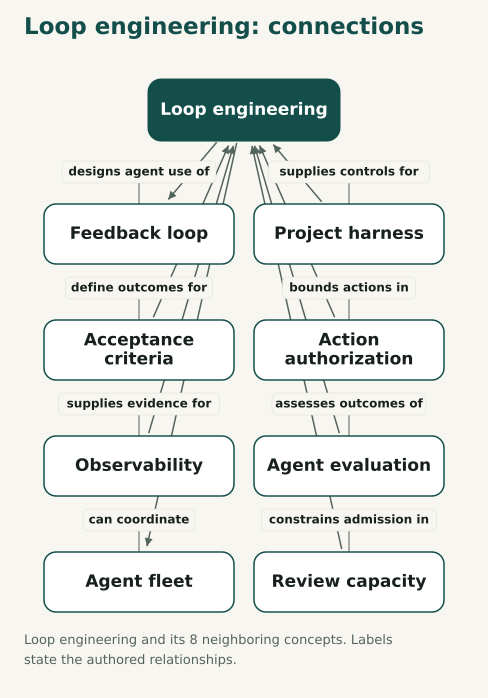
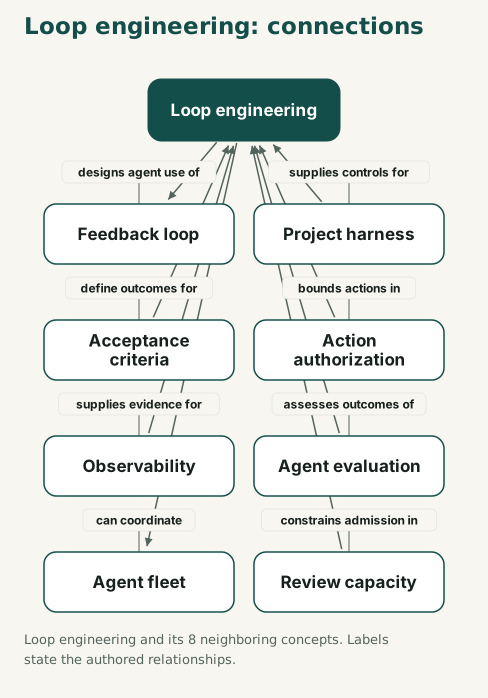
- Loop engineering designs agent use of Feedback loop
Loop engineering chooses the observations and responses that guide agent work; a feedback loop describes how effects influence subsequent behavior, including harmful reinforcing cycles.
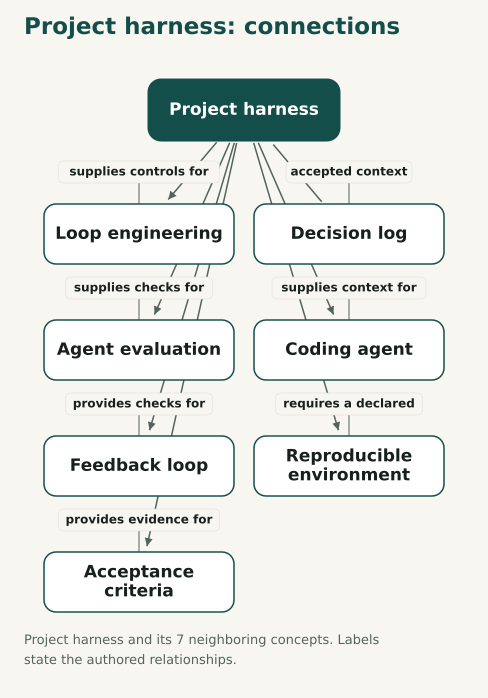
- Project harness supplies controls for Loop engineering
The project harness supplies maintained instructions, environments, and checks that loop engineering connects to task initiation, progress, repair, and acceptance.
- Acceptance criteria define outcomes for Loop engineering
Acceptance criteria define the result a loop should pursue. A stop condition can also terminate an unsuccessful run at its budget or escalation boundary.
- Action authorization bounds actions in Loop engineering
A loop may continue only within the granted action authority; starting another iteration or run does not expand permissions.
- Observability supplies evidence for Loop engineering
Recorded inputs, tool outcomes, failures, and state changes help explain why the loop continued, stopped, or escalated; a successful job status alone can hide an idle or ineffective run.
- Agent evaluation assesses outcomes of Loop engineering
Representative tasks and independent acceptance evidence can assess a loop change while accounting for retries, resource cost, and human correction.
- Loop engineering can coordinate Agent fleet
A loop can assign and verify work across a fleet, but one agent can also operate inside a designed loop. Delegation adds coordination and integration obligations.
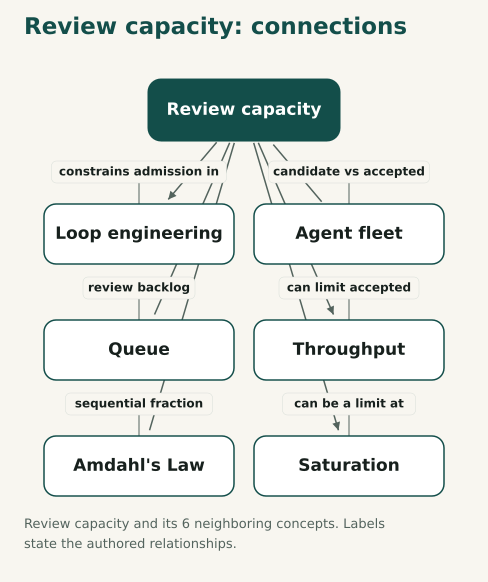
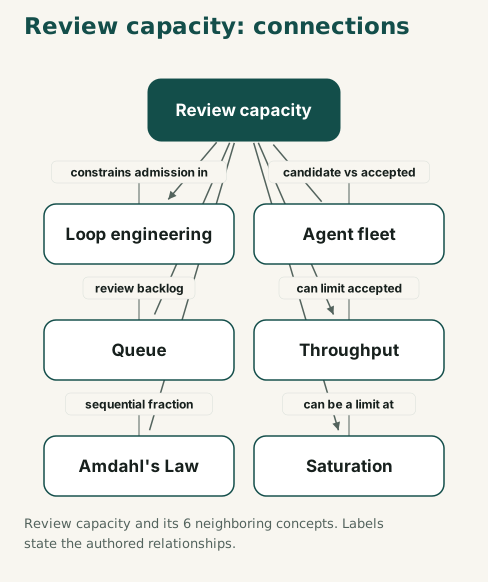
- Review capacity constrains admission in Loop engineering
Loop design must account for the owner's capacity to review, correct, and accept work; more autonomous runs can otherwise accumulate an unreviewed backlog.
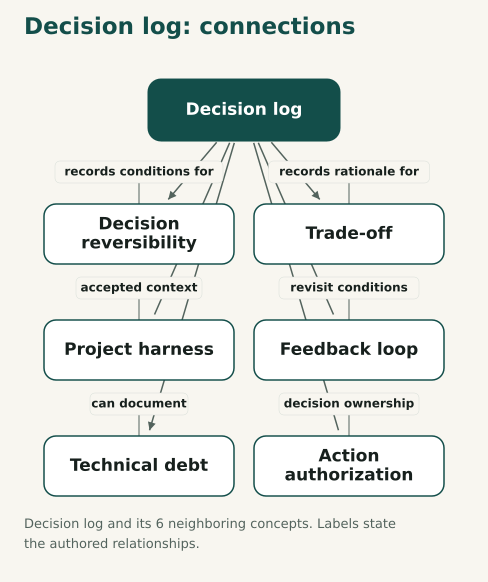
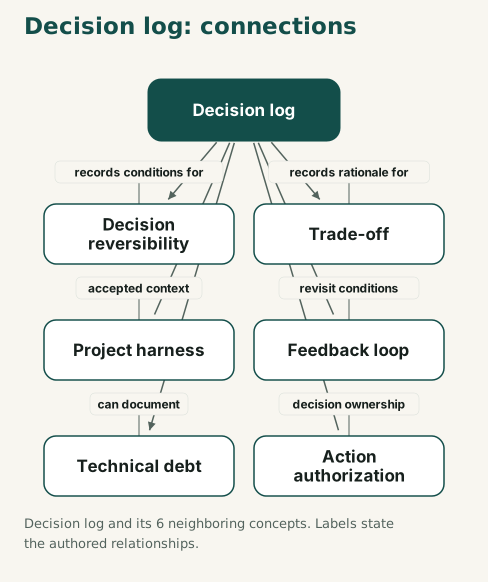
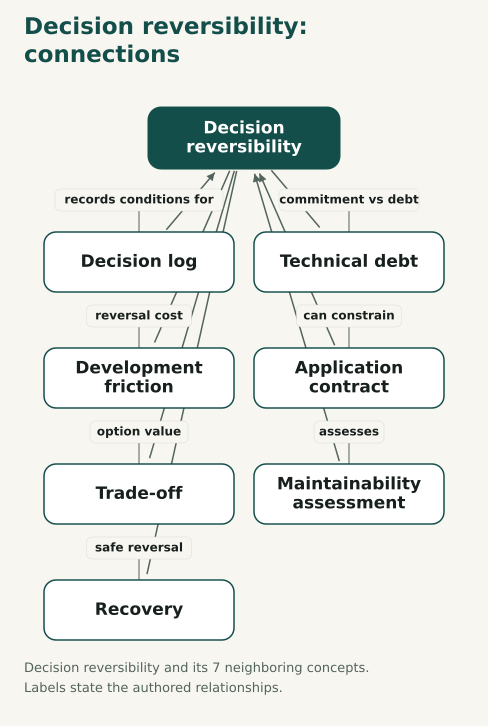
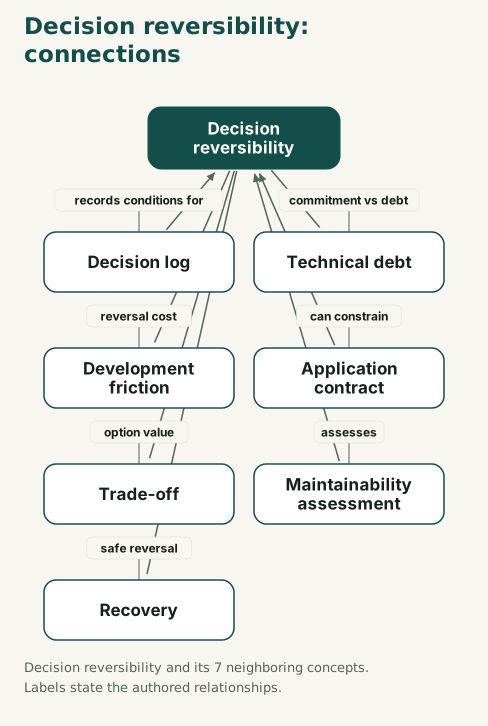
- Decision log records conditions for Decision reversibility
A decision record can state which choices remain soft, what dependencies would make them hard, and what safe reversal would require.
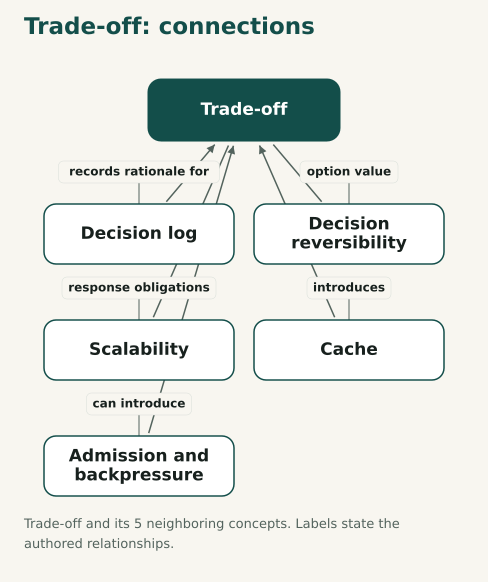
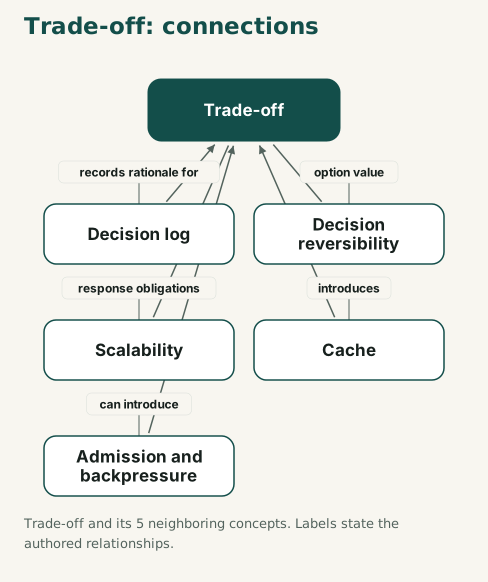
- Decision log records rationale for Trade-off
The log preserves the alternatives, rationale, and consequences that justified a trade-off under the conditions known at the time.
- Decision log Project harness accepted context
Decision records preserve accepted project context, while current specifications and executable harness checks must reflect the implemented choice.
- Decision log Feedback loop revisit conditions
A recorded revisit condition makes new evidence a reason to review a choice; a superseding record preserves why the earlier decision changed.
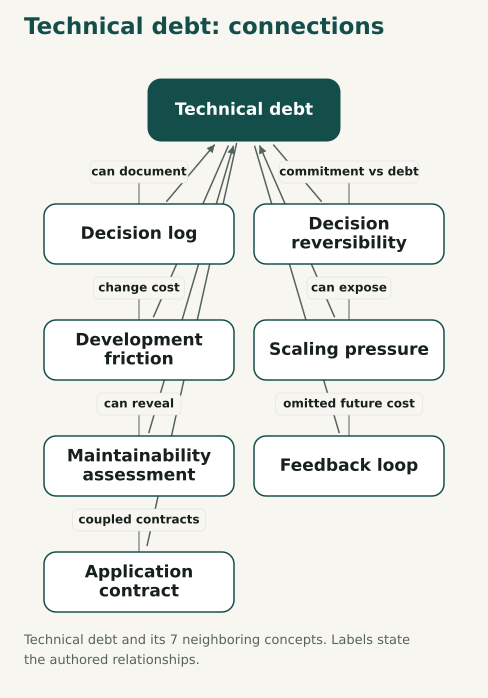
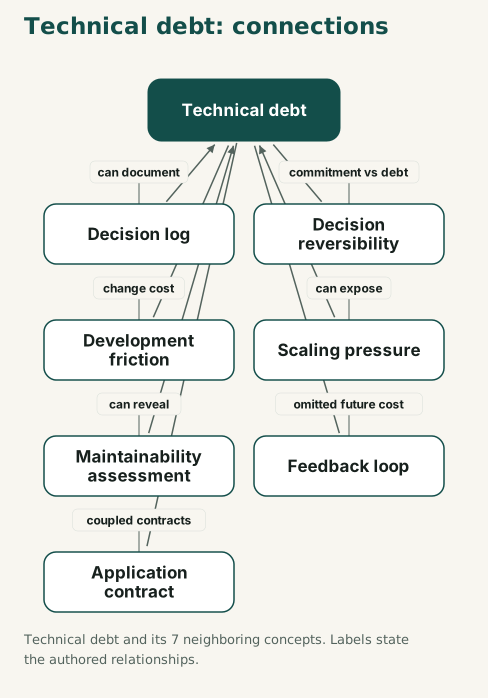
- Decision log can document Technical debt
A record makes deliberately accepted debt and its future change cost visible so an owner can review it instead of letting the obligation disappear from view.
- Decision log Action authorization decision ownership
A proposed record does not grant action authority; acceptance needs a named owner, and the record's status must distinguish intent from implementation.
- Decision reversibility Technical debt commitment vs debt
Technical debt can reduce future options, but a hard decision is not automatically debt; its dependencies and reversal cost may be necessary and justified.
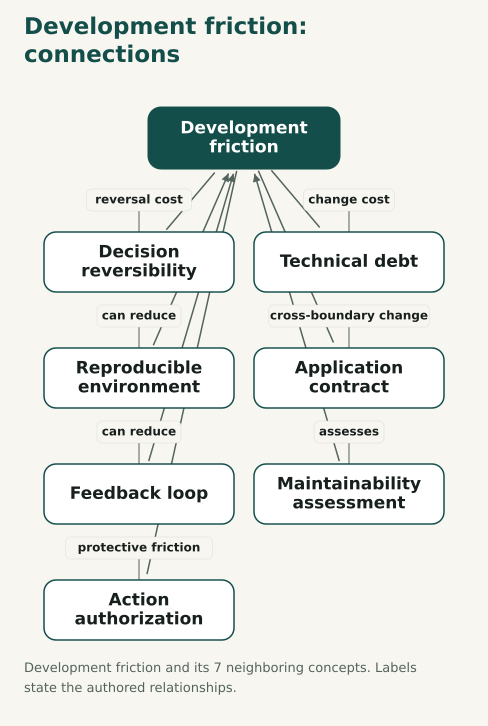
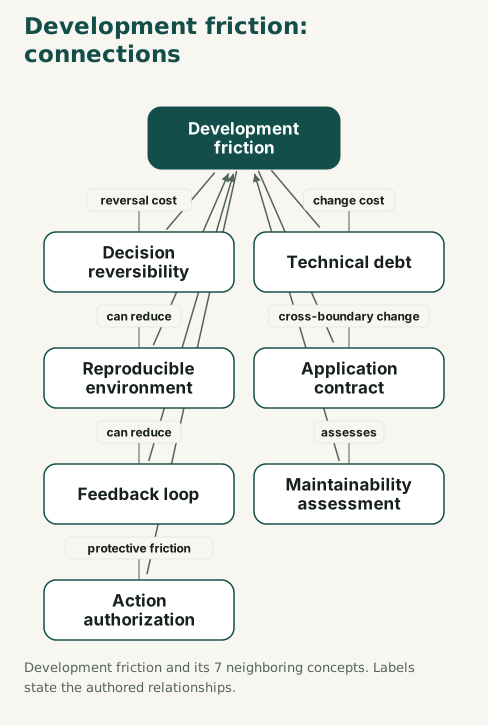
- Decision reversibility Development friction reversal cost
A choice becomes harder to revise as safe reversal requires coordination across data, consumers, and deployment boundaries.
- Application contract can constrain Decision reversibility
An independently deployed consumer relying on a contract can turn a locally editable choice into a hard compatibility commitment.
- Decision reversibility Trade-off option value
Planning a trade-off includes the value of keeping an uncertain choice soft and the obligations introduced by committing to it.
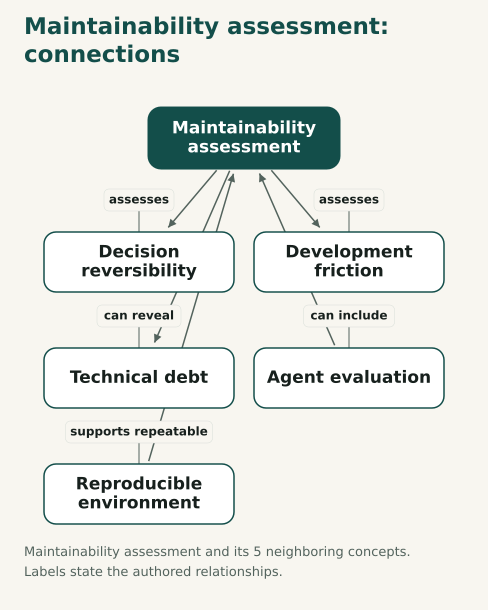
- Maintainability assessment assesses Decision reversibility
A bounded change probe can test how much effort a revision requires and which dependencies make a decision hard to change.
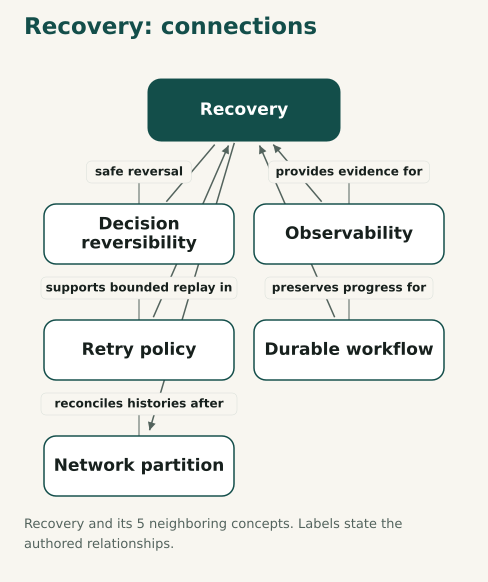
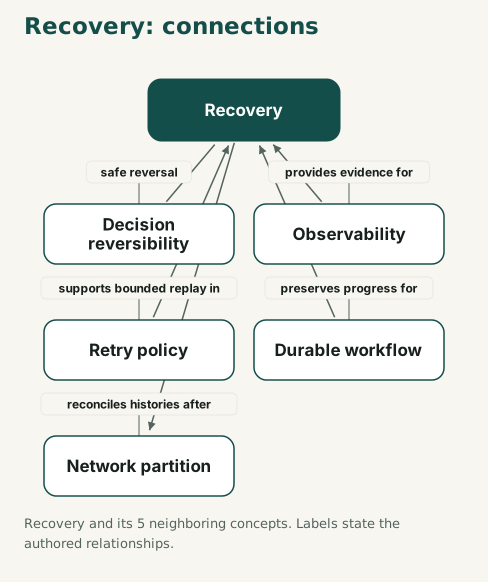
- Decision reversibility Recovery safe reversal
Reversing a decision after durable effects may require migration or reconciliation; restoring code alone does not establish safe recovery.
- Development friction Technical debt change cost
Friction can expose the practical cost of technical debt, but protective checks and necessary commitments are not automatically debt.
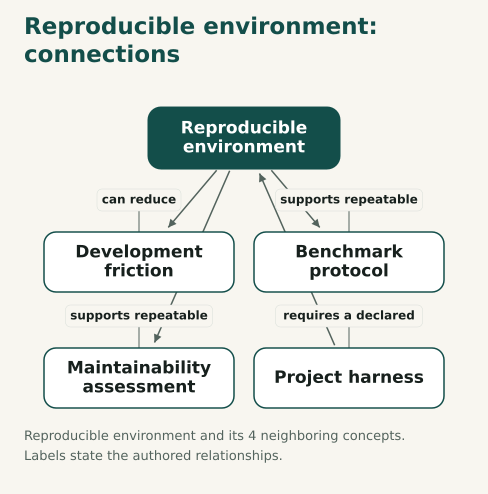
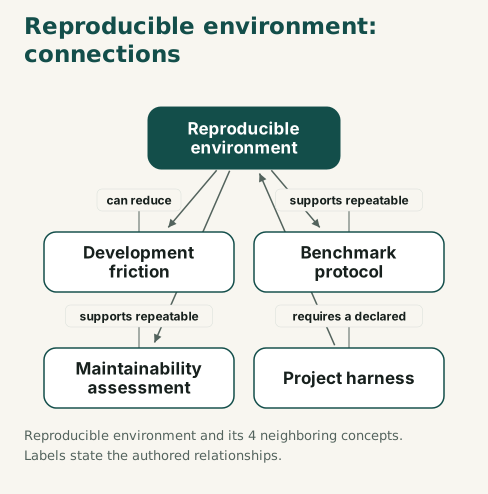
- Reproducible environment can reduce Development friction
A declared, reproducible environment can reduce setup friction and reveal hidden inputs rather than relying on undocumented repairs.
- Development friction Application contract cross-boundary change
A small feature can create friction as it crosses HTTP, data, cache, and deployment contracts owned at different boundaries.
- Feedback loop can reduce Development friction
Feedback matched to the changed boundary can reduce diagnosis and revision friction while retaining useful checks.
- Maintainability assessment assesses Development friction
A bounded change probe records concrete blockages and effort so a friction claim can be tested by an unfamiliar maintainer.
- Development friction Action authorization protective friction
Explicit ownership reduces coordination ambiguity; authorization and release gates can remain protective friction when they control a named risk.
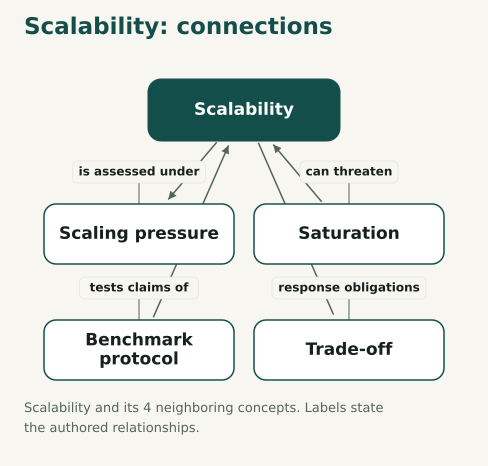
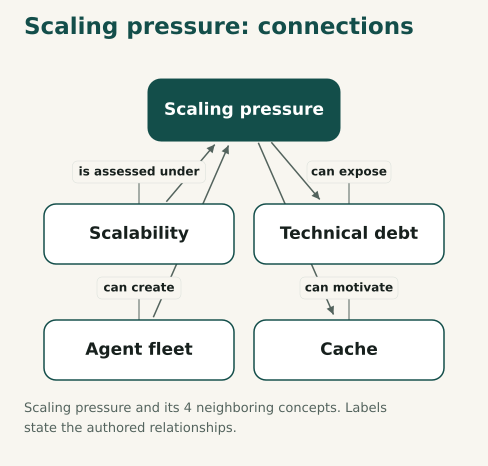
- Scalability is assessed under Scaling pressure
A scalability claim states which goal must hold as a particular pressure changes.
- Saturation can threaten Scalability
Saturation identifies the current limit that threatens the maintained scalability goal.
- Benchmark protocol tests claims of Scalability
A benchmark protocol makes a conditional scalability claim testable.
- Scalability Trade-off response obligations
A scaling response must justify the costs and obligations it introduces alongside the maintained goal.
- Scaling pressure can expose Technical debt
Change pressure can expose future change cost from earlier shortcuts, compromises, or unmanaged coupling. A necessary compatibility obligation alone does not establish technical debt.
- Agent fleet can create Scaling pressure
Adding contributors or agents increases coordination pressure as well as possible parallelism.
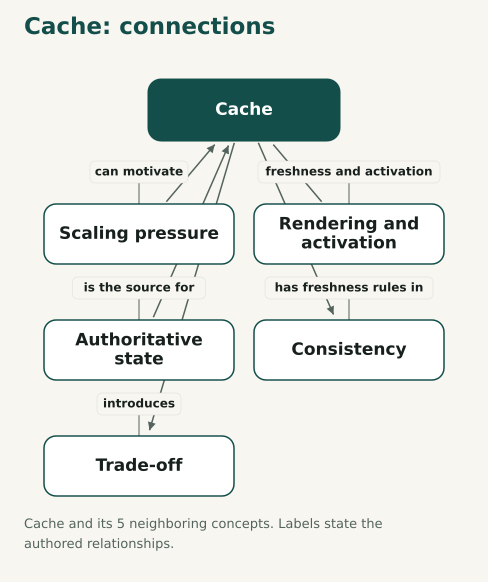
- Scaling pressure can motivate Cache
Data or demand pressure may motivate caching, but the cache introduces a freshness and access contract.
- Benchmark protocol declares Measurement boundary
A benchmark protocol declares the boundary at which elapsed time and completed work are counted.
- Reproducible environment supports repeatable Benchmark protocol
Reproducible environments help separate implementation differences from setup differences in a benchmark.
- Benchmark protocol Agent evaluation shared protocol
Benchmarks and agent evaluations both require declared tasks, boundaries, outcome criteria, and failure accounting.
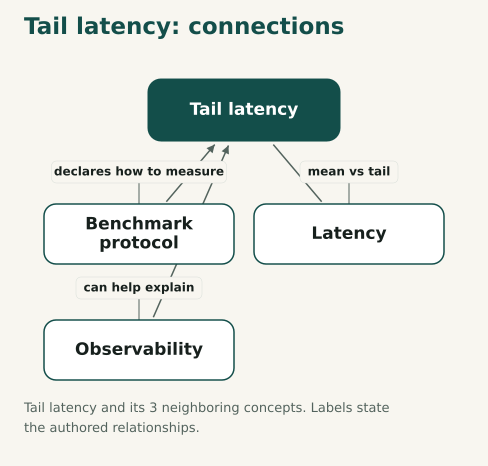
- Benchmark protocol declares how to measure Tail latency
A benchmark needs a declared latency population and percentile convention to support a tail-latency claim.
- Latency Tail latency mean vs tail
Tail latency describes slow outcomes that an average elapsed time can hide.
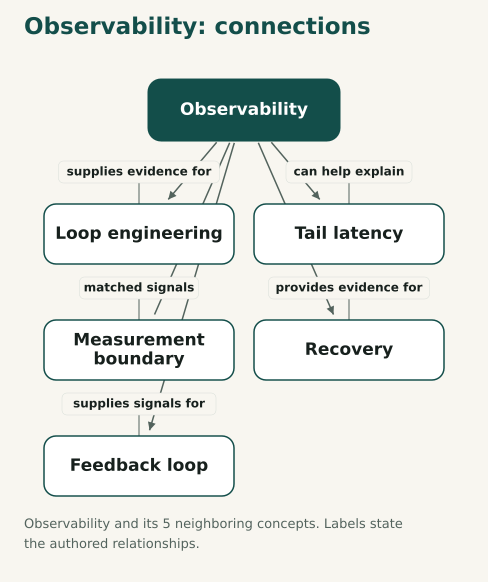
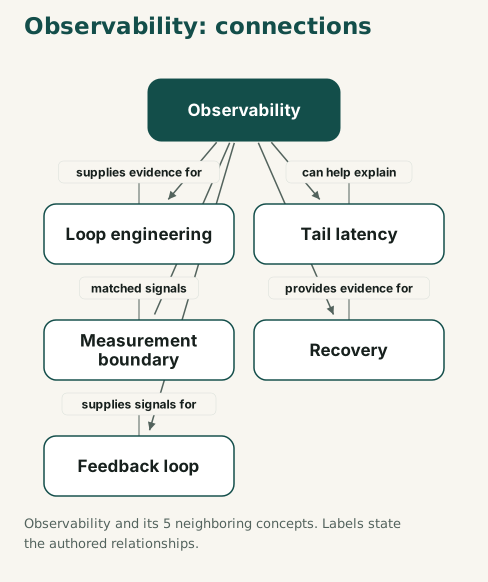
- Observability can help explain Tail latency
Latency distributions reveal a slow population; traces and event records help investigate its path.
- Observability Measurement boundary matched signals
Useful signals must identify the same logical work and boundaries as the outcome being explained.
- Observability provides evidence for Recovery
Recovery needs evidence about authoritative state, pending work, and user-visible outcomes, not only process health.
- Observability supplies signals for Feedback loop
A corrective feedback loop can choose a useful response only when its signals describe the relevant goal and boundary.
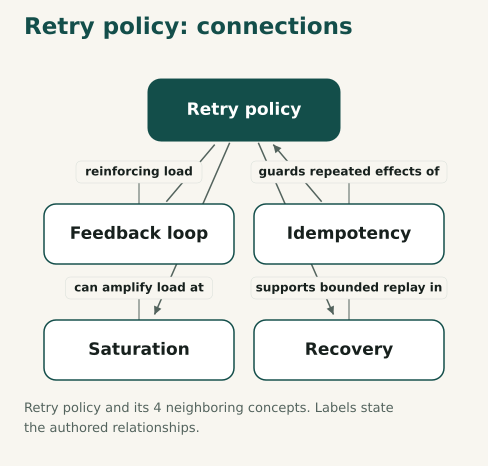
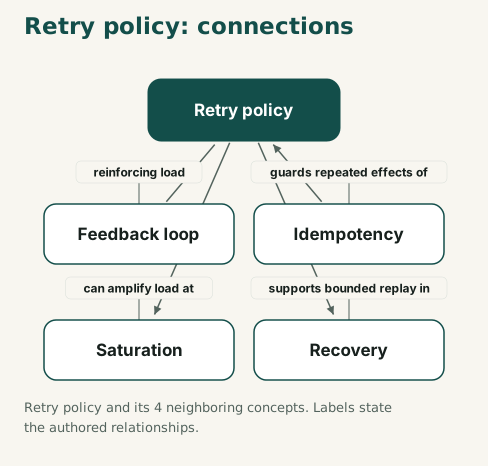
- Feedback loop Retry policy reinforcing load
Overload can cause timeouts that trigger retries and add more load. A bounded retry policy with delay and admission control can limit this reinforcing feedback; retry-safe effects are still required.
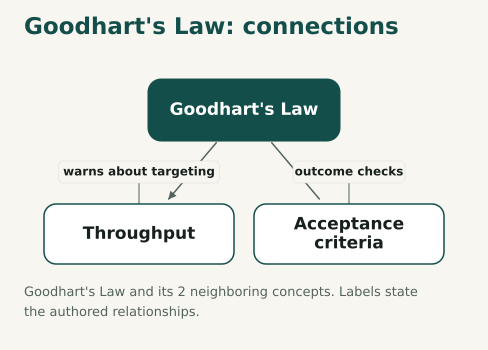
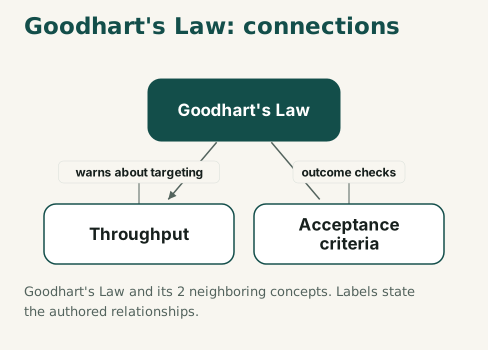
- Goodhart's Law warns about targeting Throughput
Counting generated or acknowledged work can become a misleading target when useful accepted completions are the intended outcome.
- Goodhart's Law Acceptance criteria outcome checks
Acceptance criteria help check the intended outcome when a convenient proxy metric becomes a target.
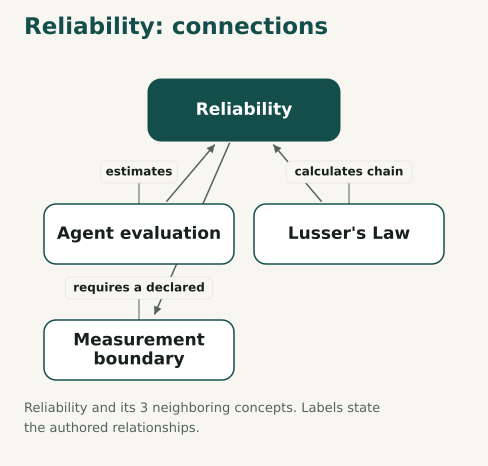
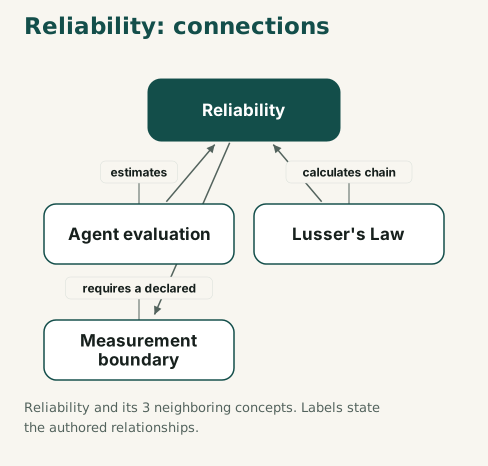
- Agent evaluation estimates Reliability
Repeated agent evaluation distinguishes a successful example from evidence about success frequency and uncertainty.
- Acceptance criteria define grading for Agent evaluation
An evaluation grader must assess the declared task and invariants rather than hidden acceptance assumptions.
- Project harness supplies checks for Agent evaluation
The project harness supplies reusable checks and setup, while the evaluation harness provisions and scores trials.
- Maintainability assessment can reveal Technical debt
A bounded change probe can expose coupling or earlier shortcuts that make a later modification costly even when current behavior tests pass. Use that evidence to distinguish debt from necessary compatibility work.
- Agent evaluation can include Maintainability assessment
An agent evaluation can include next-change tasks to assess maintainability beyond initial task success.
- Reproducible environment supports repeatable Maintainability assessment
An unfamiliar auditor needs a reproducible starting environment to distinguish setup friction from change difficulty.
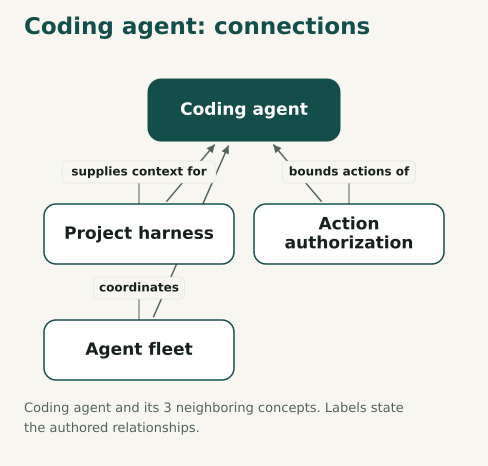
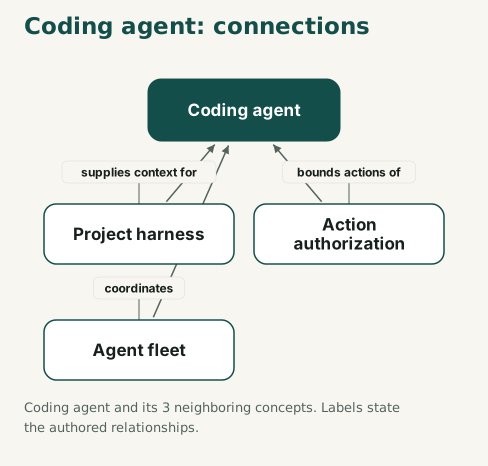
- Project harness supplies context for Coding agent
An agent's useful capability depends on the project context, tools, checks, and commands supplied by its harness.
- Action authorization bounds actions of Coding agent
An agent's ability to invoke a tool must be bounded by the authority granted for the task.
- Agent fleet coordinates Coding agent
A fleet extends one agent's execution loop with explicit coordination, integration, and acceptance.
- Project harness provides checks for Feedback loop
Executable harness checks turn generated work into feedback that can guide a revision.
- Project harness requires a declared Reproducible environment
A harness needs a declared environment so its checks can be run by another agent or maintainer.
- Project harness provides evidence for Acceptance criteria
Harness checks provide repeatable evidence for acceptance criteria, while a named owner remains accountable for acceptance.
- Action authorization Acceptance criteria acceptance ownership
Authority defines who may execute work and who may judge that the acceptance criteria have been met.
- Action authorization Authoritative state permission vs commit
Action authorization asks who may execute an operation; authoritative state establishes its committed outcome and the boundary responsible for preserving it. An authorized attempt can still fail to commit.
- Application contract states rules for Action authorization
An application contract specifies which actors may invoke an operation and which boundary enforces that permission. A workspace handle or tool credential alone does not authorize every action.
- Feedback loop Technical debt omitted future cost
Feedback that omits the cost of later changes can allow technical debt to grow while current tasks pass.
- Technical debt Application contract coupled contracts
Unclear or tightly coupled contracts can make one local change require coordinated changes elsewhere.
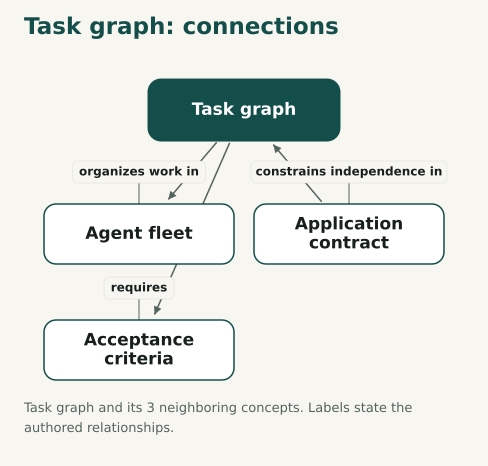
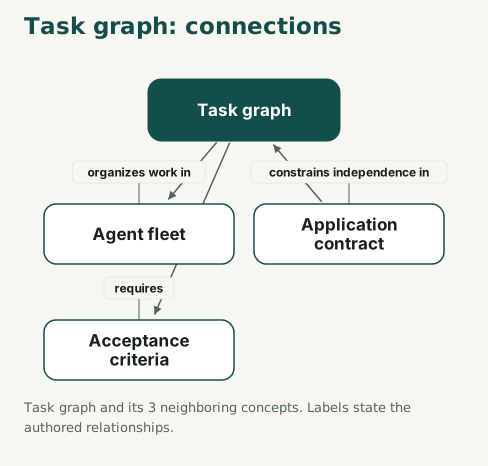
- Task graph organizes work in Agent fleet
A fleet's task graph states what can proceed independently and where contracts or integration impose order.
- Amdahl's Law bounds ideal speedup of Agent fleet
Amdahl's Law provides an ideal bound when part of a fleet's fixed workload remains sequential.
- Agent fleet Review capacity candidate vs accepted
Additional agents can increase candidate output faster than human review can accept it.
- Application contract constrains independence in Task graph
Task independence depends on compatible shared contracts, not merely separate files.
- Task graph requires Acceptance criteria
Integration points in a task graph need acceptance checks that cover the combined behavior.
- Review capacity Queue review backlog
Candidate changes waiting for review form a queue. Its growth depends on submissions and all departures, including rejection or withdrawal; accepted-change throughput counts only successful acceptance.
- Review capacity can limit accepted Throughput
Reviewer attention and correction effort can limit accepted-change throughput even when generation speeds up.
- Review capacity Amdahl's Law sequential fraction
Review or integration that must remain sequential belongs in Amdahl's sequential fraction for a fixed task. A growing review queue asks a separate question about ongoing arrival and completion rates.
- Review capacity can be a limit at Saturation
Human review capacity can be the binding limit when candidate work arrives faster than it can be understood, integrated, and accepted. Increasing generation alone does not expand that capacity.
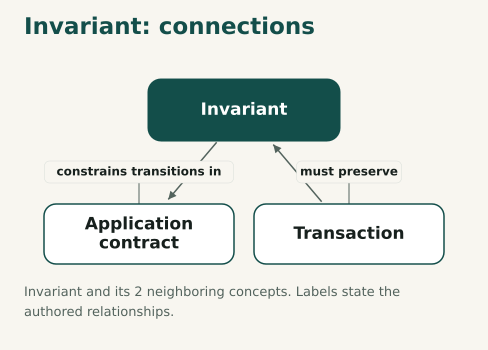
- Invariant constrains transitions in Application contract
A contract describes valid boundary behavior; invariants state conditions its accepted transitions must preserve.
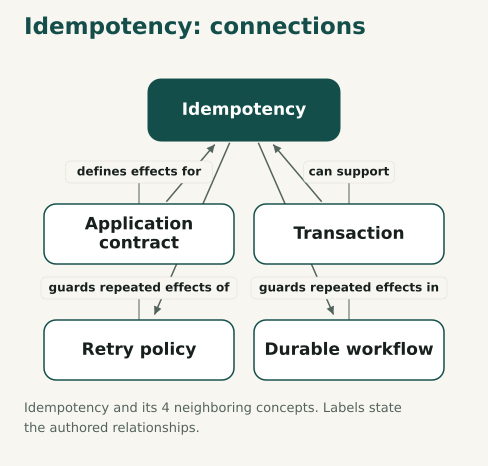
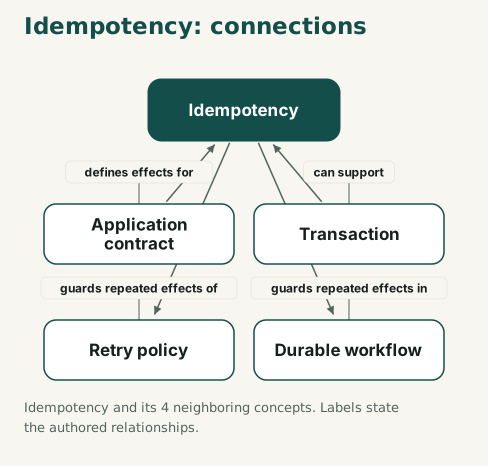
- Application contract defines effects for Idempotency
The contract names all intended effects against which idempotency is judged. A key-based retry protocol also needs scope, conflict, retention, and outcome rules.
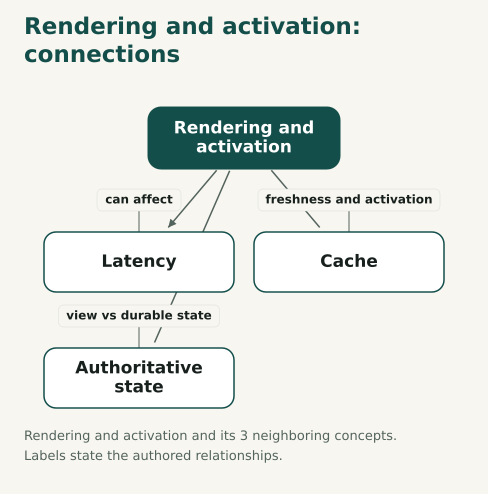
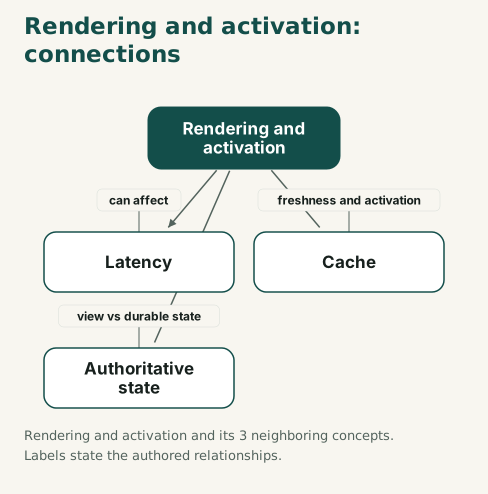
- Rendering and activation can affect Latency
Moving rendering or activation changes which work lies on the measured user journey.
- Rendering and activation Cache freshness and activation
A cached representation needs freshness and activation policies in addition to a fast delivery path.
- Rendering and activation Authoritative state view vs durable state
Rendering a representation must remain distinct from committing the durable action it displays.
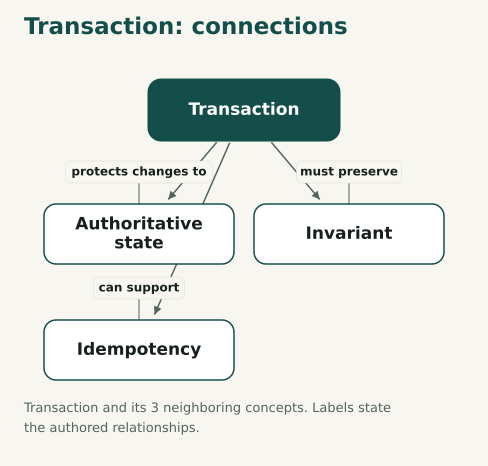
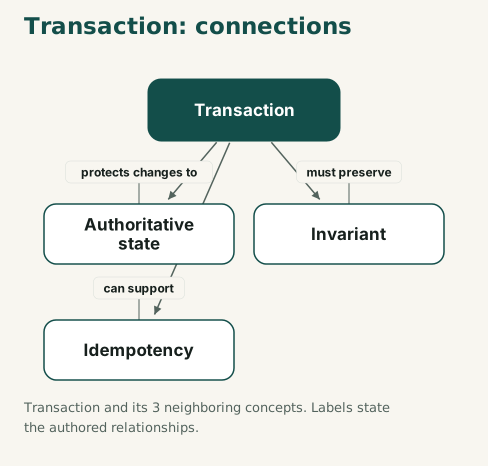
- Transaction protects changes to Authoritative state
Transactions protect related changes at the durable authority under the store's actual guarantees.
- Authoritative state is the source for Cache
A cache is a controlled copy whose freshness and invalidation depend on the authoritative state.
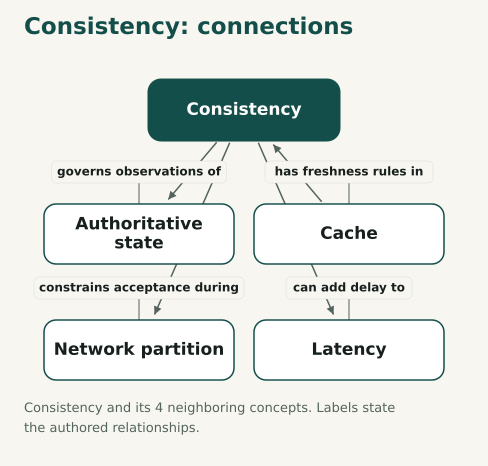
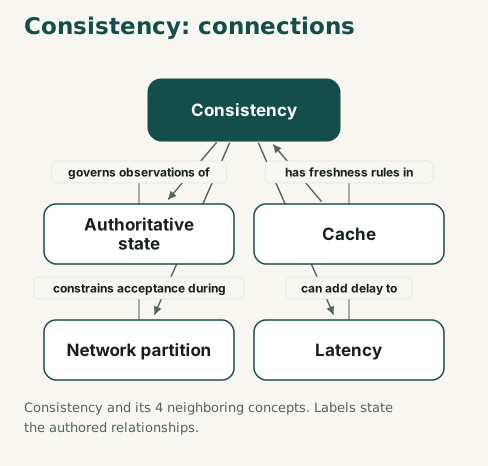
- Consistency governs observations of Authoritative state
Consistency promises describe how consumers observe authoritative changes through concurrency and copies.
- Transaction must preserve Invariant
The chosen transaction and isolation behavior must preserve the domain invariant under concurrent transitions.
- Transaction can support Idempotency
A key-based command protocol can atomically enforce operation identity with the promised effects and a reusable result at their authority. A transaction alone does not prevent repeated commands.
- Cache has freshness rules in Consistency
Cache freshness is part of the observation promise, but it does not by itself define every consistency guarantee.
- Cache introduces Trade-off
Caching can reduce dependency load while introducing invalidation, freshness, and access obligations.
- Idempotency guards repeated effects of Retry policy
A deduplicated command reuses its logical operation identity after an ambiguous outcome so the retry cannot invent another durable action.
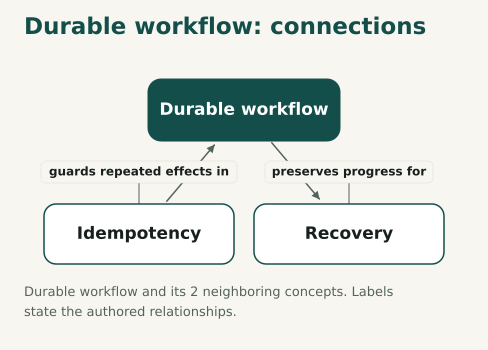
- Idempotency guards repeated effects in Durable workflow
Durable coordination can resume steps, while idempotency protects effects that may be attempted again.
- Retry policy can amplify load at Saturation
Retries can amplify pressure on an already saturated dependency instead of improving useful completion.
- Retry policy supports bounded replay in Recovery
Bounded retry and backlog replay policies must protect state integrity and capacity during recovery.
- Admission and backpressure can bound admission to Queue
A bounded queue requires a policy for slowing or rejecting new work when downstream capacity cannot keep up.
- Admission and backpressure can protect capacity at Saturation
Admission controls can protect a saturated boundary while making rejected or delayed work explicit.
- Admission and backpressure can introduce Trade-off
Bounding admission can preserve useful service while sacrificing immediate acceptance of some work.
- Durable workflow preserves progress for Recovery
Preserved workflow progress helps interrupted coordination resume, but recovery must still audit its effects.
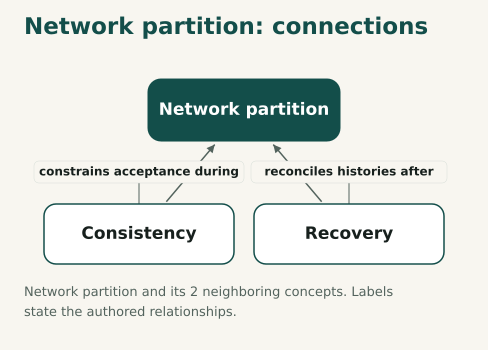
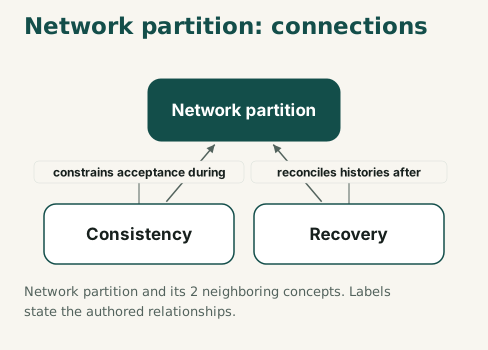
- Consistency constrains acceptance during Network partition
During a partition, the operation's consistency promise constrains which work disconnected nodes may accept.
- Recovery reconciles histories after Network partition
Recovery from a partition may require reconciling divergent histories and draining pending work.
- Consistency can add delay to Latency
Coordinating remote state can add latency; permitting delayed observations changes the consumer's contract.
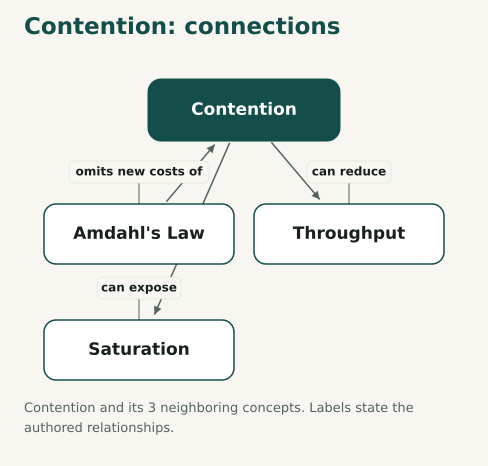
- Amdahl's Law omits new costs of Contention
Amdahl's ideal fixed-workload bound omits new contention and coordination costs introduced by parallelism.
- Contention can reduce Throughput
Competition for a shared resource can make throughput plateau or decline as workers are added.
- Contention can expose Saturation
Contention can expose a binding shared-resource limit before every worker is fully utilized.
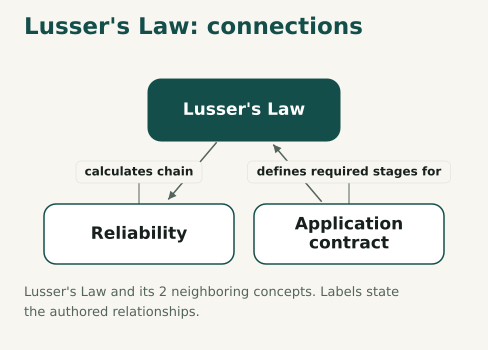
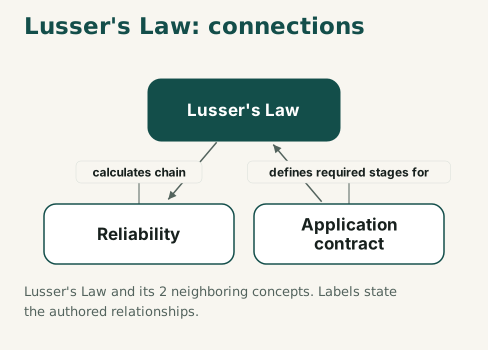
- Lusser's Law calculates chain Reliability
Lusser's Law calculates a required-stage chain's reliability under a declared independence assumption.
- Application contract defines required stages for Lusser's Law
The reliability chain includes the stages that must succeed to meet the declared end-to-end contract.
- Reliability requires a declared Measurement boundary
A reliability claim needs a declared eligible-attempt denominator and end-to-end success boundary.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Concept list
46 topics
Choose an idea for its definition, examples, and connections.
No topics match. Clear the search or reset the view above.
Acceptance criteriaDevelopment Declared observable conditions a candidate result must satisfy before it counts as completed work. Explore concept Group member
Development
Acceptance criteria
- Definition
- Declared observable conditions a candidate result must satisfy before it counts as completed work.
- Assumptions
- Criteria should follow the task and invariants, be testable where possible, and identify who accepts the result. Passing checks establish only what those checks cover.
- Worked example
- An event change must preserve workspace isolation, show the new activity in the feed, and pass the shared tests before it counts as accepted throughput.
- Common mistake
- A clean diff or successful merge establishes correctness. Behavior, integration, and accountable review are separate obligations.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Acceptance criteria · 6 connections
Read the relationships
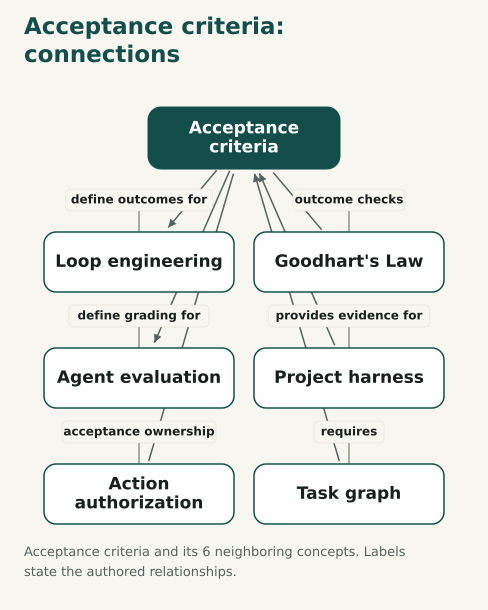
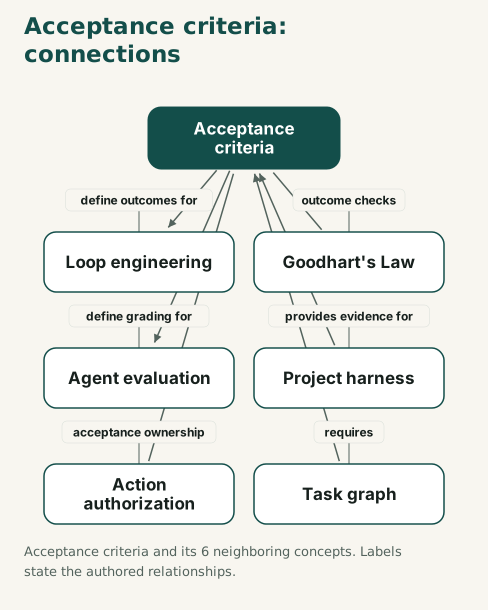
- Acceptance criteria define outcomes for Loop engineering
Acceptance criteria define the result a loop should pursue. A stop condition can also terminate an unsuccessful run at its budget or escalation boundary.
- Goodhart's Law Acceptance criteria outcome checks
Acceptance criteria help check the intended outcome when a convenient proxy metric becomes a target.
- Acceptance criteria define grading for Agent evaluation
An evaluation grader must assess the declared task and invariants rather than hidden acceptance assumptions.
- Project harness provides evidence for Acceptance criteria
Harness checks provide repeatable evidence for acceptance criteria, while a named owner remains accountable for acceptance.
- Action authorization Acceptance criteria acceptance ownership
Authority defines who may execute work and who may judge that the acceptance criteria have been met.
- Task graph requires Acceptance criteria
Integration points in a task graph need acceptance checks that cover the combined behavior.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (2)
- Acceptance criteria: connections
Acceptance criteria and its 6 neighboring concepts. Labels state the authored relationships.
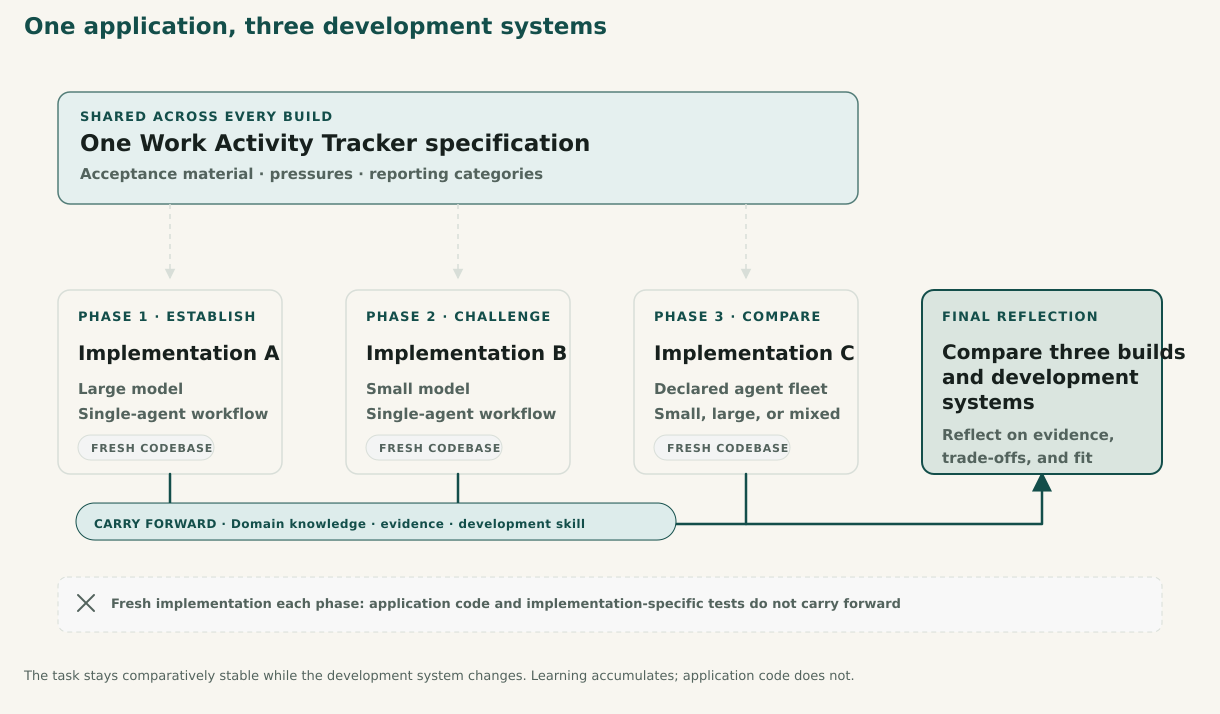
- One application, three development systems
The task stays comparatively stable while the development system changes. Learning accumulates; application code does not.
Follow the idea
Explore through a course task (6)
- Move a prototype into shared use
A working CSV exporter is ready for a demo. What would make it ready for a team's weekly report?
- Challenge an explanation
An agent says a recorder prevents duplicate events after restart. Predict the behavior and test its claim.
- Compare evidence for an agent repair
Saving an event reports success, but the list stays unchanged. Compare task feedback, runtime logs, and a diagnostic brief.
- Follow a fix into running systems
A release succeeds and every health check passes. Decide what the runtime inventory still requires you to investigate.
- Probe an API with temporary clients
A generated CSV client reports success but exports two rows. Design independent checks for a fixed paginated event feed.
- Examine a confident classification
Twenty valid classifications report 90% confidence. Examine the evidence before using that score to route work.
- Fleets: authority and acceptance
Assign acceptance before parallel work begins.
- Webernetes: shared behavioral tests
Test generated behavior against a reference.
Connect the concepts
- Acceptance criteria define outcomes for Loop engineering
Acceptance criteria define the result a loop should pursue. A stop condition can also terminate an unsuccessful run at its budget or escalation boundary.
- Goodhart's Law Acceptance criteria outcome checks
Acceptance criteria help check the intended outcome when a convenient proxy metric becomes a target.
- Acceptance criteria define grading for Agent evaluation
An evaluation grader must assess the declared task and invariants rather than hidden acceptance assumptions.
- Project harness provides evidence for Acceptance criteria
Harness checks provide repeatable evidence for acceptance criteria, while a named owner remains accountable for acceptance.
- Action authorization Acceptance criteria acceptance ownership
Authority defines who may execute work and who may judge that the acceptance criteria have been met.
- Task graph requires Acceptance criteria
Integration points in a task graph need acceptance checks that cover the combined behavior.
Action authorizationDevelopment The permission granted to an actor to propose, prepare, or execute a decision or action within stated limits. Explore concept Group member
Development
Action authorization
- Definition
- The permission granted to an actor to propose, prepare, or execute a decision or action within stated limits.
- Usage in this book
- The book also calls this action authority. Authorization concerns permission to act; accountability concerns ownership of the consequences. Keep both separate from which stored state is authoritative.
- Assumptions
- Name who may act and who remains accountable for the outcome. Separate holding credentials, being authorized to act, and being contained by the environment. Reading untrusted material does not grant it authority.
- Worked example
- An implementation agent may edit a worktree and run tests, but may only prepare a release. A named maintainer authorizes the release and owns acceptance of its behavior.
- Common mistake
- Access to a tool implies permission for every action it supports. Credentials, action approval, and containment are different controls.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Action authorization · 7 connections
Read the relationships
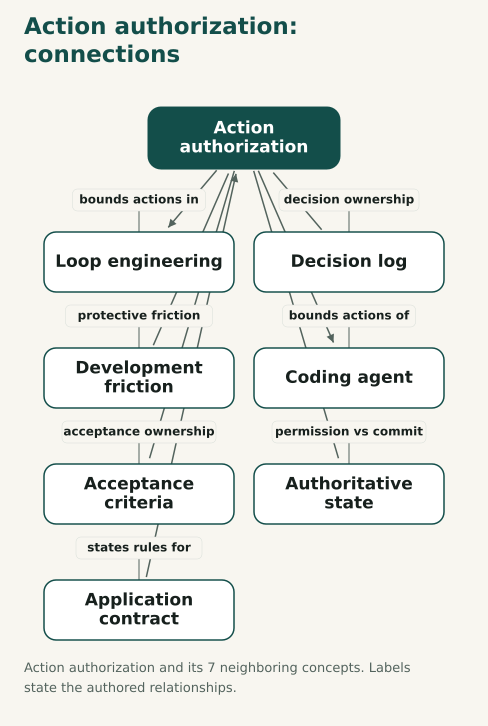
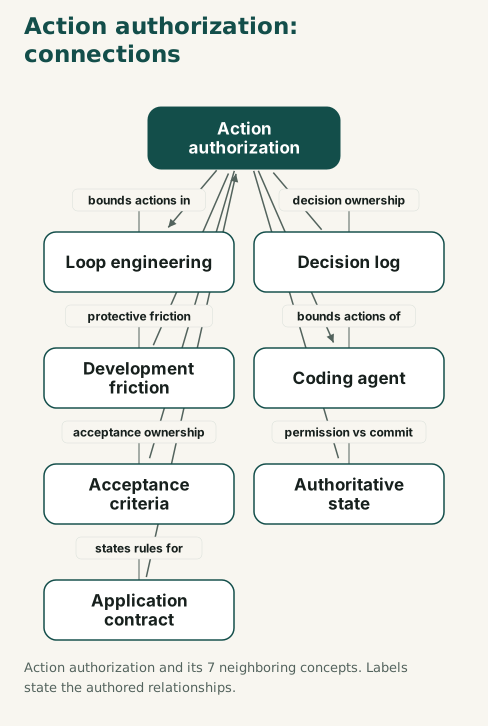
- Action authorization bounds actions in Loop engineering
A loop may continue only within the granted action authority; starting another iteration or run does not expand permissions.
- Decision log Action authorization decision ownership
A proposed record does not grant action authority; acceptance needs a named owner, and the record's status must distinguish intent from implementation.
- Development friction Action authorization protective friction
Explicit ownership reduces coordination ambiguity; authorization and release gates can remain protective friction when they control a named risk.
- Action authorization bounds actions of Coding agent
An agent's ability to invoke a tool must be bounded by the authority granted for the task.
- Action authorization Acceptance criteria acceptance ownership
Authority defines who may execute work and who may judge that the acceptance criteria have been met.
- Action authorization Authoritative state permission vs commit
Action authorization asks who may execute an operation; authoritative state establishes its committed outcome and the boundary responsible for preserving it. An authorized attempt can still fail to commit.
- Application contract states rules for Action authorization
An application contract specifies which actors may invoke an operation and which boundary enforces that permission. A workspace handle or tool credential alone does not authorize every action.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (4)
- Action authorization: connections
Action authorization and its 7 neighboring concepts. Labels state the authored relationships.
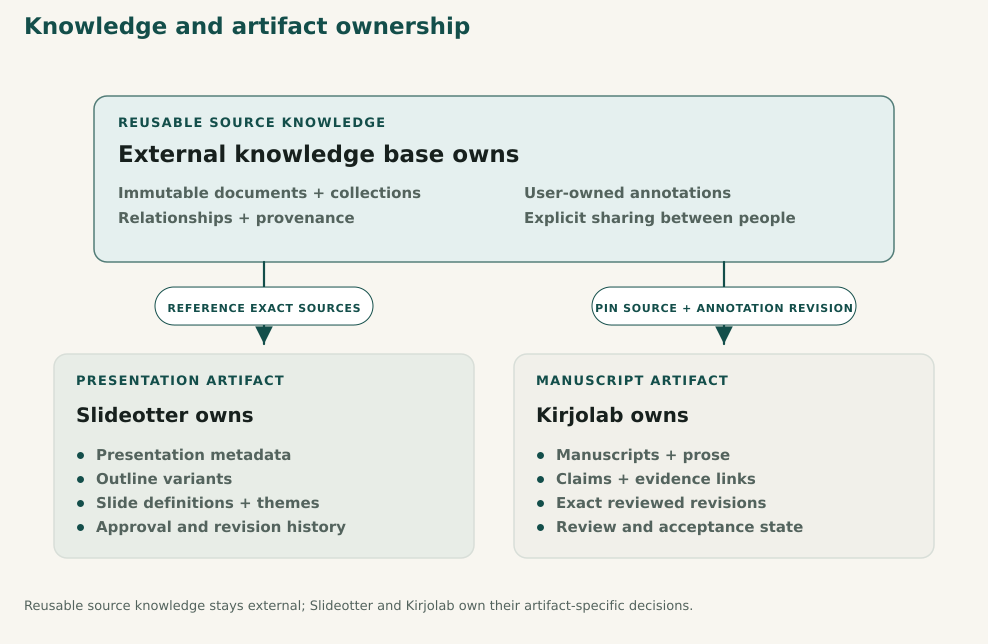
- Knowledge and artifact ownership
Reusable source knowledge stays external; Slideotter and Kirjolab own their artifact-specific decisions.
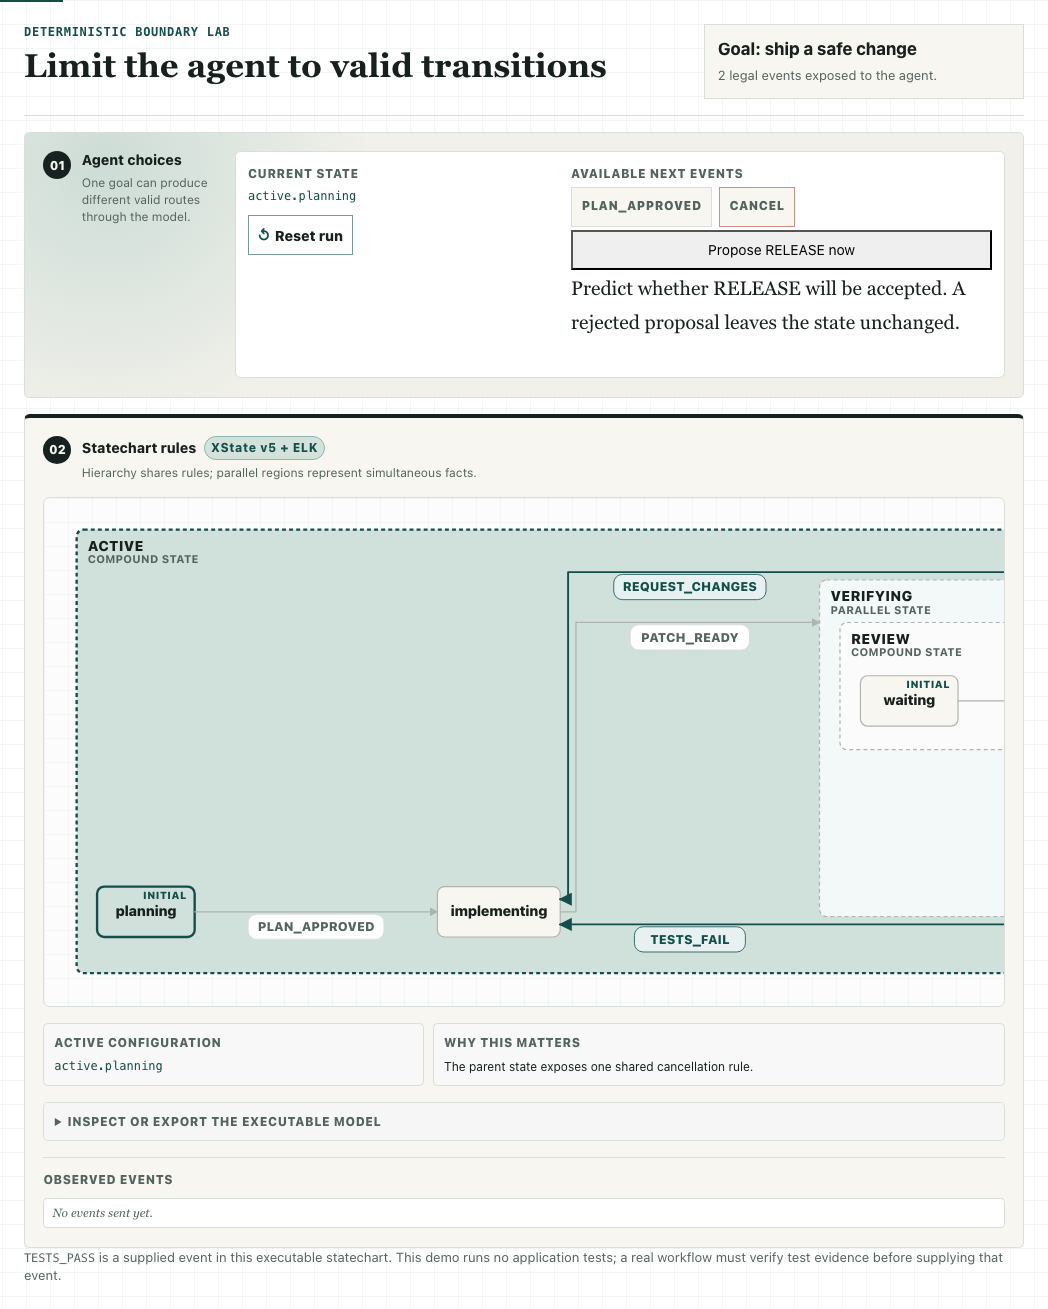
- Deterministic boundary lab
Follow accepted and rejected transitions through a delivery statechart.
Predict first. Which state or guard should prevent the next proposed action, and why?
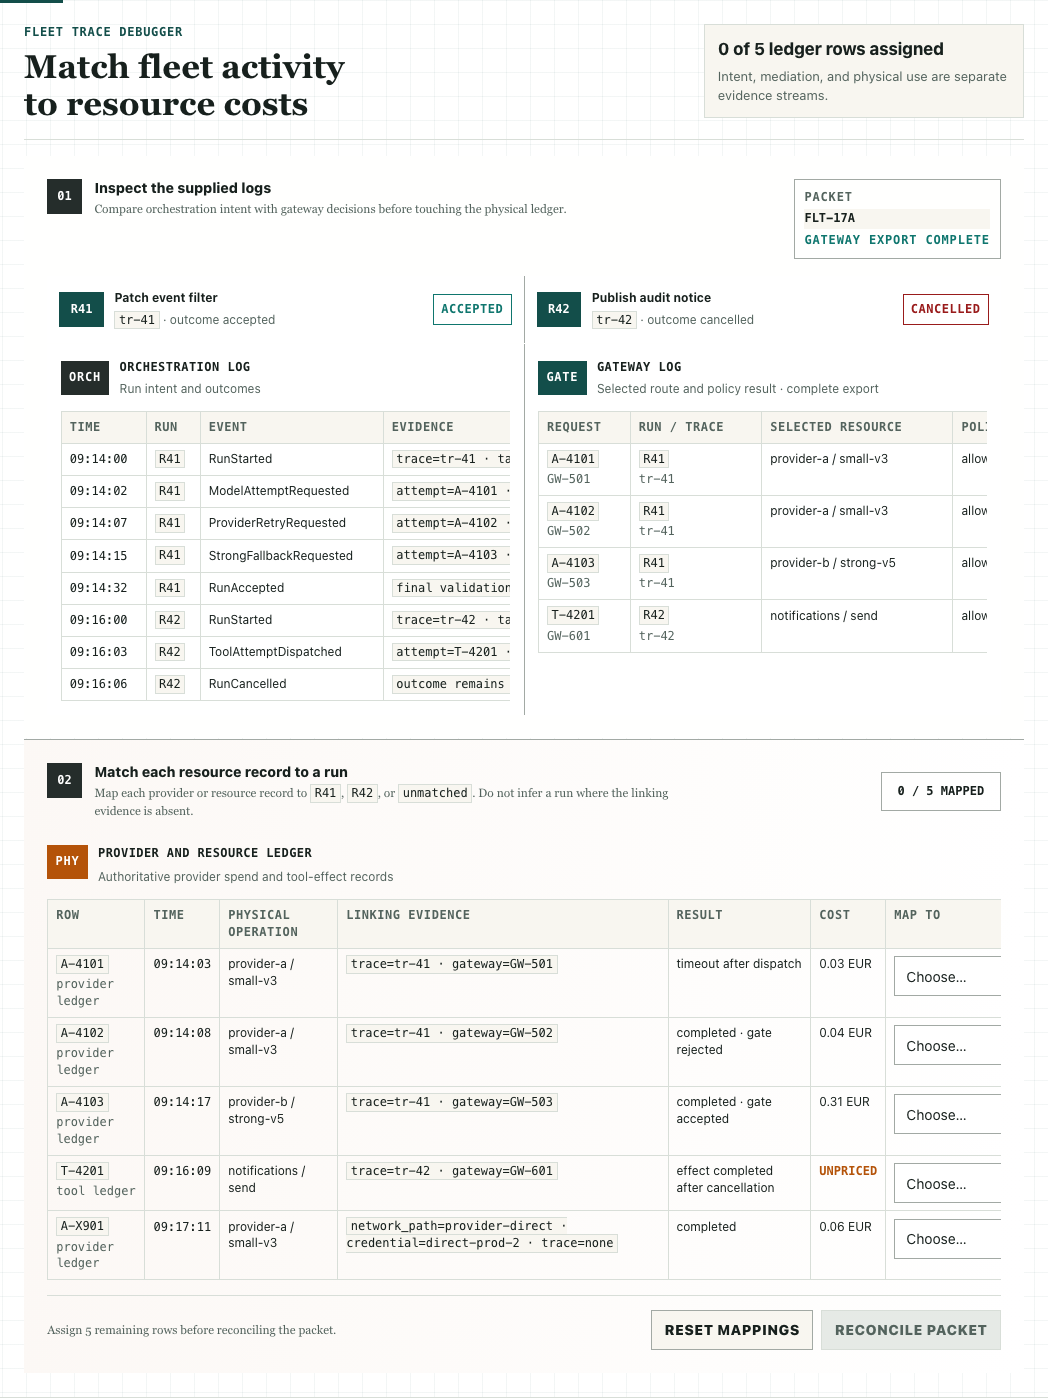
- Fleet trace debugger
Reconcile orchestration intent, gateway decisions, and the physical execution ledger.
Predict first. Which records prove execution, and which express only an intended or authorized action?
Follow the idea
Explore through a course task (3)
- Move a prototype into shared use
A working CSV exporter is ready for a demo. What would make it ready for a team's weekly report?
- Probe an API with temporary clients
A generated CSV client reports success but exports two rows. Design independent checks for a fixed paginated event feed.
- Examine a confident classification
Twenty valid classifications report 90% confidence. Examine the evidence before using that score to route work.
- Development: assign authority
Make execution and acceptance ownership explicit.
- Appendix D: separate security controls
Distinguish access, authorization, and containment.
Connect the concepts
- Action authorization bounds actions in Loop engineering
A loop may continue only within the granted action authority; starting another iteration or run does not expand permissions.
- Decision log Action authorization decision ownership
A proposed record does not grant action authority; acceptance needs a named owner, and the record's status must distinguish intent from implementation.
- Development friction Action authorization protective friction
Explicit ownership reduces coordination ambiguity; authorization and release gates can remain protective friction when they control a named risk.
- Action authorization bounds actions of Coding agent
An agent's ability to invoke a tool must be bounded by the authority granted for the task.
- Action authorization Acceptance criteria acceptance ownership
Authority defines who may execute work and who may judge that the acceptance criteria have been met.
- Action authorization Authoritative state permission vs commit
Action authorization asks who may execute an operation; authoritative state establishes its committed outcome and the boundary responsible for preserving it. An authorized attempt can still fail to commit.
- Application contract states rules for Action authorization
An application contract specifies which actors may invoke an operation and which boundary enforces that permission. A workspace handle or tool credential alone does not authorize every action.
Admission and backpressureOperations Policies that bound admitted work or communicate downstream inability to keep up, preserving a declared service goal under pressure. Explore concept Group member
Operations
Admission and backpressure
- Definition
- Policies that bound admitted work or communicate downstream inability to keep up, preserving a declared service goal under pressure.
- Assumptions
- Specify capacity, rejection or slowing behavior, caller obligations, and recovery. Rejected work must stay visible in the outcome accounting.
- Worked example
- A full event queue rejects optional submissions with a retry policy instead of accumulating unbounded waiting and exhausting memory.
- Common mistake
- Rejecting load means the design cannot scale, or a queue is unlimited capacity. Bounded admission can protect useful work while capacity is restored.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Admission and backpressure · 3 connections
Read the relationships
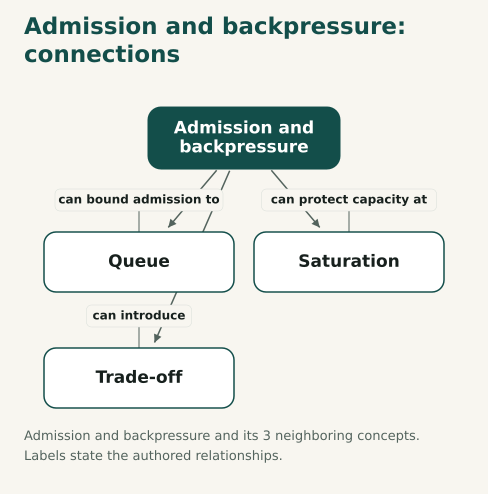
- Admission and backpressure can bound admission to Queue
A bounded queue requires a policy for slowing or rejecting new work when downstream capacity cannot keep up.
- Admission and backpressure can protect capacity at Saturation
Admission controls can protect a saturated boundary while making rejected or delayed work explicit.
- Admission and backpressure can introduce Trade-off
Bounding admission can preserve useful service while sacrificing immediate acceptance of some work.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (2)
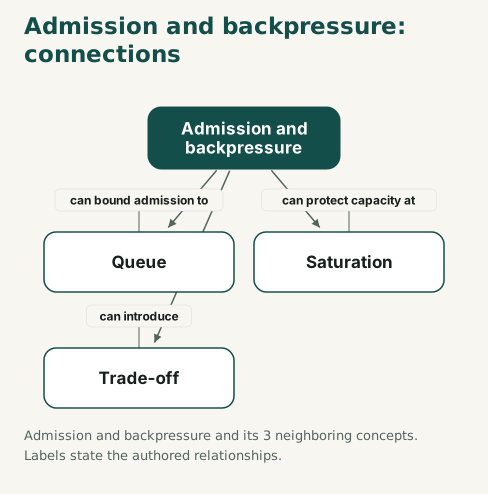
- Admission and backpressure: connections
Admission and backpressure and its 3 neighboring concepts. Labels state the authored relationships.
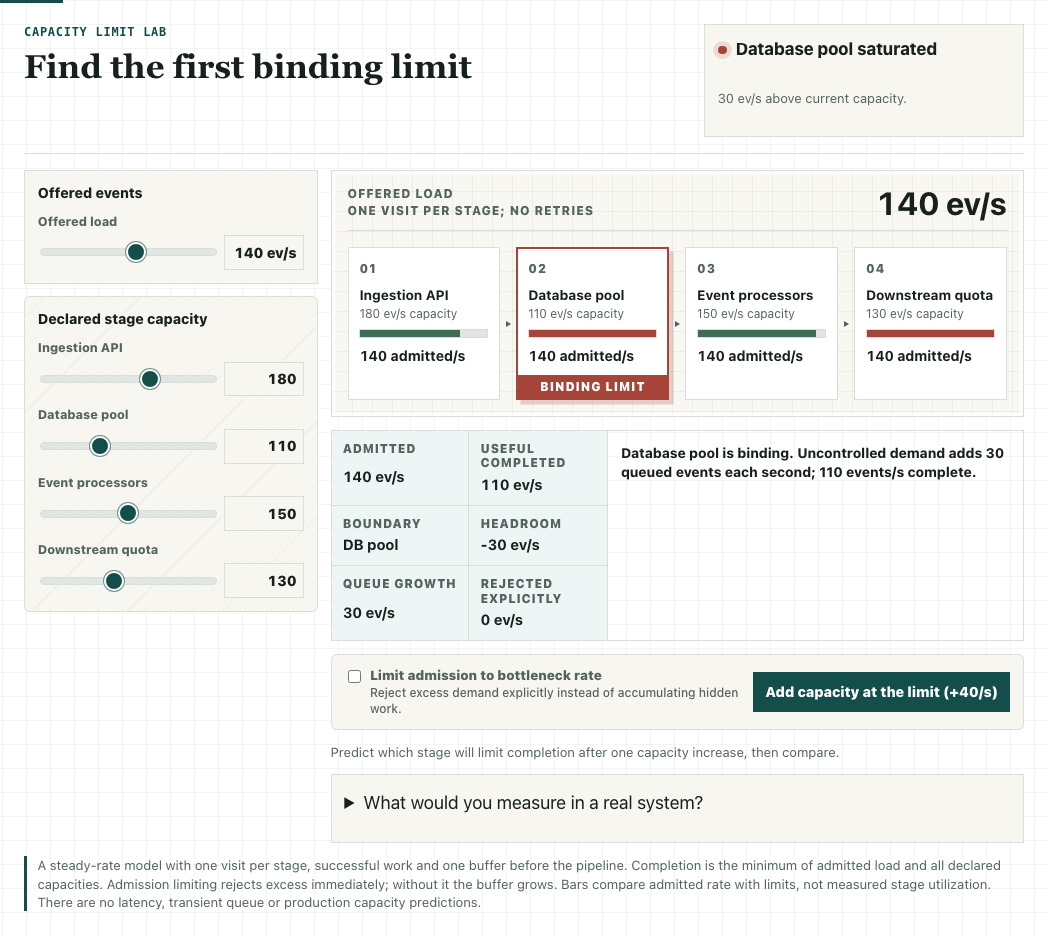
- Saturation boundary lab
Compare offered, admitted and completed event rates and move the binding limit.
Predict first. If you raise only the database capacity, which stage will limit completion next?
Follow the idea
- Scaling: response guide
Match the intervention to the pressured boundary.
- Pressure: recovery architecture
Plan how overload and backlog drain end.
Connect the concepts
- Admission and backpressure can bound admission to Queue
A bounded queue requires a policy for slowing or rejecting new work when downstream capacity cannot keep up.
- Admission and backpressure can protect capacity at Saturation
Admission controls can protect a saturated boundary while making rejected or delayed work explicit.
- Admission and backpressure can introduce Trade-off
Bounding admission can preserve useful service while sacrificing immediate acceptance of some work.
Find this idea across the book (2)
Agent evaluationEvidence A declared task-and-grading procedure for assessing an agent workflow's capability, regression behavior, cost, and reliability. Explore concept Group member
Evidence
Agent evaluation
- Definition
- A declared task-and-grading procedure for assessing an agent workflow's capability, regression behavior, cost, and reliability.
- Assumptions
- Separate the evaluated agent harness from the evaluation harness. Preserve task inputs, served configuration, trial rules, graders, and failed attempts.
- Worked example
- Run a contract-change task with fixed acceptance checks across repeated trials, recording correctness, retries, tokens, and reviewer minutes.
- Common mistake
- A pass on one task proves general reliability. Task selection, graders, environment, and trial variability limit the claim.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Agent evaluation · 6 connections
Read the relationships
- Agent evaluation assesses outcomes of Loop engineering
Representative tasks and independent acceptance evidence can assess a loop change while accounting for retries, resource cost, and human correction.
- Benchmark protocol Agent evaluation shared protocol
Benchmarks and agent evaluations both require declared tasks, boundaries, outcome criteria, and failure accounting.
- Agent evaluation estimates Reliability
Repeated agent evaluation distinguishes a successful example from evidence about success frequency and uncertainty.
- Acceptance criteria define grading for Agent evaluation
An evaluation grader must assess the declared task and invariants rather than hidden acceptance assumptions.
- Project harness supplies checks for Agent evaluation
The project harness supplies reusable checks and setup, while the evaluation harness provisions and scores trials.
- Agent evaluation can include Maintainability assessment
An agent evaluation can include next-change tasks to assess maintainability beyond initial task success.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (1)
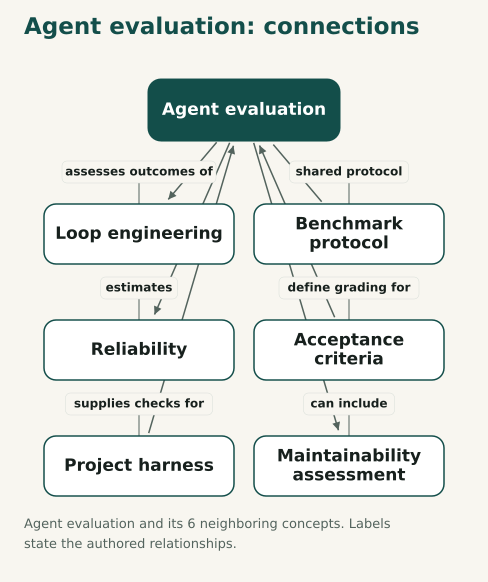
- Agent evaluation: connections
Agent evaluation and its 6 neighboring concepts. Labels state the authored relationships.
Follow the idea
Explore through a course task (3)
- Compare evidence for an agent repair
Saving an event reports success, but the list stays unchanged. Compare task feedback, runtime logs, and a diagnostic brief.
- Probe an API with temporary clients
A generated CSV client reports success but exports two rows. Design independent checks for a fixed paginated event feed.
- Examine a confident classification
Twenty valid classifications report 90% confidence. Examine the evidence before using that score to route work.
- Appendix A: anatomy of an eval
Separate execution, environment, and grading.
- Modern Web Guidance: evaluate the guidance
Check whether a capability improves actual task outcomes.
Connect the concepts
- Agent evaluation assesses outcomes of Loop engineering
Representative tasks and independent acceptance evidence can assess a loop change while accounting for retries, resource cost, and human correction.
- Benchmark protocol Agent evaluation shared protocol
Benchmarks and agent evaluations both require declared tasks, boundaries, outcome criteria, and failure accounting.
- Agent evaluation estimates Reliability
Repeated agent evaluation distinguishes a successful example from evidence about success frequency and uncertainty.
- Acceptance criteria define grading for Agent evaluation
An evaluation grader must assess the declared task and invariants rather than hidden acceptance assumptions.
- Project harness supplies checks for Agent evaluation
The project harness supplies reusable checks and setup, while the evaluation harness provisions and scores trials.
- Agent evaluation can include Maintainability assessment
An agent evaluation can include next-change tasks to assess maintainability beyond initial task success.
Find this idea across the book (4)
Agent fleetDevelopment Several agents working under an explicit task, coordination, authority, integration, and acceptance arrangement. Explore concept Group member
Development
Agent fleet
- Definition
- Several agents working under an explicit task, coordination, authority, integration, and acceptance arrangement.
- Usage in this book
- Multi-agent system is the established broader term. Agent fleet names the book's coordinated coding-agent arrangement within a development workflow. A multi-agent system need not use LLMs, pursue a shared goal, or have the integration and acceptance structure described here.
- Assumptions
- Useful parallelism depends on separable work and available integration capacity. Count accepted changes and coordination cost, not only simultaneous agents.
- Worked example
- One agent changes the event contract, another updates consumers after that contract is fixed, and a reviewer tests their integrated behavior.
- Common mistake
- More agents guarantee more useful output. Shared dependencies and sequential review can erase the benefit.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Agent fleet · 6 connections
Read the relationships
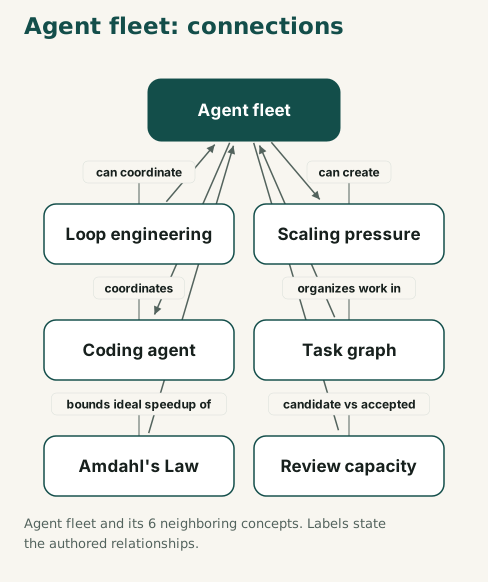
- Loop engineering can coordinate Agent fleet
A loop can assign and verify work across a fleet, but one agent can also operate inside a designed loop. Delegation adds coordination and integration obligations.
- Agent fleet can create Scaling pressure
Adding contributors or agents increases coordination pressure as well as possible parallelism.
- Agent fleet coordinates Coding agent
A fleet extends one agent's execution loop with explicit coordination, integration, and acceptance.
- Task graph organizes work in Agent fleet
A fleet's task graph states what can proceed independently and where contracts or integration impose order.
- Amdahl's Law bounds ideal speedup of Agent fleet
Amdahl's Law provides an ideal bound when part of a fleet's fixed workload remains sequential.
- Agent fleet Review capacity candidate vs accepted
Additional agents can increase candidate output faster than human review can accept it.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (4)
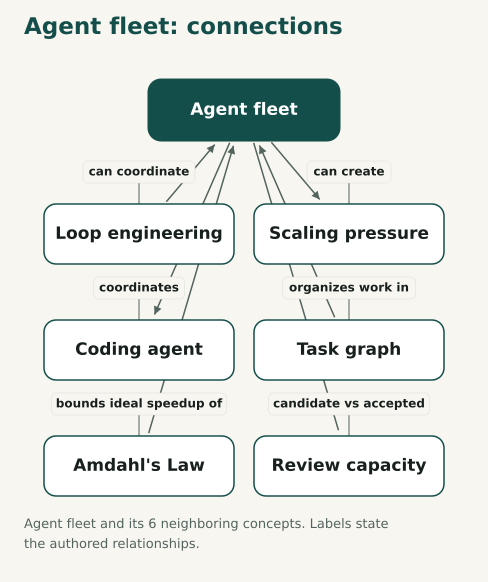
- Agent fleet: connections
Agent fleet and its 6 neighboring concepts. Labels state the authored relationships.
- One application, three development systems
The task stays comparatively stable while the development system changes. Learning accumulates; application code does not.
- Fleet trace debugger
Reconcile orchestration intent, gateway decisions, and the physical execution ledger.
Predict first. Which records prove execution, and which express only an intended or authorized action?
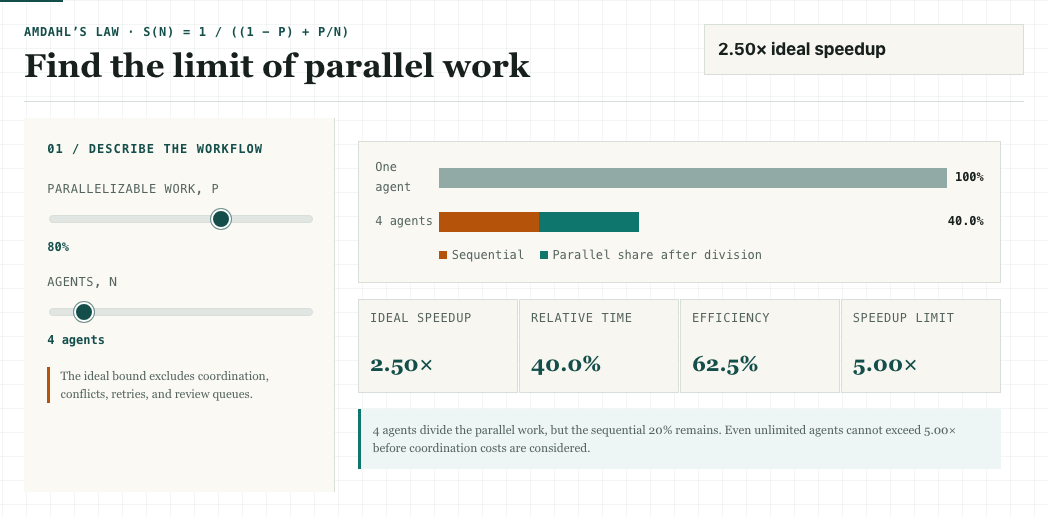
- Sequential work bound
Inspect the ideal speedup bound when part of a fixed workload stays sequential.
Predict first. With 80% parallelizable work, will increasing from four to eight agents double speedup?
Follow the idea
Explore through a course task (1)
- Vary human work in progress
Keep the same worker limit while changing how many unfinished changes enter the workflow. Plan a bounded comparison.
- Fleets: choose a coordination structure
Choose a structure that fits the work and integration capacity.
- Compare: implementation C
Declare and evaluate a fleet in the project.
Connect the concepts
- Loop engineering can coordinate Agent fleet
A loop can assign and verify work across a fleet, but one agent can also operate inside a designed loop. Delegation adds coordination and integration obligations.
- Agent fleet can create Scaling pressure
Adding contributors or agents increases coordination pressure as well as possible parallelism.
- Agent fleet coordinates Coding agent
A fleet extends one agent's execution loop with explicit coordination, integration, and acceptance.
- Task graph organizes work in Agent fleet
A fleet's task graph states what can proceed independently and where contracts or integration impose order.
- Amdahl's Law bounds ideal speedup of Agent fleet
Amdahl's Law provides an ideal bound when part of a fleet's fixed workload remains sequential.
- Agent fleet Review capacity candidate vs accepted
Additional agents can increase candidate output faster than human review can accept it.
Find this idea across the book (5)
Amdahl's LawModels For a fixed workload with parallelizable fraction p and n workers, ideal speedup is S(n) = 1 / ((1 − p) + p/n). Explore concept Group member
Models
Amdahl's Law
- Definition
- For a fixed workload with parallelizable fraction p and n workers, ideal speedup is S(n) = 1 / ((1 − p) + p/n). The sequential fraction bounds the gain.
- Assumptions
- Hold the workload and sequential fraction fixed. Assume ideal division of parallel work with no added coordination cost. The result is an upper bound under those assumptions.
- Worked example
- If 80% of baseline work can run in parallel and 20% remains sequential, four workers give ideal speedup 1 / (0.2 + 0.8/4) = 2.5. Even infinitely many workers cannot exceed 5× in this model.
- Common mistake
- Four agents guarantee four times the accepted output. Review or integration that must remain sequential limits fixed-task speedup; added coordination cost can reduce the gain further. Ongoing accepted-change throughput requires its own measurements.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Amdahl's Law · 5 connections
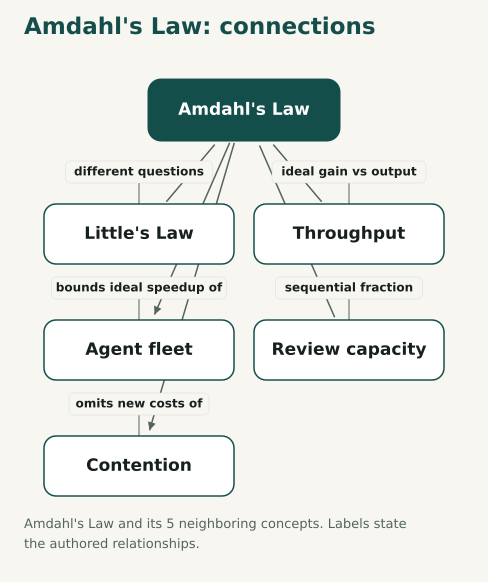
Read the relationships
- Little's Law Amdahl's Law different questions
Little's Law checks stable flow averages; Amdahl's Law bounds ideal fixed-workload parallel speedup.
- Throughput Amdahl's Law ideal gain vs output
An Amdahl speedup bound does not guarantee accepted-change throughput; review, coordination, and correctness still matter.
- Amdahl's Law bounds ideal speedup of Agent fleet
Amdahl's Law provides an ideal bound when part of a fleet's fixed workload remains sequential.
- Review capacity Amdahl's Law sequential fraction
Review or integration that must remain sequential belongs in Amdahl's sequential fraction for a fixed task. A growing review queue asks a separate question about ongoing arrival and completion rates.
- Amdahl's Law omits new costs of Contention
Amdahl's ideal fixed-workload bound omits new contention and coordination costs introduced by parallelism.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (3)
- Amdahl's Law: connections
Amdahl's Law and its 5 neighboring concepts. Labels state the authored relationships.
- Sequential work bound
Inspect the ideal speedup bound when part of a fixed workload stays sequential.
Predict first. With 80% parallelizable work, will increasing from four to eight agents double speedup?
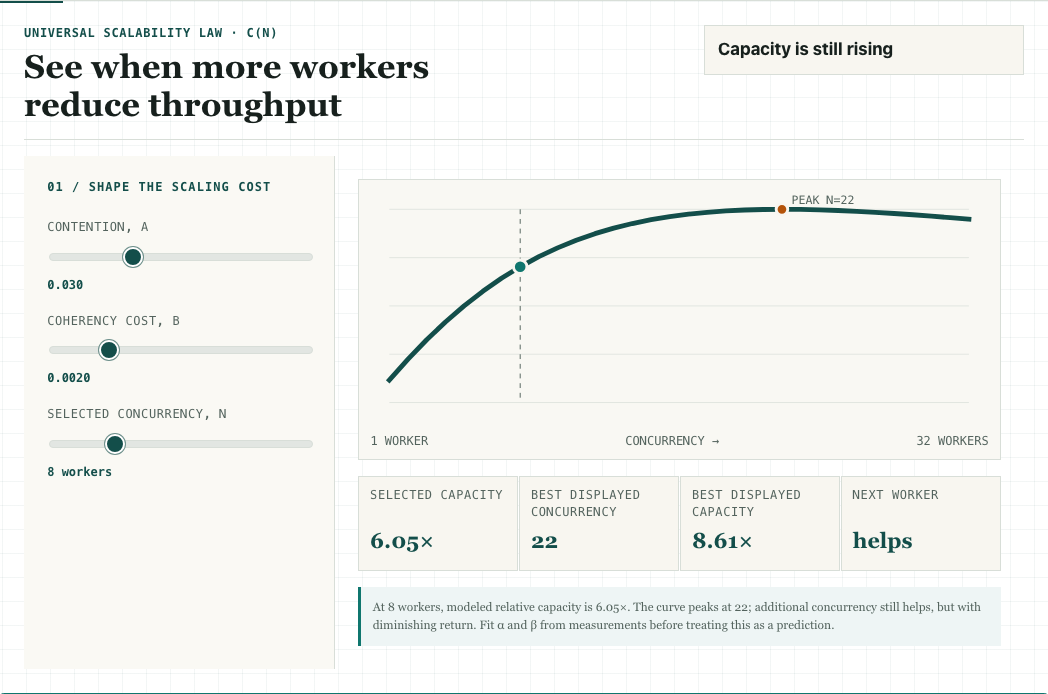
- Contention curve lab
Explore a modeled capacity curve as contention and coherency costs change.
Predict first. Will adding workers always increase capacity when coherency cost is nonzero?
Follow the idea
- Fleets: calculate the sequential bound
Account for integration and review in the workload.
- Scaling: choose between the two laws
Choose a model by the question it can answer.
Connect the concepts
- Little's Law Amdahl's Law different questions
Little's Law checks stable flow averages; Amdahl's Law bounds ideal fixed-workload parallel speedup.
- Throughput Amdahl's Law ideal gain vs output
An Amdahl speedup bound does not guarantee accepted-change throughput; review, coordination, and correctness still matter.
- Amdahl's Law bounds ideal speedup of Agent fleet
Amdahl's Law provides an ideal bound when part of a fleet's fixed workload remains sequential.
- Review capacity Amdahl's Law sequential fraction
Review or integration that must remain sequential belongs in Amdahl's sequential fraction for a fixed task. A growing review queue asks a separate question about ongoing arrival and completion rates.
- Amdahl's Law omits new costs of Contention
Amdahl's ideal fixed-workload bound omits new contention and coordination costs introduced by parallelism.
Find this idea across the book (3)
Application contractArchitecture An agreement about observable behavior, valid inputs, outputs, errors, and obligations at an application boundary. Explore concept Group member
Architecture
Application contract
- Definition
- An agreement about observable behavior, valid inputs, outputs, errors, and obligations at an application boundary.
- Assumptions
- Identify consumers, versioning, authority, and compatibility expectations. Contracts include behavior that a type signature alone cannot express.
- Worked example
- POST /events accepts one logical activity with workspace isolation and a declared duplicate policy, regardless of which runtime hosts the handler.
- Common mistake
- A deployment location or matching types fully defines the contract. Timing, retries, errors, and state effects also matter.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
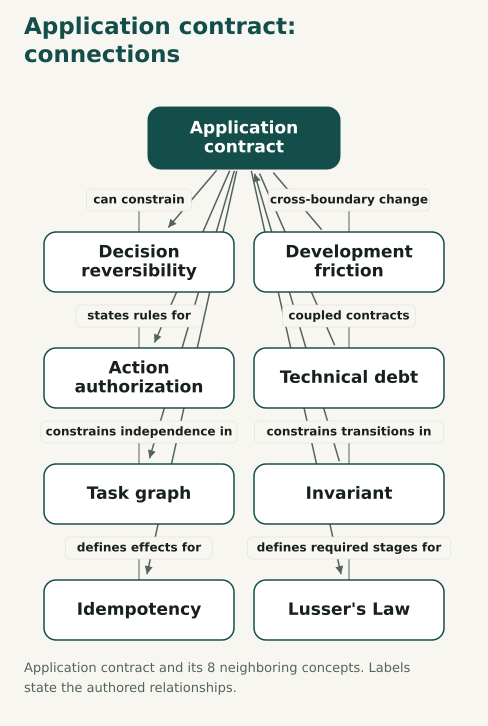
Application contract · 8 connections
Read the relationships
- Application contract can constrain Decision reversibility
An independently deployed consumer relying on a contract can turn a locally editable choice into a hard compatibility commitment.
- Development friction Application contract cross-boundary change
A small feature can create friction as it crosses HTTP, data, cache, and deployment contracts owned at different boundaries.
- Application contract states rules for Action authorization
An application contract specifies which actors may invoke an operation and which boundary enforces that permission. A workspace handle or tool credential alone does not authorize every action.
- Technical debt Application contract coupled contracts
Unclear or tightly coupled contracts can make one local change require coordinated changes elsewhere.
- Application contract constrains independence in Task graph
Task independence depends on compatible shared contracts, not merely separate files.
- Invariant constrains transitions in Application contract
A contract describes valid boundary behavior; invariants state conditions its accepted transitions must preserve.
- Application contract defines effects for Idempotency
The contract names all intended effects against which idempotency is judged. A key-based retry protocol also needs scope, conflict, retention, and outcome rules.
- Application contract defines required stages for Lusser's Law
The reliability chain includes the stages that must succeed to meet the declared end-to-end contract.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (8)
- Application contract: connections
Application contract and its 8 neighboring concepts. Labels state the authored relationships.
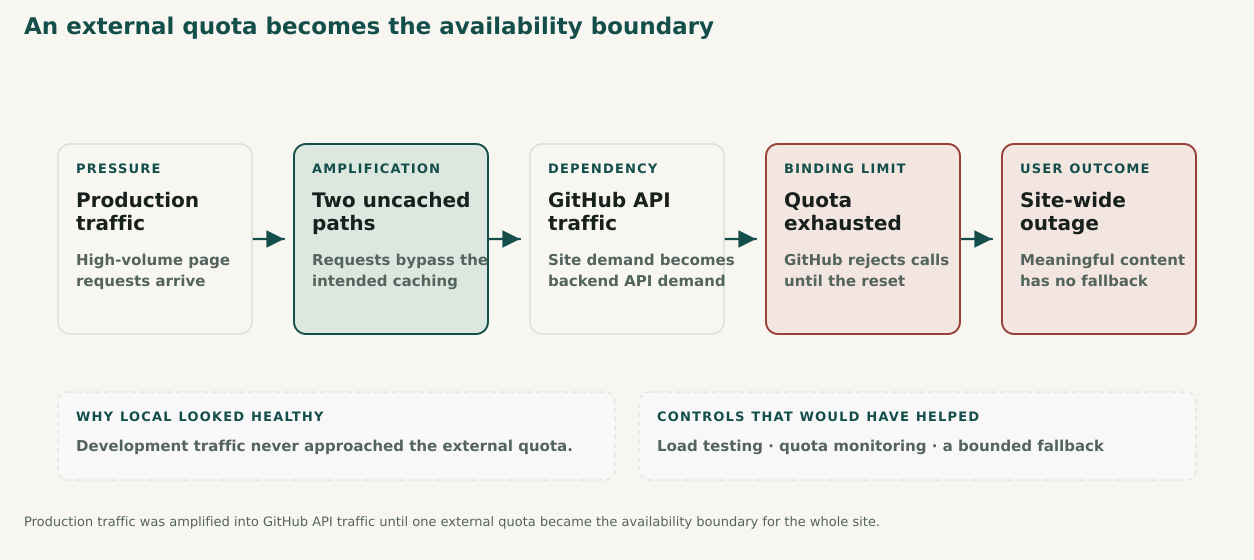
- An external quota becomes the availability boundary
Production traffic was amplified into GitHub API traffic until one external quota became the availability boundary for the whole site.
- Knowledge and artifact ownership
Reusable source knowledge stays external; Slideotter and Kirjolab own their artifact-specific decisions.
- Deterministic boundary lab
Follow accepted and rejected transitions through a delivery statechart.
Predict first. Which state or guard should prevent the next proposed action, and why?
- Cache decision lab
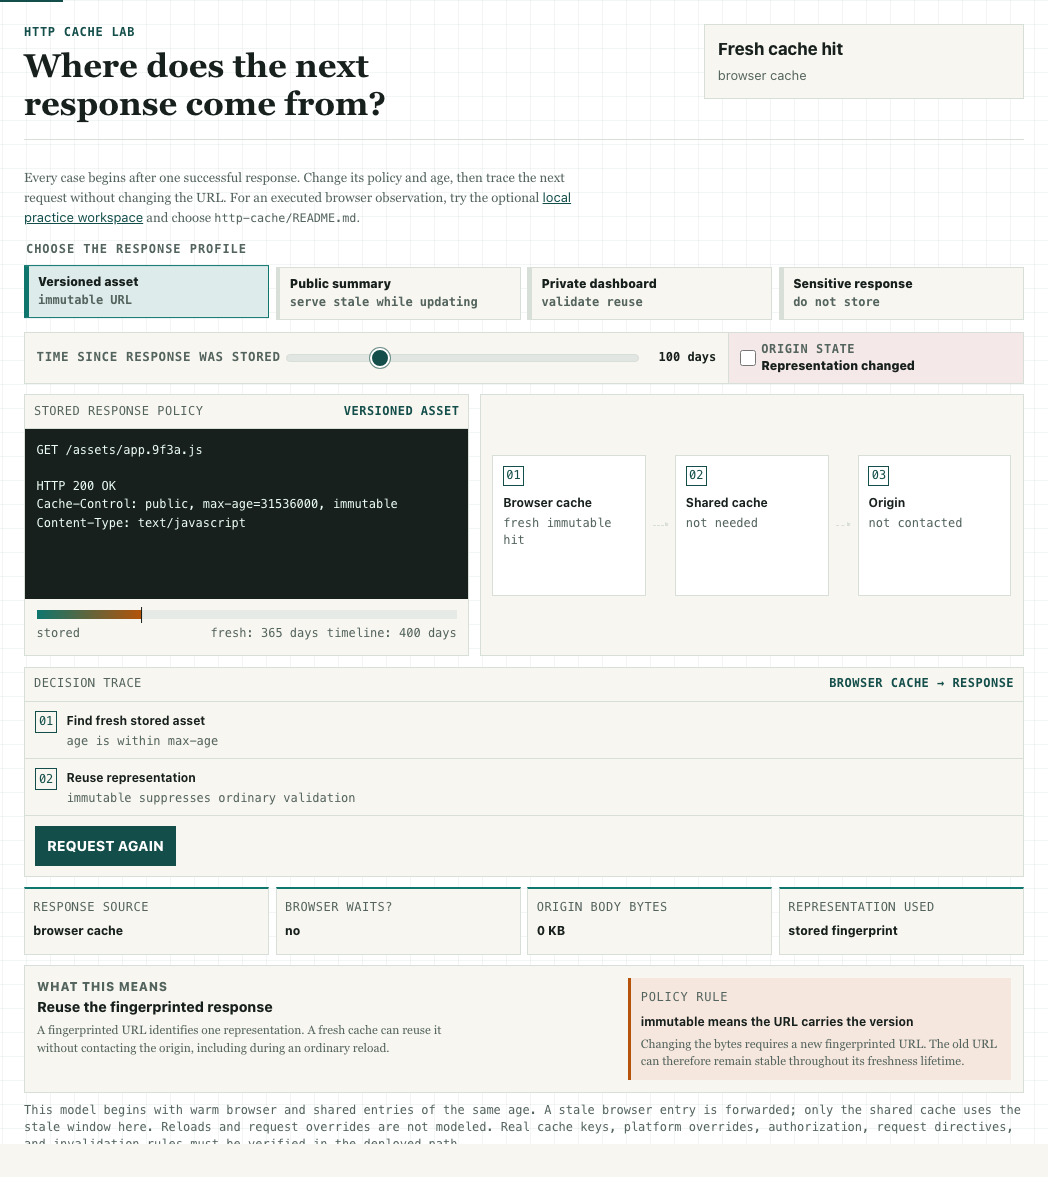
Trace reuse, validation, and stale responses under different HTTP cache policies.
Predict first. Which policy can reuse a response without contacting the origin, and what freshness promise does that make?
- Web architecture lens
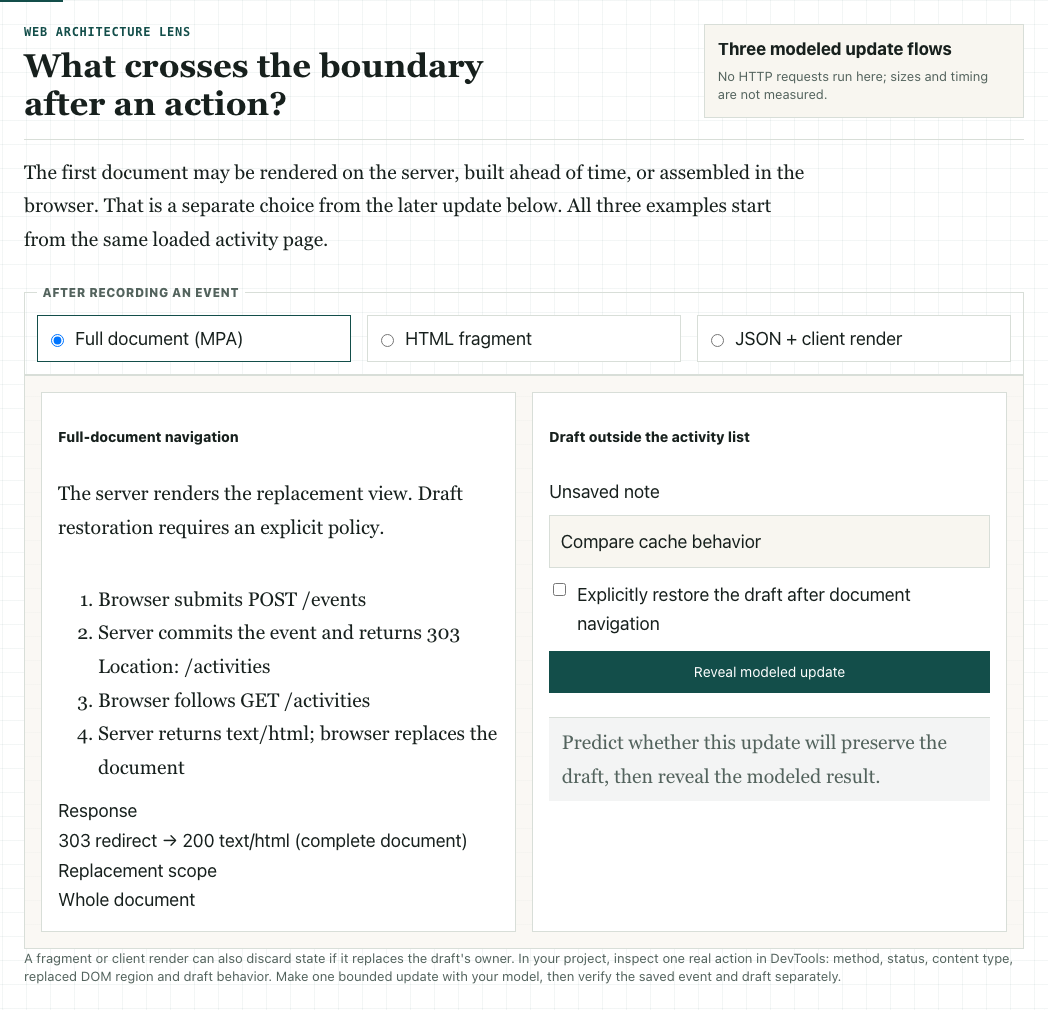
Compare page navigation, HTML fragments, and browser-built views for the same operation.
Predict first. Which local state might be lost when an action causes a full-page navigation?
- Reliability chain lab
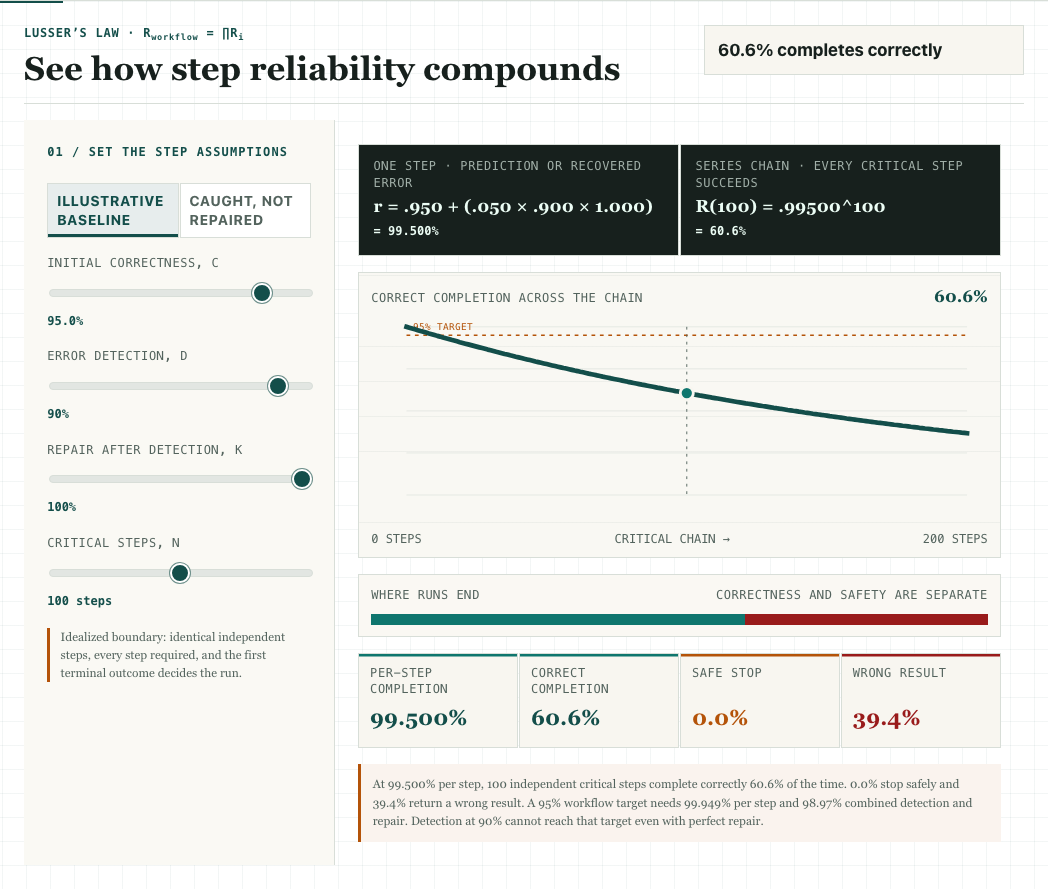
Calculate a required-stage chain's reliability under explicit independence and repair assumptions.
Predict first. How will doubling the required step count affect end-to-end success if per-step behavior stays fixed?
- Orchestration control loop
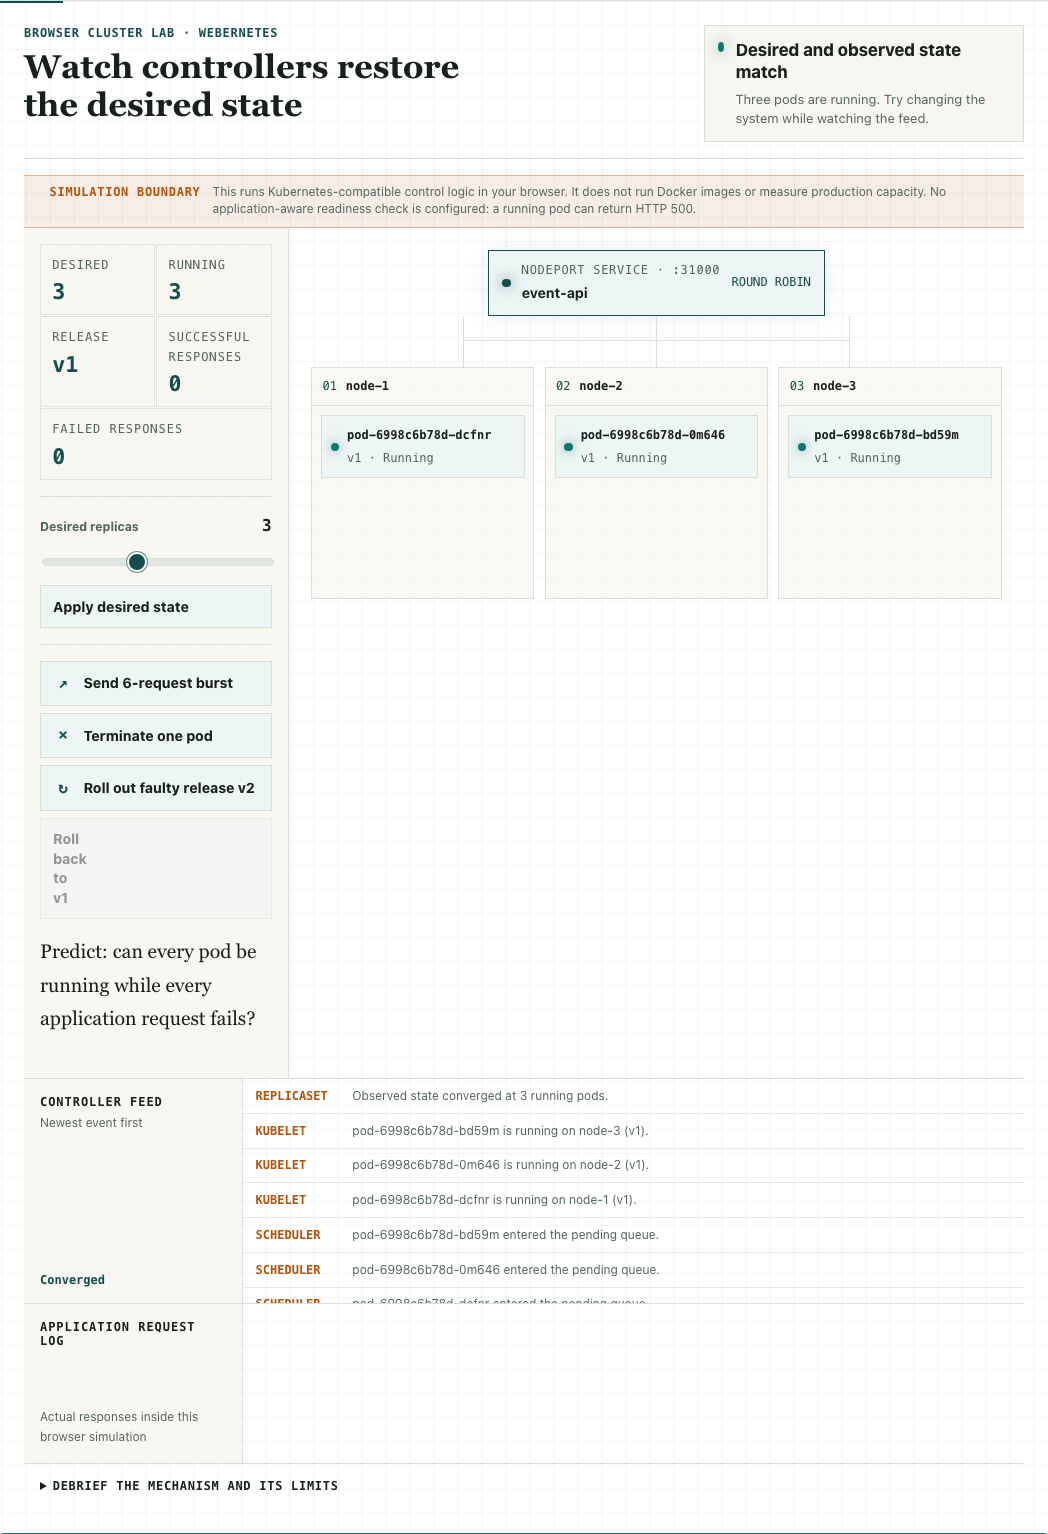
Follow controller actions that reconcile observed replicas with desired state.
Predict first. After losing a replica, what discrepancy should the controller observe and what action should follow?
Follow the idea
Explore through a course task (1)
- Probe an API with temporary clients
A generated CSV client reports success but exports two rows. Design independent checks for a fixed paginated event feed.
- Architecture: contracts outlive deployment
Separate behavior from where execution happens.
- Appendix C: executable HTTP contracts
Make boundary expectations testable.
Connect the concepts
- Application contract can constrain Decision reversibility
An independently deployed consumer relying on a contract can turn a locally editable choice into a hard compatibility commitment.
- Development friction Application contract cross-boundary change
A small feature can create friction as it crosses HTTP, data, cache, and deployment contracts owned at different boundaries.
- Application contract states rules for Action authorization
An application contract specifies which actors may invoke an operation and which boundary enforces that permission. A workspace handle or tool credential alone does not authorize every action.
- Technical debt Application contract coupled contracts
Unclear or tightly coupled contracts can make one local change require coordinated changes elsewhere.
- Application contract constrains independence in Task graph
Task independence depends on compatible shared contracts, not merely separate files.
- Invariant constrains transitions in Application contract
A contract describes valid boundary behavior; invariants state conditions its accepted transitions must preserve.
- Application contract defines effects for Idempotency
The contract names all intended effects against which idempotency is judged. A key-based retry protocol also needs scope, conflict, retention, and outcome rules.
- Application contract defines required stages for Lusser's Law
The reliability chain includes the stages that must succeed to meet the declared end-to-end contract.
Authoritative stateArchitecture The state treated as the source of truth for a named domain outcome, together with the boundary responsible for committing and preserving it. Explore concept Group member
Architecture
Authoritative state
- Definition
- The state treated as the source of truth for a named domain outcome, together with the boundary responsible for committing and preserving it.
- Usage in this book
- The book also uses state authority for the boundary that owns authoritative state. Authority terminology varies by system; identify the particular record and owner rather than assuming every domain has one central store.
- Assumptions
- Name which state is authoritative and how copies catch up. Permission to submit an action does not establish that it committed; a successful response or rebuilt view also needs evidence of the authoritative outcome.
- Worked example
- The event store commits one activity. A delayed cached feed may show none yet; rebuilding the feed must not create a second activity.
- Common mistake
- Every copy is equally authoritative, or stateless handlers remove state. Authority still exists somewhere in the system.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Authoritative state · 5 connections
Read the relationships
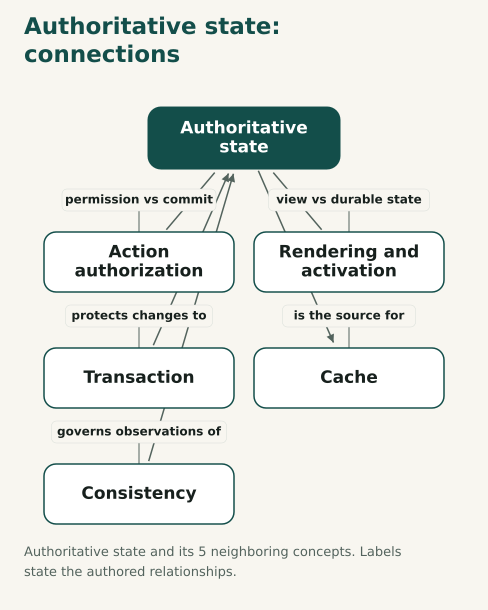
- Action authorization Authoritative state permission vs commit
Action authorization asks who may execute an operation; authoritative state establishes its committed outcome and the boundary responsible for preserving it. An authorized attempt can still fail to commit.
- Rendering and activation Authoritative state view vs durable state
Rendering a representation must remain distinct from committing the durable action it displays.
- Transaction protects changes to Authoritative state
Transactions protect related changes at the durable authority under the store's actual guarantees.
- Authoritative state is the source for Cache
A cache is a controlled copy whose freshness and invalidation depend on the authoritative state.
- Consistency governs observations of Authoritative state
Consistency promises describe how consumers observe authoritative changes through concurrency and copies.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (8)
- Authoritative state: connections
Authoritative state and its 5 neighboring concepts. Labels state the authored relationships.
- Deterministic boundary lab
Follow accepted and rejected transitions through a delivery statechart.
Predict first. Which state or guard should prevent the next proposed action, and why?
- ACID transaction lab
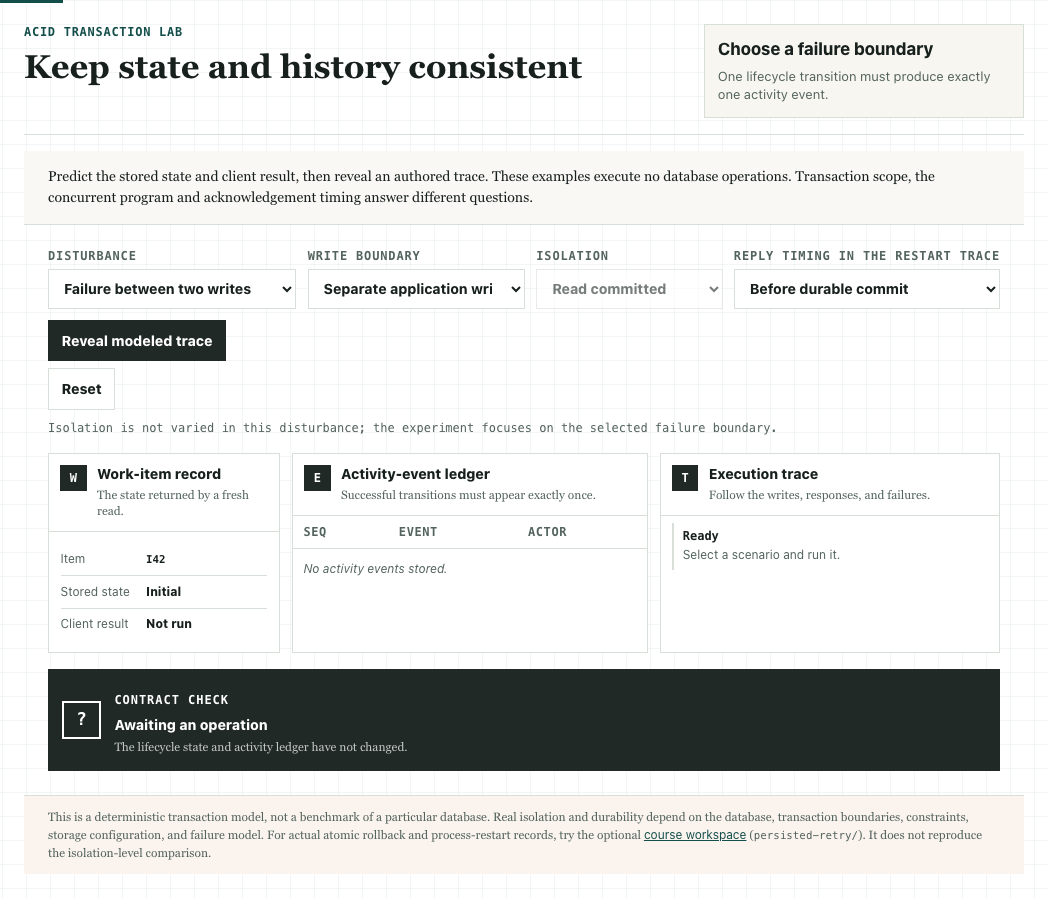
Inspect lifecycle and ledger records under failed writes, concurrency, and restart.
Predict first. Which invariant could fail between two application-managed writes?
- Web architecture lens
Compare page navigation, HTML fragments, and browser-built views for the same operation.
Predict first. Which local state might be lost when an action causes a full-page navigation?
- Fleet trace debugger
Reconcile orchestration intent, gateway decisions, and the physical execution ledger.
Predict first. Which records prove execution, and which express only an intended or authorized action?
- Orchestration control loop
Follow controller actions that reconcile observed replicas with desired state.
Predict first. After losing a replica, what discrepancy should the controller observe and what action should follow?
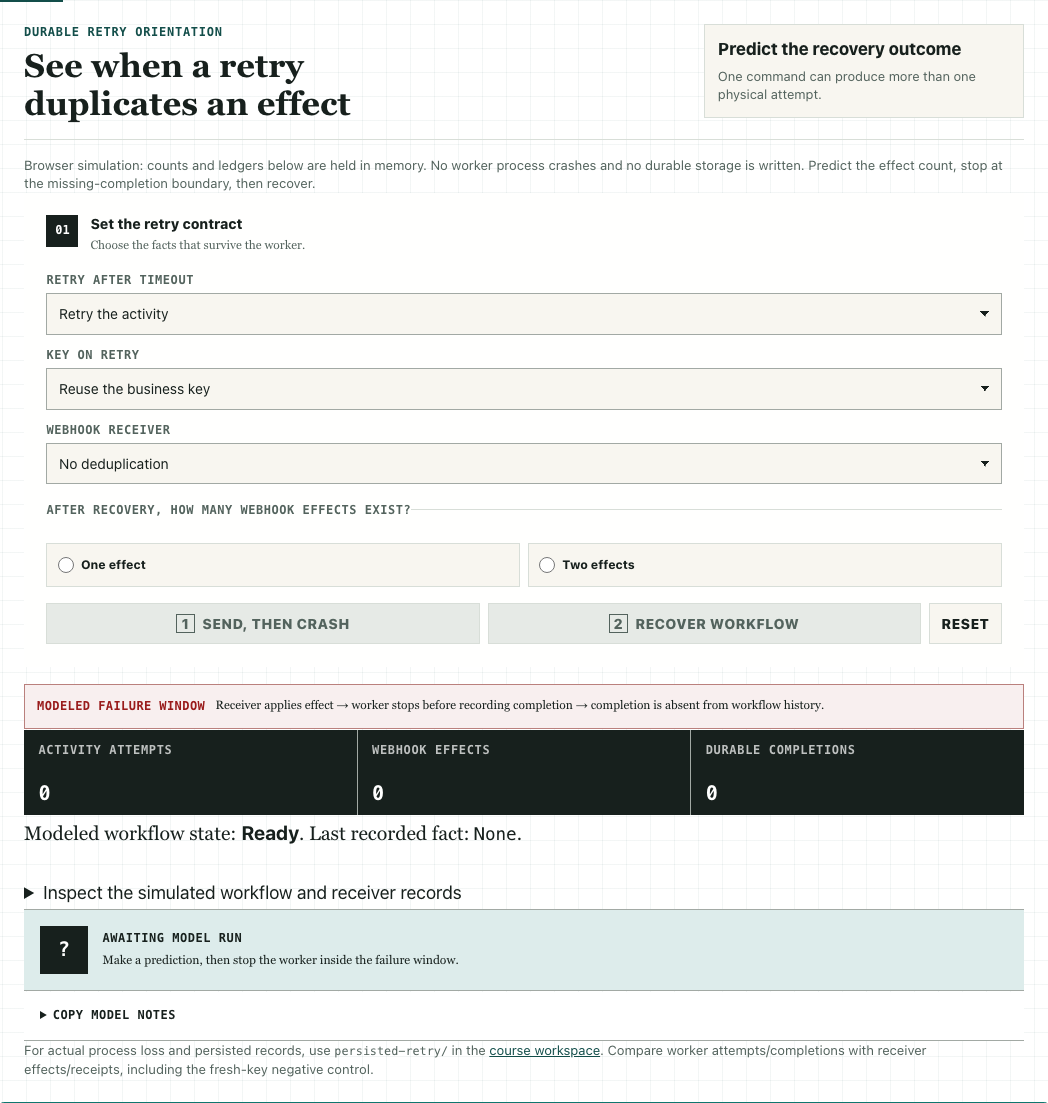
- Durable effect retry lab
Stop a worker after an external effect but before its completion enters durable history.
Predict first. If the receiver applied the effect but completion was not recorded, what could make a retry apply it twice?
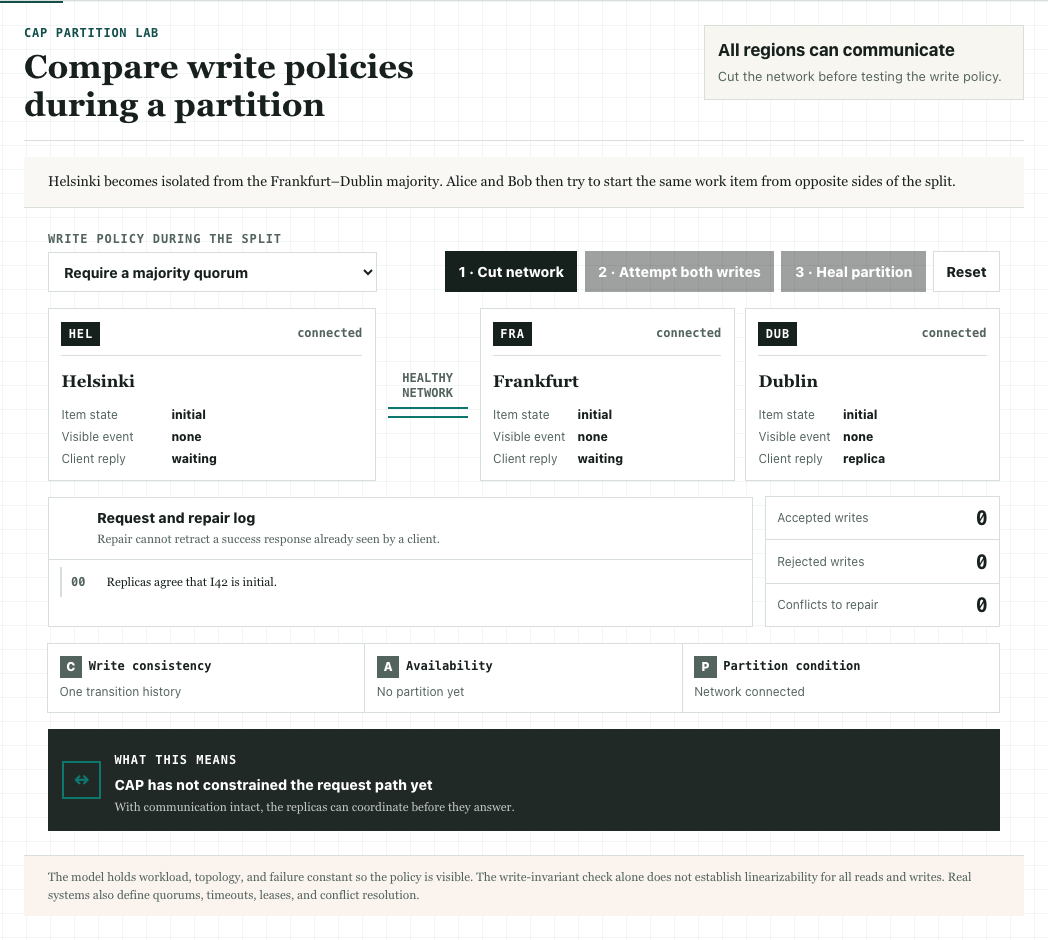
- CAP partition lab
Compare conflicting writes across a network split under quorum and local-acceptance policies.
Predict first. Can both sides acknowledge a conflicting start operation while preserving the declared invariant?
Follow the idea
Explore through a course task (1)
- Challenge an explanation
An agent says a recorder prevents duplicate events after restart. Predict the behavior and test its claim.
- Architecture: authority and access
Follow ownership before choosing placement.
- Appendix C: rebuild without repeating effects
Keep derived views separate from durable actions.
Connect the concepts
- Action authorization Authoritative state permission vs commit
Action authorization asks who may execute an operation; authoritative state establishes its committed outcome and the boundary responsible for preserving it. An authorized attempt can still fail to commit.
- Rendering and activation Authoritative state view vs durable state
Rendering a representation must remain distinct from committing the durable action it displays.
- Transaction protects changes to Authoritative state
Transactions protect related changes at the durable authority under the store's actual guarantees.
- Authoritative state is the source for Cache
A cache is a controlled copy whose freshness and invalidation depend on the authoritative state.
- Consistency governs observations of Authoritative state
Consistency promises describe how consumers observe authoritative changes through concurrency and copies.
Find this idea across the book (5)
Benchmark protocolEvidence A reproducible procedure that tests a specific performance claim with a declared workload, environment, boundaries, and success criteria. Explore concept Group member
Evidence
Benchmark protocol
- Definition
- A reproducible procedure that tests a specific performance claim with a declared workload, environment, boundaries, and success criteria.
- Assumptions
- Record versions, input distribution, warm-up, concurrency or arrival schedule, repetitions, failures, and unfinished work. Check that the generator is able to offer the intended load.
- Worked example
- Run the same activity-feed workload against A, B, and C, preserving logical operation boundaries and reporting valid completions separately from overload rejections.
- Common mistake
- A single requests-per-second number ranks implementations. Different work, failure accounting, or generator behavior can make the numbers incomparable.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Benchmark protocol · 5 connections
Read the relationships
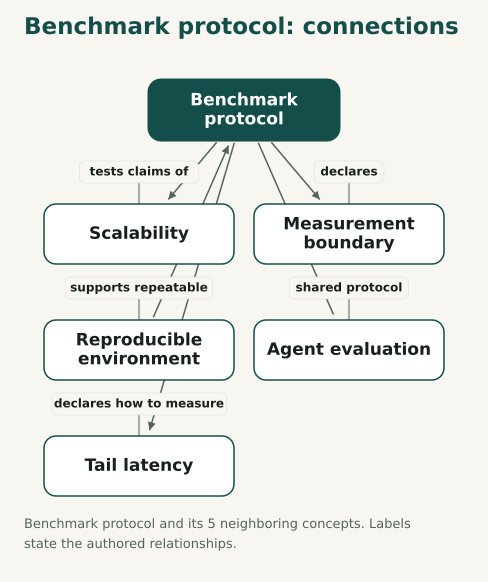
- Benchmark protocol tests claims of Scalability
A benchmark protocol makes a conditional scalability claim testable.
- Benchmark protocol declares Measurement boundary
A benchmark protocol declares the boundary at which elapsed time and completed work are counted.
- Reproducible environment supports repeatable Benchmark protocol
Reproducible environments help separate implementation differences from setup differences in a benchmark.
- Benchmark protocol Agent evaluation shared protocol
Benchmarks and agent evaluations both require declared tasks, boundaries, outcome criteria, and failure accounting.
- Benchmark protocol declares how to measure Tail latency
A benchmark needs a declared latency population and percentile convention to support a tail-latency claim.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (6)
- Benchmark protocol: connections
Benchmark protocol and its 5 neighboring concepts. Labels state the authored relationships.
- One application, three development systems
The task stays comparatively stable while the development system changes. Learning accumulates; application code does not.
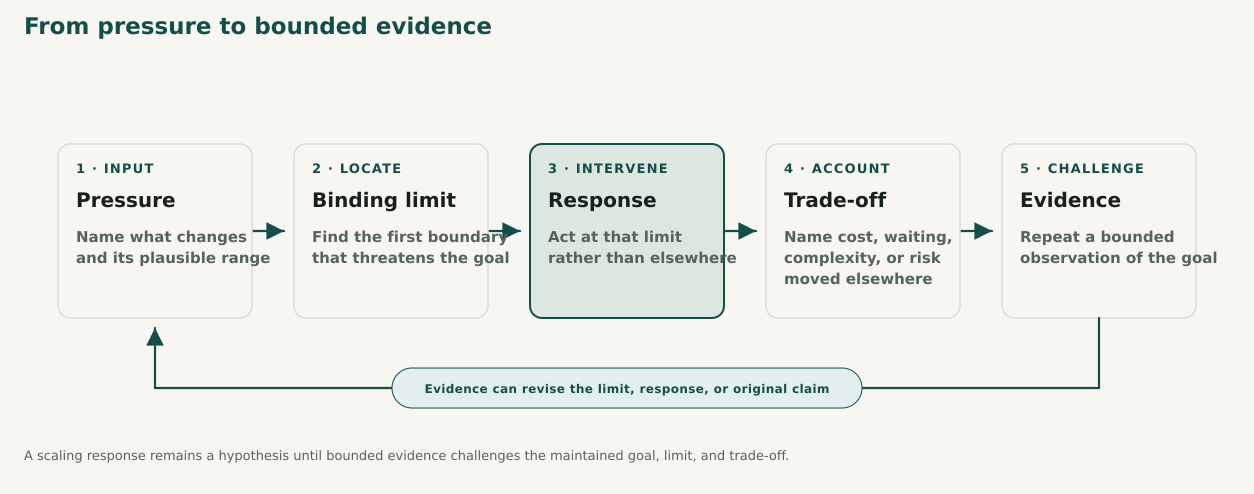
- From pressure to bounded evidence
A scaling response remains a hypothesis until bounded evidence challenges the maintained goal, limit, and trade-off.
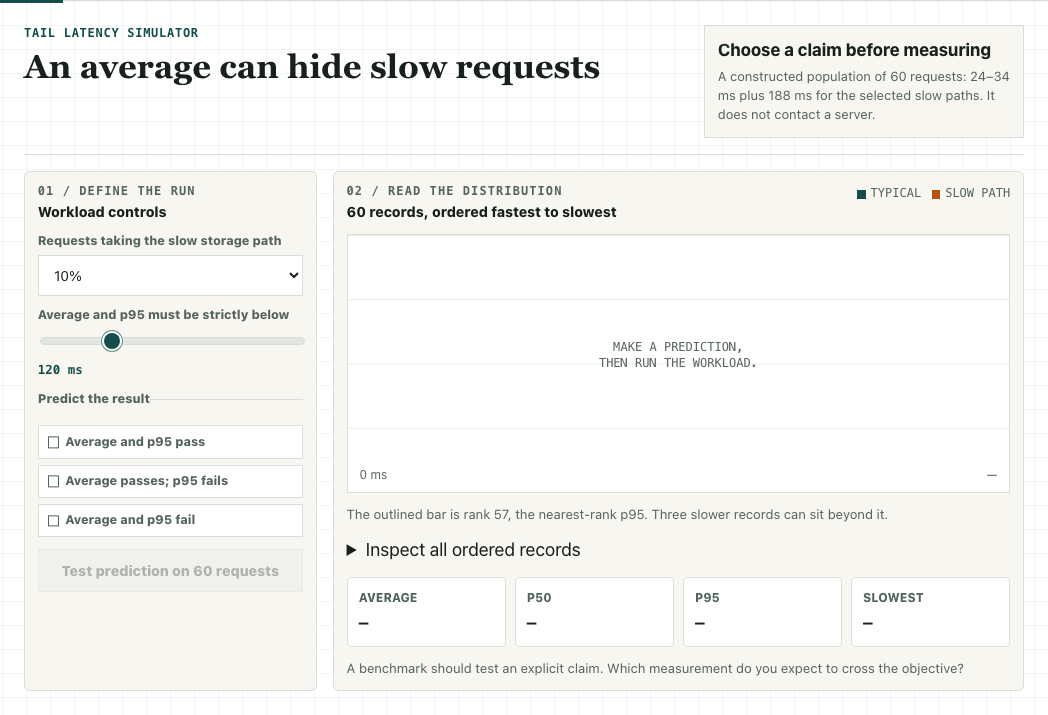
- Tail latency simulator
Compare average latency and p95 when a minority of requests take a slow path.
Predict first. Will the average and p95 cross the objective together when only a minority of requests become slow?
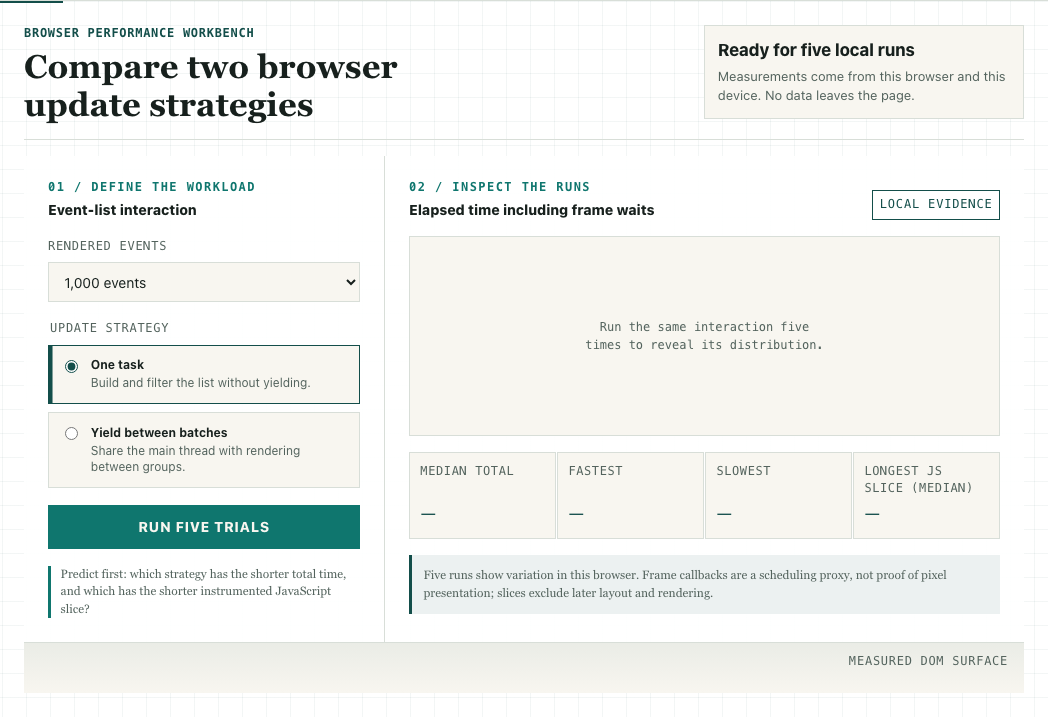
- Browser performance workbench
Measure total time and instrumented JavaScript slices while yielding or blocking the main thread.
Predict first. Which strategy will have the shorter total time, and which the shorter longest JavaScript slice?
- Fleet trace debugger
Reconcile orchestration intent, gateway decisions, and the physical execution ledger.
Predict first. Which records prove execution, and which express only an intended or authorized action?
Follow the idea
- Measurement: test a claim
Declare the protocol before interpreting numbers.
- Project: common workload
Hold logical operations constant across implementations.
Connect the concepts
- Benchmark protocol tests claims of Scalability
A benchmark protocol makes a conditional scalability claim testable.
- Benchmark protocol declares Measurement boundary
A benchmark protocol declares the boundary at which elapsed time and completed work are counted.
- Reproducible environment supports repeatable Benchmark protocol
Reproducible environments help separate implementation differences from setup differences in a benchmark.
- Benchmark protocol Agent evaluation shared protocol
Benchmarks and agent evaluations both require declared tasks, boundaries, outcome criteria, and failure accounting.
- Benchmark protocol declares how to measure Tail latency
A benchmark needs a declared latency population and percentile convention to support a tail-latency claim.
CacheArchitecture A controlled copy of a representation or result whose identity, freshness, invalidation, and access policy are part of the application contract. Explore concept Group member
Architecture
Cache
- Definition
- A controlled copy of a representation or result whose identity, freshness, invalidation, and access policy are part of the application contract.
- Assumptions
- Name the authority, cache key, eligible population, stale tolerance, and invalidation path. Shared caches must preserve isolation between users and workspaces.
- Worked example
- Cache an activity feed by workspace and filter, then define when a newly committed event becomes visible. Omitting workspace from the key can expose another workspace's data.
- Common mistake
- Caching only changes speed. It also changes freshness, authorization exposure, dependency load, and recovery behavior.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Cache · 5 connections
Read the relationships
- Scaling pressure can motivate Cache
Data or demand pressure may motivate caching, but the cache introduces a freshness and access contract.
- Rendering and activation Cache freshness and activation
A cached representation needs freshness and activation policies in addition to a fast delivery path.
- Authoritative state is the source for Cache
A cache is a controlled copy whose freshness and invalidation depend on the authoritative state.
- Cache has freshness rules in Consistency
Cache freshness is part of the observation promise, but it does not by itself define every consistency guarantee.
- Cache introduces Trade-off
Caching can reduce dependency load while introducing invalidation, freshness, and access obligations.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (4)
- Cache: connections
Cache and its 5 neighboring concepts. Labels state the authored relationships.
- An external quota becomes the availability boundary
Production traffic was amplified into GitHub API traffic until one external quota became the availability boundary for the whole site.
- Cache decision lab
Trace reuse, validation, and stale responses under different HTTP cache policies.
Predict first. Which policy can reuse a response without contacting the origin, and what freshness promise does that make?
- Latency budget map
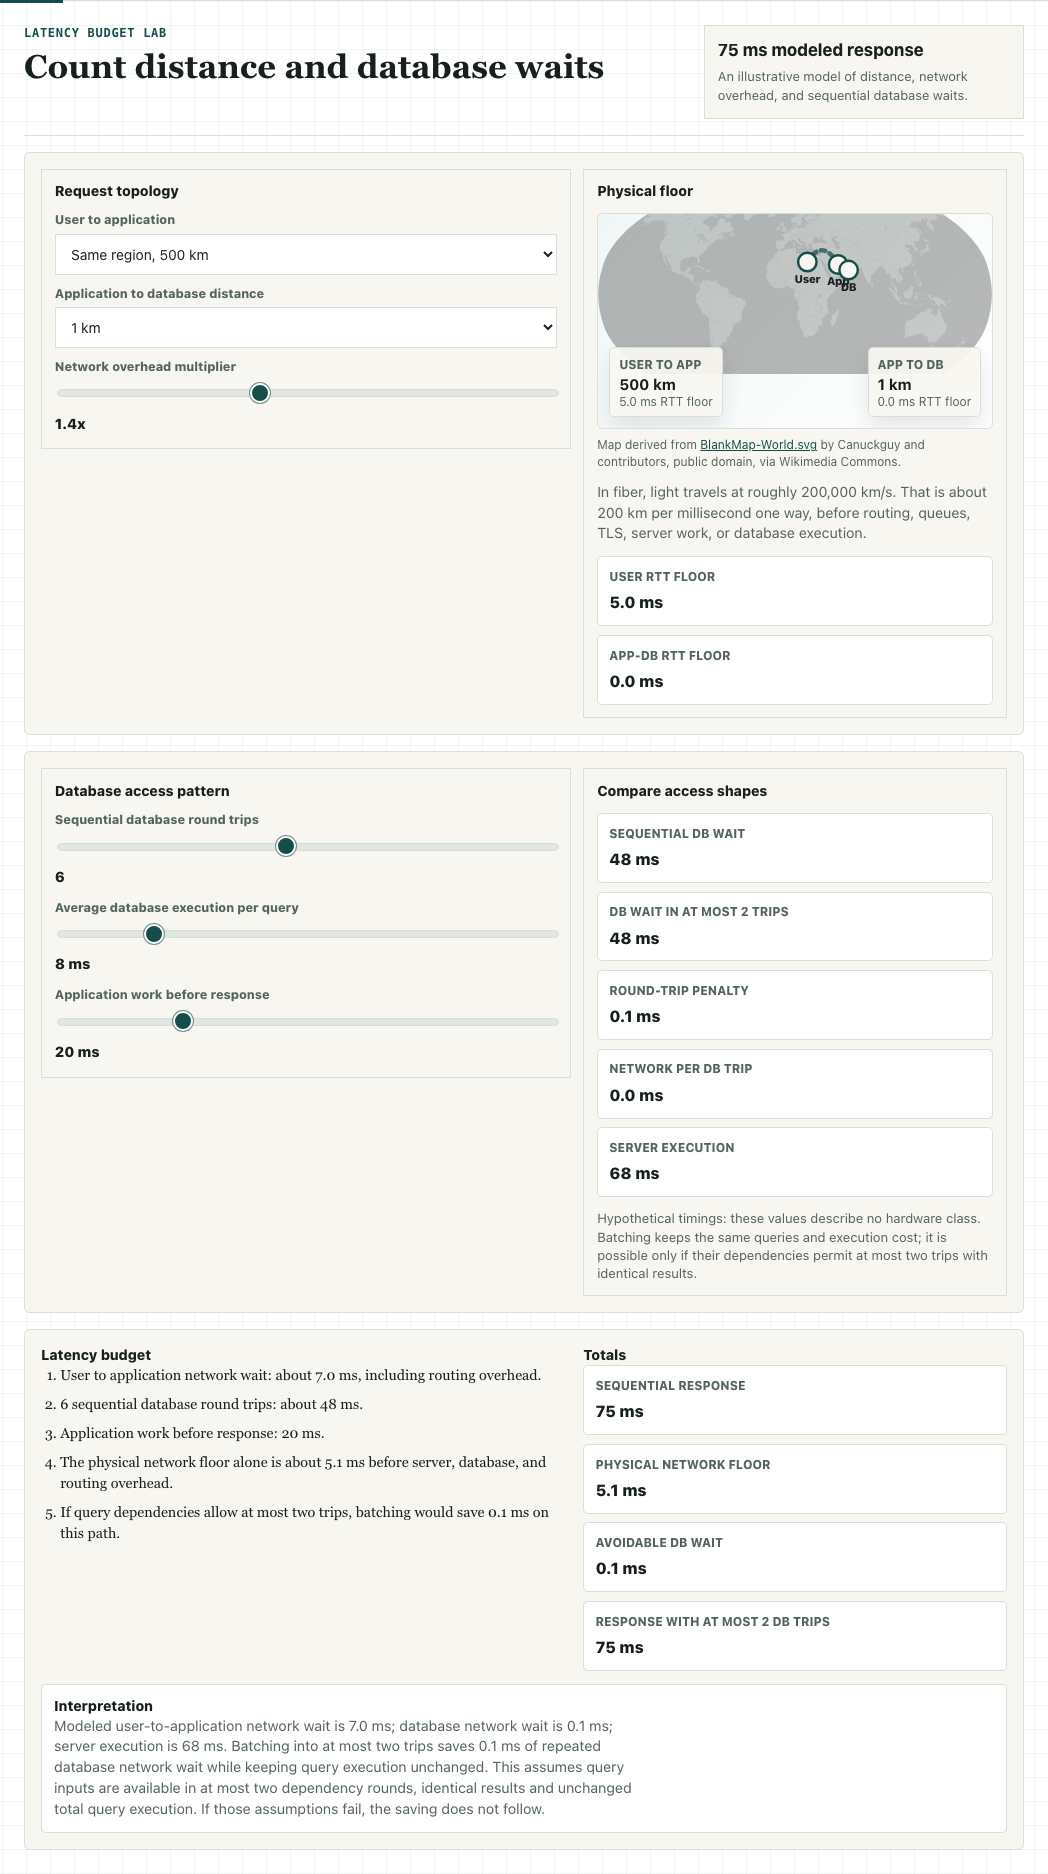
Estimate latency contributions from geography, round trips, and execution time.
Predict first. Which will matter more in your scenario: faster query execution or fewer sequential remote round trips?
Follow the idea
- Architecture: controlled copies
Specify cache policy as behavior.
- Pressure: a dependency quota outage
Trace faulty caching into an availability failure.
Connect the concepts
- Scaling pressure can motivate Cache
Data or demand pressure may motivate caching, but the cache introduces a freshness and access contract.
- Rendering and activation Cache freshness and activation
A cached representation needs freshness and activation policies in addition to a fast delivery path.
- Authoritative state is the source for Cache
A cache is a controlled copy whose freshness and invalidation depend on the authoritative state.
- Cache has freshness rules in Consistency
Cache freshness is part of the observation promise, but it does not by itself define every consistency guarantee.
- Cache introduces Trade-off
Caching can reduce dependency load while introducing invalidation, freshness, and access obligations.
Find this idea across the book (3)
Coding agentDevelopment A model-driven loop that observes context, chooses actions through tools, and uses resulting feedback to continue a development task. Explore concept Group member
Development
Coding agent
- Definition
- A model-driven loop that observes context, chooses actions through tools, and uses resulting feedback to continue a development task.
- Usage in this book
- Agent is an established AI concept; coding agent has a more specific working meaning here. LLM practitioners vary in whether predefined workflows count as agents. The definition above requires model-directed action through tools.
- Assumptions
- Capabilities depend on the model, context, tools, environment, budget, and permitted authority. Generated work remains candidate work until accepted.
- Worked example
- An agent edits an event handler, runs contract tests, inspects a failure, and revises the implementation before a maintainer accepts the change.
- Common mistake
- The model alone determines the development result. Its harness and the project's constraints materially shape what it can do and verify.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Coding agent · 3 connections
Read the relationships
- Project harness supplies context for Coding agent
An agent's useful capability depends on the project context, tools, checks, and commands supplied by its harness.
- Action authorization bounds actions of Coding agent
An agent's ability to invoke a tool must be bounded by the authority granted for the task.
- Agent fleet coordinates Coding agent
A fleet extends one agent's execution loop with explicit coordination, integration, and acceptance.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (3)
- Coding agent: connections
Coding agent and its 3 neighboring concepts. Labels state the authored relationships.
- One application, three development systems
The task stays comparatively stable while the development system changes. Learning accumulates; application code does not.
- Three connected scalability loops
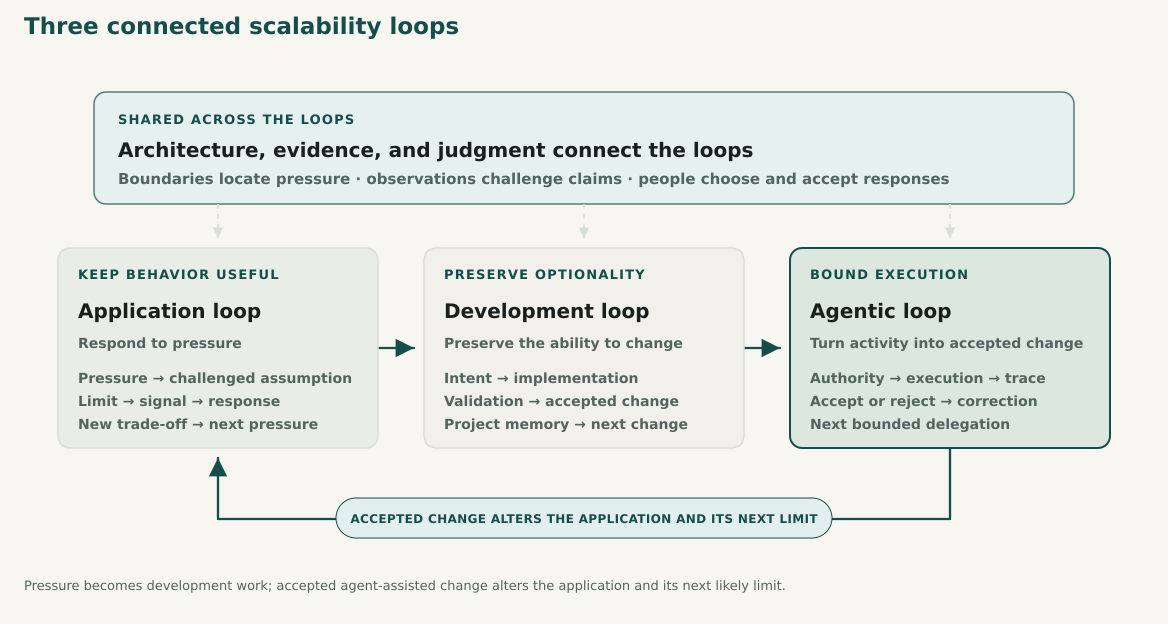
Pressure becomes development work; accepted agent-assisted change alters the application and its next likely limit.
Follow the idea
- Development: define an agent
Identify the observation–action loop.
- Fleets: choose a coordination structure
Explain the coordination obligations of each option.
Connect the concepts
- Project harness supplies context for Coding agent
An agent's useful capability depends on the project context, tools, checks, and commands supplied by its harness.
- Action authorization bounds actions of Coding agent
An agent's ability to invoke a tool must be bounded by the authority granted for the task.
- Agent fleet coordinates Coding agent
A fleet extends one agent's execution loop with explicit coordination, integration, and acceptance.
ConsistencyArchitecture The promised relationship between operations and the state they can observe across concurrent access and replicated copies. Explore concept Group member
Architecture
Consistency
- Definition
- The promised relationship between operations and the state they can observe across concurrent access and replicated copies.
- Assumptions
- Name the actual guarantee and the relevant operation. Freshness delay, ordering, and durable integrity are related but different questions.
- Worked example
- A committed event may reach a regional feed later. Decide whether that stale read is permitted and how the UI represents pending visibility.
- Common mistake
- All consistency choices are simply strong or eventual. The contract must describe what a consumer can rely on in its specific operation.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Consistency · 4 connections
Read the relationships
- Consistency governs observations of Authoritative state
Consistency promises describe how consumers observe authoritative changes through concurrency and copies.
- Cache has freshness rules in Consistency
Cache freshness is part of the observation promise, but it does not by itself define every consistency guarantee.
- Consistency constrains acceptance during Network partition
During a partition, the operation's consistency promise constrains which work disconnected nodes may accept.
- Consistency can add delay to Latency
Coordinating remote state can add latency; permitting delayed observations changes the consumer's contract.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (5)
- Consistency: connections
Consistency and its 4 neighboring concepts. Labels state the authored relationships.
- ACID transaction lab
Inspect lifecycle and ledger records under failed writes, concurrency, and restart.
Predict first. Which invariant could fail between two application-managed writes?
- Cache decision lab
Trace reuse, validation, and stale responses under different HTTP cache policies.
Predict first. Which policy can reuse a response without contacting the origin, and what freshness promise does that make?
- CAP partition lab
Compare conflicting writes across a network split under quorum and local-acceptance policies.
Predict first. Can both sides acknowledge a conflicting start operation while preserving the declared invariant?
- Latency budget map
Estimate latency contributions from geography, round trips, and execution time.
Predict first. Which will matter more in your scenario: faster query execution or fewer sequential remote round trips?
Follow the idea
- Scaling: geography and latency
Connect distance with observation guarantees.
- Appendix C: partition proof and lab
Distinguish operation ordering from transaction atomicity.
- Architecture: data authority
Distinguish authoritative state from copies.
Connect the concepts
- Consistency governs observations of Authoritative state
Consistency promises describe how consumers observe authoritative changes through concurrency and copies.
- Cache has freshness rules in Consistency
Cache freshness is part of the observation promise, but it does not by itself define every consistency guarantee.
- Consistency constrains acceptance during Network partition
During a partition, the operation's consistency promise constrains which work disconnected nodes may accept.
- Consistency can add delay to Latency
Coordinating remote state can add latency; permitting delayed observations changes the consumer's contract.
Find this idea across the book (3)
ContentionModels Competition for shared resources or coordination that makes additional parallel workers spend more time waiting or synchronizing. Explore concept Group member
Models
Contention
- Definition
- Competition for shared resources or coordination that makes additional parallel workers spend more time waiting or synchronizing.
- Assumptions
- Declare the workload and shared resource. Fit or compare a contention model only with suitable measurements; its parameters are not universal constants.
- Worked example
- More event workers compete for the same database lock. Parallelism increases, but completed throughput can plateau or fall as coordination grows.
- Common mistake
- Amdahl's ideal speedup bound accounts for every coordination cost. Added contention can make actual scaling worse than that bound suggests.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Contention · 3 connections
Read the relationships
- Amdahl's Law omits new costs of Contention
Amdahl's ideal fixed-workload bound omits new contention and coordination costs introduced by parallelism.
- Contention can reduce Throughput
Competition for a shared resource can make throughput plateau or decline as workers are added.
- Contention can expose Saturation
Contention can expose a binding shared-resource limit before every worker is fully utilized.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (2)
- Contention: connections
Contention and its 3 neighboring concepts. Labels state the authored relationships.
- Contention curve lab
Explore a modeled capacity curve as contention and coherency costs change.
Predict first. Will adding workers always increase capacity when coherency cost is nonzero?
Follow the idea
- Scaling: beyond Amdahl
Account for costs introduced by parallelism.
- Appendix E: contention curve
Compare a model with the observed curve.
Connect the concepts
- Amdahl's Law omits new costs of Contention
Amdahl's ideal fixed-workload bound omits new contention and coordination costs introduced by parallelism.
- Contention can reduce Throughput
Competition for a shared resource can make throughput plateau or decline as workers are added.
- Contention can expose Saturation
Contention can expose a binding shared-resource limit before every worker is fully utilized.
Find this idea across the book (4)
Decision logDevelopment A maintained record of consequential decisions, their context, rationale, status, and consequences. Explore concept Group member
Development
Decision log
- Definition
- A maintained record of consequential decisions, their context, rationale, status, and consequences. An Architecture Decision Record (ADR) captures one architecturally significant choice in such a log.
- Assumptions
- For the course, include alternatives, evidence, ownership, current reversibility, and a revisit condition. Distinguish proposed, accepted, and implemented status from whether the choice remains soft or has become hard. Link superseding decisions to earlier records.
- Worked example
- A record accepts an optional category field for an isolated trial, links compatibility tests, and requires review before production adoption. It notes that storing the representation and exposing it to independent clients will make reversal require compatibility or migration.
- Common mistake
- Writing an ADR makes a decision permanent, proves it was implemented, or replaces current tests and contracts. The log preserves rationale and review conditions; it must remain connected to the actual implementation and evidence.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Decision log · 6 connections
Read the relationships
- Decision log records conditions for Decision reversibility
A decision record can state which choices remain soft, what dependencies would make them hard, and what safe reversal would require.
- Decision log records rationale for Trade-off
The log preserves the alternatives, rationale, and consequences that justified a trade-off under the conditions known at the time.
- Decision log Project harness accepted context
Decision records preserve accepted project context, while current specifications and executable harness checks must reflect the implemented choice.
- Decision log Feedback loop revisit conditions
A recorded revisit condition makes new evidence a reason to review a choice; a superseding record preserves why the earlier decision changed.
- Decision log can document Technical debt
A record makes deliberately accepted debt and its future change cost visible so an owner can review it instead of letting the obligation disappear from view.
- Decision log Action authorization decision ownership
A proposed record does not grant action authority; acceptance needs a named owner, and the record's status must distinguish intent from implementation.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (1)
- Decision log: connections
Decision log and its 6 neighboring concepts. Labels state the authored relationships.
Follow the idea
- Friction: record the commitment
Record soft and hard choices with their evidence and revisit conditions.
- Measurement: preserve accepted context
Distinguish accepted rationale from a complete execution trace.
- Project: record the stack hypothesis
Use the existing stack decision record to make assumptions reviewable.
Connect the concepts
- Decision log records conditions for Decision reversibility
A decision record can state which choices remain soft, what dependencies would make them hard, and what safe reversal would require.
- Decision log records rationale for Trade-off
The log preserves the alternatives, rationale, and consequences that justified a trade-off under the conditions known at the time.
- Decision log Project harness accepted context
Decision records preserve accepted project context, while current specifications and executable harness checks must reflect the implemented choice.
- Decision log Feedback loop revisit conditions
A recorded revisit condition makes new evidence a reason to review a choice; a superseding record preserves why the earlier decision changed.
- Decision log can document Technical debt
A record makes deliberately accepted debt and its future change cost visible so an owner can review it instead of letting the obligation disappear from view.
- Decision log Action authorization decision ownership
A proposed record does not grant action authority; acceptance needs a named owner, and the record's status must distinguish intent from implementation.
Decision reversibilityDevelopment How easily a decision can be revised or undone safely. Explore concept Group member
Development
Decision reversibility
- Definition
- How easily a decision can be revised or undone safely. Soft decisions remain cheap to change; hard decisions require more coordination or recovery because other work depends on them.
- Usage in this book
- Soft and hard decisions are the book's shorthand for low and high reversal cost. This relates to the one-way/two-way-door distinction, but the course treats reversal cost as a spectrum that changes with dependencies and durable effects.
- Assumptions
- Assess the current dependencies, durable effects, reversal cost, and evidence of safe recovery. Soft and hard are relative descriptions, and a choice can become harder as it is used.
- Worked example
- A category representation tried in an isolated branch is easy to revise. Once production events store it and independent clients rely on it, changing that same choice requires compatibility or migration rather than only a code revert.
- Common mistake
- A small code change is always a soft decision, or a hard decision is automatically technical debt. Durable effects and dependencies determine reversal cost; some hard commitments are necessary and justified.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Decision reversibility · 7 connections
Read the relationships
- Decision log records conditions for Decision reversibility
A decision record can state which choices remain soft, what dependencies would make them hard, and what safe reversal would require.
- Decision reversibility Technical debt commitment vs debt
Technical debt can reduce future options, but a hard decision is not automatically debt; its dependencies and reversal cost may be necessary and justified.
- Decision reversibility Development friction reversal cost
A choice becomes harder to revise as safe reversal requires coordination across data, consumers, and deployment boundaries.
- Application contract can constrain Decision reversibility
An independently deployed consumer relying on a contract can turn a locally editable choice into a hard compatibility commitment.
- Decision reversibility Trade-off option value
Planning a trade-off includes the value of keeping an uncertain choice soft and the obligations introduced by committing to it.
- Maintainability assessment assesses Decision reversibility
A bounded change probe can test how much effort a revision requires and which dependencies make a decision hard to change.
- Decision reversibility Recovery safe reversal
Reversing a decision after durable effects may require migration or reconciliation; restoring code alone does not establish safe recovery.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (2)
- Decision reversibility: connections
Decision reversibility and its 7 neighboring concepts. Labels state the authored relationships.
- Knowledge and artifact ownership
Reusable source knowledge stays external; Slideotter and Kirjolab own their artifact-specific decisions.
Follow the idea
Explore through a course task (1)
- Move a prototype into shared use
A working CSV exporter is ready for a demo. What would make it ready for a team's weekly report?
- Friction: plan soft and hard decisions
Keep uncertain choices cheap to revise and identify what would make them hard.
- Scalability: change exposes commitments
Connect the ability to keep changing with the dependencies already created.
- Friction: keep a decision log
Preserve what makes a choice reversible and when it should be reviewed.
Connect the concepts
- Decision log records conditions for Decision reversibility
A decision record can state which choices remain soft, what dependencies would make them hard, and what safe reversal would require.
- Decision reversibility Technical debt commitment vs debt
Technical debt can reduce future options, but a hard decision is not automatically debt; its dependencies and reversal cost may be necessary and justified.
- Decision reversibility Development friction reversal cost
A choice becomes harder to revise as safe reversal requires coordination across data, consumers, and deployment boundaries.
- Application contract can constrain Decision reversibility
An independently deployed consumer relying on a contract can turn a locally editable choice into a hard compatibility commitment.
- Decision reversibility Trade-off option value
Planning a trade-off includes the value of keeping an uncertain choice soft and the obligations introduced by committing to it.
- Maintainability assessment assesses Decision reversibility
A bounded change probe can test how much effort a revision requires and which dependencies make a decision hard to change.
- Decision reversibility Recovery safe reversal
Reversing a decision after durable effects may require migration or reconciliation; restoring code alone does not establish safe recovery.
Find this idea across the book (7)
Development frictionDevelopment The resistance a team encounters while setting up, understanding, changing, testing, reviewing, deploying, or operating a system. Explore concept Group member
Development
Development friction
- Definition
- The resistance a team encounters while setting up, understanding, changing, testing, reviewing, deploying, or operating a system.
- Usage in this book
- Development friction is a descriptive umbrella for observed effort and waiting. The course's setup, comprehension, change, and protective-friction categories organize an audit; they are not a standardized productivity score.
- Assumptions
- Locate a concrete blockage and the boundary it crosses. Some friction protects a named risk; a commitment is not automatically technical debt.
- Worked example
- Adding an event category requires finding the HTTP contract, changing validation and stored data, updating the feed's cache key, and checking deployment compatibility. Record where effort and waiting accumulate before choosing an intervention.
- Common mistake
- All friction should be removed, or faster generation removes it. Validation and release gates can be protective, while generation can move effort into comprehension, review, and operation.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Development friction · 7 connections
Read the relationships
- Decision reversibility Development friction reversal cost
A choice becomes harder to revise as safe reversal requires coordination across data, consumers, and deployment boundaries.
- Development friction Technical debt change cost
Friction can expose the practical cost of technical debt, but protective checks and necessary commitments are not automatically debt.
- Reproducible environment can reduce Development friction
A declared, reproducible environment can reduce setup friction and reveal hidden inputs rather than relying on undocumented repairs.
- Development friction Application contract cross-boundary change
A small feature can create friction as it crosses HTTP, data, cache, and deployment contracts owned at different boundaries.
- Feedback loop can reduce Development friction
Feedback matched to the changed boundary can reduce diagnosis and revision friction while retaining useful checks.
- Maintainability assessment assesses Development friction
A bounded change probe records concrete blockages and effort so a friction claim can be tested by an unfamiliar maintainer.
- Development friction Action authorization protective friction
Explicit ownership reduces coordination ambiguity; authorization and release gates can remain protective friction when they control a named risk.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (1)
- Development friction: connections
Development friction and its 7 neighboring concepts. Labels state the authored relationships.
Follow the idea
- Friction: recognize the forms
Distinguish setup, comprehension, change, and protective friction.
- Friction: find the commitment point
Explain when a simple revert stops restoring the prior state.
Connect the concepts
- Decision reversibility Development friction reversal cost
A choice becomes harder to revise as safe reversal requires coordination across data, consumers, and deployment boundaries.
- Development friction Technical debt change cost
Friction can expose the practical cost of technical debt, but protective checks and necessary commitments are not automatically debt.
- Reproducible environment can reduce Development friction
A declared, reproducible environment can reduce setup friction and reveal hidden inputs rather than relying on undocumented repairs.
- Development friction Application contract cross-boundary change
A small feature can create friction as it crosses HTTP, data, cache, and deployment contracts owned at different boundaries.
- Feedback loop can reduce Development friction
Feedback matched to the changed boundary can reduce diagnosis and revision friction while retaining useful checks.
- Maintainability assessment assesses Development friction
A bounded change probe records concrete blockages and effort so a friction claim can be tested by an unfamiliar maintainer.
- Development friction Action authorization protective friction
Explicit ownership reduces coordination ambiguity; authorization and release gates can remain protective friction when they control a named risk.
Find this idea across the book (1)
Durable workflowOperations Execution that preserves coordination progress so work can resume after interruption without reconstructing every completed step. Explore concept Group member
Operations
Durable workflow
- Definition
- Execution that preserves coordination progress so work can resume after interruption without reconstructing every completed step.
- Assumptions
- Persistence of workflow progress does not itself make external effects retry-safe. Audit each effect's authority, operation identity, and uncertain-outcome handling.
- Worked example
- A workflow checkpoints completed rendering and resumes publication after a crash. Publishing still needs a stable identity so an uncertain response cannot create duplicate artifacts.
- Common mistake
- Durable execution guarantees exactly-once external effects. Progress recovery and effect safety are separate guarantees.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Durable workflow · 2 connections
Read the relationships
- Idempotency guards repeated effects in Durable workflow
Durable coordination can resume steps, while idempotency protects effects that may be attempted again.
- Durable workflow preserves progress for Recovery
Preserved workflow progress helps interrupted coordination resume, but recovery must still audit its effects.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (2)
- Durable workflow: connections
Durable workflow and its 2 neighboring concepts. Labels state the authored relationships.
- Durable effect retry lab
Stop a worker after an external effect but before its completion enters durable history.
Predict first. If the receiver applied the effect but completion was not recorded, what could make a retry apply it twice?
Follow the idea
- Appendix F: preserve coordination progress
Separate durable coordination from effect semantics.
- Slideotter: artifact authority
Locate the artifact that generation may replace.
Connect the concepts
- Idempotency guards repeated effects in Durable workflow
Durable coordination can resume steps, while idempotency protects effects that may be attempted again.
- Durable workflow preserves progress for Recovery
Preserved workflow progress helps interrupted coordination resume, but recovery must still audit its effects.
Find this idea across the book (4)
Feedback loopDevelopment A cycle in which a system's effects feed back into its subsequent behavior. Explore concept Group member
Development
Feedback loop
- Definition
- A cycle in which a system's effects feed back into its subsequent behavior. Negative feedback counteracts a deviation; positive feedback reinforces it.
- Usage in this book
- Positive and negative describe whether the loop reinforces or counteracts a change, not whether its outcome is desirable. The development examples mainly use corrective feedback; overload examples also use reinforcing feedback.
- Assumptions
- Identify the causal path, signal, response, and delay. For a corrective loop, also name the desired state and owner. Negative feedback can still become unstable when delay or response strength is poorly controlled.
- Worked example
- A failing contract check leads an agent to revise a change: corrective feedback. Overload causes timeouts, timeouts cause retries, and retries add load: reinforcing feedback.
- Common mistake
- More frequent feedback guarantees improvement. A delayed or misleading signal can amplify the wrong behavior.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Feedback loop · 7 connections
Read the relationships
- Loop engineering designs agent use of Feedback loop
Loop engineering chooses the observations and responses that guide agent work; a feedback loop describes how effects influence subsequent behavior, including harmful reinforcing cycles.
- Decision log Feedback loop revisit conditions
A recorded revisit condition makes new evidence a reason to review a choice; a superseding record preserves why the earlier decision changed.
- Feedback loop can reduce Development friction
Feedback matched to the changed boundary can reduce diagnosis and revision friction while retaining useful checks.
- Observability supplies signals for Feedback loop
A corrective feedback loop can choose a useful response only when its signals describe the relevant goal and boundary.
- Feedback loop Retry policy reinforcing load
Overload can cause timeouts that trigger retries and add more load. A bounded retry policy with delay and admission control can limit this reinforcing feedback; retry-safe effects are still required.
- Project harness provides checks for Feedback loop
Executable harness checks turn generated work into feedback that can guide a revision.
- Feedback loop Technical debt omitted future cost
Feedback that omits the cost of later changes can allow technical debt to grow while current tasks pass.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (3)
- Feedback loop: connections
Feedback loop and its 7 neighboring concepts. Labels state the authored relationships.
- Three connected scalability loops
Pressure becomes development work; accepted agent-assisted change alters the application and its next likely limit.
- Orchestration control loop
Follow controller actions that reconcile observed replicas with desired state.
Predict first. After losing a replica, what discrepancy should the controller observe and what action should follow?
Follow the idea
- Development: constrain, generate, validate, revise
Use the loop to turn candidate work into accepted work.
- Scaling: orchestration control
Compare development feedback with runtime control.
- Scaling: retry amplification
Trace the reinforcing cycle from overload to timeouts, retries, and more load.
Connect the concepts
- Loop engineering designs agent use of Feedback loop
Loop engineering chooses the observations and responses that guide agent work; a feedback loop describes how effects influence subsequent behavior, including harmful reinforcing cycles.
- Decision log Feedback loop revisit conditions
A recorded revisit condition makes new evidence a reason to review a choice; a superseding record preserves why the earlier decision changed.
- Feedback loop can reduce Development friction
Feedback matched to the changed boundary can reduce diagnosis and revision friction while retaining useful checks.
- Observability supplies signals for Feedback loop
A corrective feedback loop can choose a useful response only when its signals describe the relevant goal and boundary.
- Feedback loop Retry policy reinforcing load
Overload can cause timeouts that trigger retries and add more load. A bounded retry policy with delay and admission control can limit this reinforcing feedback; retry-safe effects are still required.
- Project harness provides checks for Feedback loop
Executable harness checks turn generated work into feedback that can guide a revision.
- Feedback loop Technical debt omitted future cost
Feedback that omits the cost of later changes can allow technical debt to grow while current tasks pass.
Find this idea across the book (7)
Goodhart's LawEvidence A warning that optimizing a proxy as a target can weaken its relationship to the outcome it was intended to represent. Explore concept Group member
Evidence
Goodhart's Law
- Definition
- A warning that optimizing a proxy as a target can weaken its relationship to the outcome it was intended to represent.
- Assumptions
- Identify the useful outcome, the proxy, and how behavior changes when rewarded for the proxy. Check the outcome with evidence beyond the target metric.
- Worked example
- Rewarding generated changes per hour can produce more small submissions while accepted output stays flat and reviewer waiting grows.
- Common mistake
- Every metric is useless. Metrics can inform decisions when their boundary, incentives, and omitted outcomes remain visible.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Goodhart's Law · 2 connections
Read the relationships
- Goodhart's Law warns about targeting Throughput
Counting generated or acknowledged work can become a misleading target when useful accepted completions are the intended outcome.
- Goodhart's Law Acceptance criteria outcome checks
Acceptance criteria help check the intended outcome when a convenient proxy metric becomes a target.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (1)
- Goodhart's Law: connections
Goodhart's Law and its 2 neighboring concepts. Labels state the authored relationships.
Follow the idea
- Measurement: challenge the metric
Use the Goodhart pressure test to inspect the proxy.
- Fleets: measure accepted output
Count accepted work and the human effort it needs.
Connect the concepts
- Goodhart's Law warns about targeting Throughput
Counting generated or acknowledged work can become a misleading target when useful accepted completions are the intended outcome.
- Goodhart's Law Acceptance criteria outcome checks
Acceptance criteria help check the intended outcome when a convenient proxy metric becomes a target.
Find this idea across the book (2)
IdempotencyArchitecture The property that repeating one logical operation has the same intended effect at a declared boundary as performing it once. Explore concept Group member
Architecture
Idempotency
- Definition
- The property that repeating one logical operation has the same intended effect at a declared boundary as performing it once.
- Assumptions
- Name the operation and all its intended effects. For key-based deduplication, define key scope and lifetime, conflicting payload behavior, and atomic enforcement with the effect and result at their authority.
- Worked example
- Completing a work item promises the Done status and one activity event. A retry that leaves the status unchanged but appends another event violates the whole operation's contract.
- Common mistake
- An unchanged final status proves the whole operation is idempotent. Its contract may include other effects; a local deduplication guarantee also does not establish exactly-once execution elsewhere.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Idempotency · 4 connections
Read the relationships
- Application contract defines effects for Idempotency
The contract names all intended effects against which idempotency is judged. A key-based retry protocol also needs scope, conflict, retention, and outcome rules.
- Transaction can support Idempotency
A key-based command protocol can atomically enforce operation identity with the promised effects and a reusable result at their authority. A transaction alone does not prevent repeated commands.
- Idempotency guards repeated effects of Retry policy
A deduplicated command reuses its logical operation identity after an ambiguous outcome so the retry cannot invent another durable action.
- Idempotency guards repeated effects in Durable workflow
Durable coordination can resume steps, while idempotency protects effects that may be attempted again.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (2)
- Idempotency: connections
Idempotency and its 4 neighboring concepts. Labels state the authored relationships.
- Durable effect retry lab
Stop a worker after an external effect but before its completion enters durable history.
Predict first. If the receiver applied the effect but completion was not recorded, what could make a retry apply it twice?
Follow the idea
Explore through a course task (1)
- Challenge an explanation
An agent says a recorder prevents duplicate events after restart. Predict the behavior and test its claim.
- Pressure: lost response and duplicate
Follow one logical command through a retry.
- Pressure: inspect all promised effects
Assess the status and activity history together before choosing a retry mechanism.
- Appendix C: HTTP method semantics
Separate intended effects, response differences, and incidental request logging.
- Appendix F: audit the effect
Place deduplication at the authority for the effect.
Connect the concepts
- Application contract defines effects for Idempotency
The contract names all intended effects against which idempotency is judged. A key-based retry protocol also needs scope, conflict, retention, and outcome rules.
- Transaction can support Idempotency
A key-based command protocol can atomically enforce operation identity with the promised effects and a reusable result at their authority. A transaction alone does not prevent repeated commands.
- Idempotency guards repeated effects of Retry policy
A deduplicated command reuses its logical operation identity after an ambiguous outcome so the retry cannot invent another durable action.
- Idempotency guards repeated effects in Durable workflow
Durable coordination can resume steps, while idempotency protects effects that may be attempted again.
Find this idea across the book (4)
InvariantArchitecture A condition that must hold for every valid state or accepted transition within a declared domain boundary. Explore concept Group member
Architecture
Invariant
- Definition
- A condition that must hold for every valid state or accepted transition within a declared domain boundary.
- Assumptions
- Specify the boundary and concurrent transitions. Validate at the authority; input validation alone may not protect against competing requests.
- Worked example
- An event must reference a work item in the same workspace. The rule must survive concurrent writes and retries, not only the UI form.
- Common mistake
- Passing the happy path proves the invariant. Invalid combinations, concurrency, and partial failure challenge it.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Invariant · 2 connections
Read the relationships
- Invariant constrains transitions in Application contract
A contract describes valid boundary behavior; invariants state conditions its accepted transitions must preserve.
- Transaction must preserve Invariant
The chosen transaction and isolation behavior must preserve the domain invariant under concurrent transitions.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (4)
- Invariant: connections
Invariant and its 2 neighboring concepts. Labels state the authored relationships.
- Deterministic boundary lab
Follow accepted and rejected transitions through a delivery statechart.
Predict first. Which state or guard should prevent the next proposed action, and why?
- ACID transaction lab
Inspect lifecycle and ledger records under failed writes, concurrency, and restart.
Predict first. Which invariant could fail between two application-managed writes?
- CAP partition lab
Compare conflicting writes across a network split under quorum and local-acceptance policies.
Predict first. Can both sides acknowledge a conflicting start operation while preserving the declared invariant?
Follow the idea
- Architecture: valid data combinations
Make invalid combinations explicit.
- Appendix C: durable invariants
Place enforcement at the durable boundary.
Connect the concepts
- Invariant constrains transitions in Application contract
A contract describes valid boundary behavior; invariants state conditions its accepted transitions must preserve.
- Transaction must preserve Invariant
The chosen transaction and isolation behavior must preserve the domain invariant under concurrent transitions.
Find this idea across the book (4)
LatencyEvidence Elapsed time between a declared start and completion event. Explore concept Group member
Evidence
Latency
- Definition
- Elapsed time between a declared start and completion event. End-to-end latency can include waiting, processing, network transfer, and rendering.
- Assumptions
- State the timing boundary and population. Averages and percentiles answer different questions; Little's Law uses an average, not p95. A timeout is a deadline lower bound, not an observed completion time.
- Worked example
- Of 20 requests, 18 take 40 ms and two take 240 ms. Mean latency is 60 ms; nearest-rank p95 is 240 ms. A goal below 120 ms passes for the mean and fails for p95.
- Common mistake
- A lower average guarantees a better experience for everyone. A slow minority, failures, or work omitted from the timer can be hidden by that average.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Latency · 6 connections
Read the relationships
- Measurement boundary defines timing scope of Latency
The measurement boundary defines which waiting and processing latency includes.
- Queue can add waiting time to Latency
Waiting in a queue contributes to latency when the queue is inside the timing boundary.
- Little's Law uses average Latency
Little's Law uses average time inside the boundary, not a tail percentile such as p95.
- Latency Tail latency mean vs tail
Tail latency describes slow outcomes that an average elapsed time can hide.
- Rendering and activation can affect Latency
Moving rendering or activation changes which work lies on the measured user journey.
- Consistency can add delay to Latency
Coordinating remote state can add latency; permitting delayed observations changes the consumer's contract.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (6)
- Latency: connections
Latency and its 6 neighboring concepts. Labels state the authored relationships.
- Web architecture lens
Compare page navigation, HTML fragments, and browser-built views for the same operation.
Predict first. Which local state might be lost when an action causes a full-page navigation?
- Tail latency simulator
Compare average latency and p95 when a minority of requests take a slow path.
Predict first. Will the average and p95 cross the objective together when only a minority of requests become slow?
- Browser performance workbench
Measure total time and instrumented JavaScript slices while yielding or blocking the main thread.
Predict first. Which strategy will have the shorter total time, and which the shorter longest JavaScript slice?
- OpenTelemetry trace explorer
Inspect spans, timing, and retries within a simulated server request trace.
Predict first. Which span would account for the additional time in the slow or retried request?
- Latency budget map
Estimate latency contributions from geography, round trips, and execution time.
Predict first. Which will matter more in your scenario: faster query execution or fewer sequential remote round trips?
Follow the idea
- Measurement: calculate the average and tail
Compare a mean with a declared percentile convention.
- Scaling: latency and geography
Follow time across network and consistency boundaries.
Connect the concepts
- Measurement boundary defines timing scope of Latency
The measurement boundary defines which waiting and processing latency includes.
- Queue can add waiting time to Latency
Waiting in a queue contributes to latency when the queue is inside the timing boundary.
- Little's Law uses average Latency
Little's Law uses average time inside the boundary, not a tail percentile such as p95.
- Latency Tail latency mean vs tail
Tail latency describes slow outcomes that an average elapsed time can hide.
- Rendering and activation can affect Latency
Moving rendering or activation changes which work lies on the measured user journey.
- Consistency can add delay to Latency
Coordinating remote state can add latency; permitting delayed observations changes the consumer's contract.
Find this idea across the book (3)
Little's LawModels For a stable conserved-work boundary, average work in progress L equals completion rate λ multiplied by average time in the boundary W: L = λW. Explore concept Group member
Models
Little's Law
- Definition
- For a stable conserved-work boundary, average work in progress L equals completion rate λ multiplied by average time in the boundary W: L = λW.
- Assumptions
- Use the same work, boundary, compatible windows, and units. Arrivals and completions must approximately balance over a suitable observation period. Include waiting when it is inside the boundary.
- Worked example
- At 20 completed events/s and 0.5 s per event, expected average work in progress is 10 events. At four accepted changes/hour and three hours per change, it is 12 changes. These are illustrative steady-state calculations, not measured capacity.
- Common mistake
- A mismatch proves the database is the bottleneck, or matching values prove the system is healthy. The relationship checks consistency; it does not isolate a cause or establish an acceptable waiting time.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Little's Law · 4 connections
Read the relationships
- Little's Law requires a shared Measurement boundary
Little's Law requires work in progress, rate, and average time to describe the same boundary.
- Little's Law accounts for work in Queue
Little's Law connects stable work in progress, including queued and processing work, to rate and average time.
- Little's Law Amdahl's Law different questions
Little's Law checks stable flow averages; Amdahl's Law bounds ideal fixed-workload parallel speedup.
- Little's Law uses average Latency
Little's Law uses average time inside the boundary, not a tail percentile such as p95.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (1)
- Little's Law: connections
Little's Law and its 4 neighboring concepts. Labels state the authored relationships.
Follow the idea
- Measurement: check compatible averages
Calculate the relationship and inspect what a mismatch means.
- Scaling: choose the question before the equation
Distinguish consistency of flow from a bound on parallel speedup.
Connect the concepts
- Little's Law requires a shared Measurement boundary
Little's Law requires work in progress, rate, and average time to describe the same boundary.
- Little's Law accounts for work in Queue
Little's Law connects stable work in progress, including queued and processing work, to rate and average time.
- Little's Law Amdahl's Law different questions
Little's Law checks stable flow averages; Amdahl's Law bounds ideal fixed-workload parallel speedup.
- Little's Law uses average Latency
Little's Law uses average time inside the boundary, not a tail percentile such as p95.
Find this idea across the book (4)
Loop engineeringDevelopment The design of control structures that repeatedly direct agent work toward a declared goal, using observations, retained state, bounded actions and resources, and explicit acceptance, stopping, and escalation rules. Explore concept Group member
Development
Loop engineering
- Definition
- The design of control structures that repeatedly direct agent work toward a declared goal, using observations, retained state, bounded actions and resources, and explicit acceptance, stopping, and escalation rules.
- Usage in this book
- Loop engineering is an emerging practitioner term. This book includes bounded goal-driven iteration as well as recurring agent runs. Lulla and colleagues use a narrower definition requiring scheduled or event-triggered recurrence. The label does not establish that greater autonomy improves outcomes.
- Assumptions
- Name the trigger, goal, permitted actions, state owner, evidence, budget, and human acceptance responsibility. Retain relevant progress between iterations or runs; recurrence and delegation are separate design choices.
- Worked example
- A CSV-export repair loop gives an agent the failing input and a bounded task, records the attempted fix, and checks downloaded rows against permitted events and fields. It returns evidence for acceptance or escalates when the repair budget is exhausted.
- Common mistake
- Repeating a prompt, adding a schedule, or assigning another reviewer guarantees improvement. A loop can repeatedly pursue the wrong goal or pass checks that share its mistaken assumptions.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Loop engineering · 8 connections
Read the relationships
- Loop engineering designs agent use of Feedback loop
Loop engineering chooses the observations and responses that guide agent work; a feedback loop describes how effects influence subsequent behavior, including harmful reinforcing cycles.
- Project harness supplies controls for Loop engineering
The project harness supplies maintained instructions, environments, and checks that loop engineering connects to task initiation, progress, repair, and acceptance.
- Acceptance criteria define outcomes for Loop engineering
Acceptance criteria define the result a loop should pursue. A stop condition can also terminate an unsuccessful run at its budget or escalation boundary.
- Action authorization bounds actions in Loop engineering
A loop may continue only within the granted action authority; starting another iteration or run does not expand permissions.
- Observability supplies evidence for Loop engineering
Recorded inputs, tool outcomes, failures, and state changes help explain why the loop continued, stopped, or escalated; a successful job status alone can hide an idle or ineffective run.
- Agent evaluation assesses outcomes of Loop engineering
Representative tasks and independent acceptance evidence can assess a loop change while accounting for retries, resource cost, and human correction.
- Loop engineering can coordinate Agent fleet
A loop can assign and verify work across a fleet, but one agent can also operate inside a designed loop. Delegation adds coordination and integration obligations.
- Review capacity constrains admission in Loop engineering
Loop design must account for the owner's capacity to review, correct, and accept work; more autonomous runs can otherwise accumulate an unreviewed backlog.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (2)
- Loop engineering: connections
Loop engineering and its 8 neighboring concepts. Labels state the authored relationships.
- Three connected scalability loops
Pressure becomes development work; accepted agent-assisted change alters the application and its next likely limit.
Follow the idea
- Development: design the loop
Distinguish loop design from feedback and harness infrastructure.
- Appendix A: research and evidence
Separate adoption evidence, refinement experiments, and claims about developer effort.
- Friction: match feedback to the boundary
Choose useful repair feedback without weakening final acceptance.
- Fleets: choose coordination deliberately
Add delegation only when the task and acceptance arrangement justify it.
Connect the concepts
- Loop engineering designs agent use of Feedback loop
Loop engineering chooses the observations and responses that guide agent work; a feedback loop describes how effects influence subsequent behavior, including harmful reinforcing cycles.
- Project harness supplies controls for Loop engineering
The project harness supplies maintained instructions, environments, and checks that loop engineering connects to task initiation, progress, repair, and acceptance.
- Acceptance criteria define outcomes for Loop engineering
Acceptance criteria define the result a loop should pursue. A stop condition can also terminate an unsuccessful run at its budget or escalation boundary.
- Action authorization bounds actions in Loop engineering
A loop may continue only within the granted action authority; starting another iteration or run does not expand permissions.
- Observability supplies evidence for Loop engineering
Recorded inputs, tool outcomes, failures, and state changes help explain why the loop continued, stopped, or escalated; a successful job status alone can hide an idle or ineffective run.
- Agent evaluation assesses outcomes of Loop engineering
Representative tasks and independent acceptance evidence can assess a loop change while accounting for retries, resource cost, and human correction.
- Loop engineering can coordinate Agent fleet
A loop can assign and verify work across a fleet, but one agent can also operate inside a designed loop. Delegation adds coordination and integration obligations.
- Review capacity constrains admission in Loop engineering
Loop design must account for the owner's capacity to review, correct, and accept work; more autonomous runs can otherwise accumulate an unreviewed backlog.
Find this idea across the book (7)
Lusser's LawModels For a chain that requires every stage to succeed, independent stage success probabilities multiply to give the chain's success probability. Explore concept Group member
Models
Lusser's Law
- Definition
- For a chain that requires every stage to succeed, independent stage success probabilities multiply to give the chain's success probability.
- Assumptions
- Define an eligible end-to-end attempt and the success criterion at each stage. Independence is a strong assumption; conditional stage success can describe a chain without assuming independence.
- Worked example
- If three required stages each independently succeed with probability 0.99, chain success is 0.99³, about 0.9703. A shared outage invalidates the independence assumption.
- Common mistake
- High component reliability guarantees equally high journey reliability. Required stages accumulate failure opportunities, and common causes can change the calculation.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Lusser's Law · 2 connections
Read the relationships
- Lusser's Law calculates chain Reliability
Lusser's Law calculates a required-stage chain's reliability under a declared independence assumption.
- Application contract defines required stages for Lusser's Law
The reliability chain includes the stages that must succeed to meet the declared end-to-end contract.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (2)
- Lusser's Law: connections
Lusser's Law and its 2 neighboring concepts. Labels state the authored relationships.
- Reliability chain lab
Calculate a required-stage chain's reliability under explicit independence and repair assumptions.
Predict first. How will doubling the required step count affect end-to-end success if per-step behavior stays fixed?
Follow the idea
- Appendix E: reliability chain
Declare the chain and denominator.
- Appendix E: test independence
Inspect shared failure rather than assuming it away.
Connect the concepts
- Lusser's Law calculates chain Reliability
Lusser's Law calculates a required-stage chain's reliability under a declared independence assumption.
- Application contract defines required stages for Lusser's Law
The reliability chain includes the stages that must succeed to meet the declared end-to-end contract.
Find this idea across the book (2)
Maintainability assessmentEvidence An assessment of the effort and effectiveness of understanding, changing, and validating software. Explore concept Group member
Evidence
Maintainability assessment
- Definition
- An assessment of the effort and effectiveness of understanding, changing, and validating software. This course gathers evidence through a bounded change task performed by an unfamiliar maintainer.
- Usage in this book
- Change probe names this course's task-based maintainability assessment protocol. One task supplies evidence about that change under the recorded conditions; it is not a complete maintainability assessment or a standardized score.
- Assumptions
- Declare the starting version, task, auditor familiarity, completion criteria, and effort boundary. One probe does not represent all future maintenance.
- Worked example
- Ask another team to add one event filter. Record where they looked, what contracts they changed, validation effort, and the accepted result.
- Common mistake
- A system with passing behavior tests is necessarily easy to change. Navigability and the next-change cost need separate evidence.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Maintainability assessment · 5 connections
Read the relationships
- Maintainability assessment assesses Decision reversibility
A bounded change probe can test how much effort a revision requires and which dependencies make a decision hard to change.
- Maintainability assessment assesses Development friction
A bounded change probe records concrete blockages and effort so a friction claim can be tested by an unfamiliar maintainer.
- Maintainability assessment can reveal Technical debt
A bounded change probe can expose coupling or earlier shortcuts that make a later modification costly even when current behavior tests pass. Use that evidence to distinguish debt from necessary compatibility work.
- Agent evaluation can include Maintainability assessment
An agent evaluation can include next-change tasks to assess maintainability beyond initial task success.
- Reproducible environment supports repeatable Maintainability assessment
An unfamiliar auditor needs a reproducible starting environment to distinguish setup friction from change difficulty.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (1)
- Maintainability assessment: connections
Maintainability assessment and its 5 neighboring concepts. Labels state the authored relationships.
Follow the idea
- Project: change-probe protocol
Bound the audit and preserve comparable evidence.
- Appendix A: next-change cost
Evaluate maintainability beyond first-pass success.
Connect the concepts
- Maintainability assessment assesses Decision reversibility
A bounded change probe can test how much effort a revision requires and which dependencies make a decision hard to change.
- Maintainability assessment assesses Development friction
A bounded change probe records concrete blockages and effort so a friction claim can be tested by an unfamiliar maintainer.
- Maintainability assessment can reveal Technical debt
A bounded change probe can expose coupling or earlier shortcuts that make a later modification costly even when current behavior tests pass. Use that evidence to distinguish debt from necessary compatibility work.
- Agent evaluation can include Maintainability assessment
An agent evaluation can include next-change tasks to assess maintainability beyond initial task success.
- Reproducible environment supports repeatable Maintainability assessment
An unfamiliar auditor needs a reproducible starting environment to distinguish setup friction from change difficulty.
Measurement boundaryEvidence The declared start, end, population, and observation window of a measurement. Explore concept Group member
Evidence
Measurement boundary
- Definition
- The declared start, end, population, and observation window of a measurement. A boundary determines which work and waiting the result includes.
- Usage in this book
- Measurement boundary is the book's descriptive label for a measurement's scope and timing convention, rather than a separate formal model.
- Assumptions
- Comparisons and equations must describe compatible work, units, and windows. Record failed, rejected, and unfinished work alongside successful completions.
- Worked example
- An event takes 20 ms inside the database but 200 ms from submission to visible activity. The database timer leaves out network, application, queue, and rendering time; it cannot establish the end-to-end latency.
- Common mistake
- A faster component proves a faster user journey. Work outside the measured component can dominate or become slower.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Measurement boundary · 5 connections
Read the relationships
- Measurement boundary defines timing scope of Latency
The measurement boundary defines which waiting and processing latency includes.
- Little's Law requires a shared Measurement boundary
Little's Law requires work in progress, rate, and average time to describe the same boundary.
- Benchmark protocol declares Measurement boundary
A benchmark protocol declares the boundary at which elapsed time and completed work are counted.
- Observability Measurement boundary matched signals
Useful signals must identify the same logical work and boundaries as the outcome being explained.
- Reliability requires a declared Measurement boundary
A reliability claim needs a declared eligible-attempt denominator and end-to-end success boundary.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (7)
- Measurement boundary: connections
Measurement boundary and its 5 neighboring concepts. Labels state the authored relationships.
- From pressure to bounded evidence
A scaling response remains a hypothesis until bounded evidence challenges the maintained goal, limit, and trade-off.
- Tail latency simulator
Compare average latency and p95 when a minority of requests take a slow path.
Predict first. Will the average and p95 cross the objective together when only a minority of requests become slow?
- Browser performance workbench
Measure total time and instrumented JavaScript slices while yielding or blocking the main thread.
Predict first. Which strategy will have the shorter total time, and which the shorter longest JavaScript slice?
- OpenTelemetry trace explorer
Inspect spans, timing, and retries within a simulated server request trace.
Predict first. Which span would account for the additional time in the slow or retried request?
- Reliability chain lab
Calculate a required-stage chain's reliability under explicit independence and repair assumptions.
Predict first. How will doubling the required step count affect end-to-end success if per-step behavior stays fixed?
- Latency budget map
Estimate latency contributions from geography, round trips, and execution time.
Predict first. Which will matter more in your scenario: faster query execution or fewer sequential remote round trips?
Follow the idea
- Measurement: declare the protocol
Specify what starts and ends each observation.
- Scaling: test where the cost moved
Keep the original outcome visible after changing a component.
Connect the concepts
- Measurement boundary defines timing scope of Latency
The measurement boundary defines which waiting and processing latency includes.
- Little's Law requires a shared Measurement boundary
Little's Law requires work in progress, rate, and average time to describe the same boundary.
- Benchmark protocol declares Measurement boundary
A benchmark protocol declares the boundary at which elapsed time and completed work are counted.
- Observability Measurement boundary matched signals
Useful signals must identify the same logical work and boundaries as the outcome being explained.
- Reliability requires a declared Measurement boundary
A reliability claim needs a declared eligible-attempt denominator and end-to-end success boundary.
Network partitionOperations A disruption that prevents some nodes from communicating while they may continue running and accepting local work. Explore concept Group member
Operations
Network partition
- Definition
- A disruption that prevents some nodes from communicating while they may continue running and accepting local work.
- Assumptions
- Specify the operation, consistency promise, and what each side may accept. A partition requires an operational choice about unavailable or divergent work.
- Worked example
- Two regions cannot coordinate workspace writes. Either reject or delay some operations to preserve the declared consistency, or accept a weaker promise and reconciliation obligations.
- Common mistake
- A deployment can freely choose consistency and availability as independent switches during a partition. The operation's contract constrains the choice.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Network partition · 2 connections
Read the relationships
- Consistency constrains acceptance during Network partition
During a partition, the operation's consistency promise constrains which work disconnected nodes may accept.
- Recovery reconciles histories after Network partition
Recovery from a partition may require reconciling divergent histories and draining pending work.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (2)
- Network partition: connections
Network partition and its 2 neighboring concepts. Labels state the authored relationships.
- CAP partition lab
Compare conflicting writes across a network split under quorum and local-acceptance policies.
Predict first. Can both sides acknowledge a conflicting start operation while preserving the declared invariant?
Follow the idea
- Scaling: operational choice
Explain the consequences for the tracker.
- Appendix C: partition proof and lab
Examine the guarantees and compare two partition policies.
- Pressure: documented incidents
Follow divergent histories during a real partition.
Connect the concepts
- Consistency constrains acceptance during Network partition
During a partition, the operation's consistency promise constrains which work disconnected nodes may accept.
- Recovery reconciles histories after Network partition
Recovery from a partition may require reconciling divergent histories and draining pending work.
Find this idea across the book (2)
ObservabilityEvidence The capability to use telemetry to investigate system behavior across boundaries, including failures not anticipated when the system was instrumented. Explore concept Group member
Evidence
Observability
- Definition
- The capability to use telemetry to investigate system behavior across boundaries, including failures not anticipated when the system was instrumented.
- Assumptions
- Telemetry supplies evidence such as metrics, logs, and traces. Choose signals from the question and connect them with operation identity, time, and boundary; collecting signals alone does not establish observability or a cause.
- Worked example
- For a duplicated event after a timeout, join the command identifier, request trace, commit result, retry, and visible activity. Healthy HTTP success alone misses the duplicate.
- Common mistake
- Collecting many logs establishes the cause. Signals need a coherent question and a traceable connection to the user outcome.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Observability · 5 connections
Read the relationships
- Observability supplies evidence for Loop engineering
Recorded inputs, tool outcomes, failures, and state changes help explain why the loop continued, stopped, or escalated; a successful job status alone can hide an idle or ineffective run.
- Observability can help explain Tail latency
Latency distributions reveal a slow population; traces and event records help investigate its path.
- Observability Measurement boundary matched signals
Useful signals must identify the same logical work and boundaries as the outcome being explained.
- Observability provides evidence for Recovery
Recovery needs evidence about authoritative state, pending work, and user-visible outcomes, not only process health.
- Observability supplies signals for Feedback loop
A corrective feedback loop can choose a useful response only when its signals describe the relevant goal and boundary.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (3)
- Observability: connections
Observability and its 5 neighboring concepts. Labels state the authored relationships.
- OpenTelemetry trace explorer
Inspect spans, timing, and retries within a simulated server request trace.
Predict first. Which span would account for the additional time in the slow or retried request?
- Fleet trace debugger
Reconcile orchestration intent, gateway decisions, and the physical execution ledger.
Predict first. Which records prove execution, and which express only an intended or authorized action?
Follow the idea
Explore through a course task (2)
- Compare evidence for an agent repair
Saving an event reports success, but the list stays unchanged. Compare task feedback, runtime logs, and a diagnostic brief.
- Follow a fix into running systems
A release succeeds and every health check passes. Decide what the runtime inventory still requires you to investigate.
- Pressure: trace a failure
Join symptoms, policies, and authoritative outcomes.
- Measurement: signal selection
Use telemetry and the trace explorer to investigate behavior.
Connect the concepts
- Observability supplies evidence for Loop engineering
Recorded inputs, tool outcomes, failures, and state changes help explain why the loop continued, stopped, or escalated; a successful job status alone can hide an idle or ineffective run.
- Observability can help explain Tail latency
Latency distributions reveal a slow population; traces and event records help investigate its path.
- Observability Measurement boundary matched signals
Useful signals must identify the same logical work and boundaries as the outcome being explained.
- Observability provides evidence for Recovery
Recovery needs evidence about authoritative state, pending work, and user-visible outcomes, not only process health.
- Observability supplies signals for Feedback loop
A corrective feedback loop can choose a useful response only when its signals describe the relevant goal and boundary.
Find this idea across the book (4)
Project harnessDevelopment The versioned project instructions, specifications, architecture notes, environment, commands, and checks that make candidate changes inspectable and repeatable. Explore concept Group member
Development
Project harness
- Definition
- The versioned project instructions, specifications, architecture notes, environment, commands, and checks that make candidate changes inspectable and repeatable.
- Usage in this book
- Project harness is the book's name for this bundle of repository guidance and executable development controls. Harness terminology is still developing. The bundle supports the development workflow; the wider development system also includes people, review, integration, and ownership.
- Assumptions
- Keep the project harness distinct from an agent execution harness and an evaluation harness. Controls must be executable and maintained as the project changes.
- Worked example
- Pinned versions, a documented test command, contract tests, and a review gate let an agent and an unfamiliar human validate the same event change.
- Common mistake
- A long instruction file makes the workflow controlled. Instructions require enforceable checks and an owner for acceptance.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Project harness · 7 connections
Read the relationships
- Project harness supplies controls for Loop engineering
The project harness supplies maintained instructions, environments, and checks that loop engineering connects to task initiation, progress, repair, and acceptance.
- Decision log Project harness accepted context
Decision records preserve accepted project context, while current specifications and executable harness checks must reflect the implemented choice.
- Project harness supplies checks for Agent evaluation
The project harness supplies reusable checks and setup, while the evaluation harness provisions and scores trials.
- Project harness supplies context for Coding agent
An agent's useful capability depends on the project context, tools, checks, and commands supplied by its harness.
- Project harness provides checks for Feedback loop
Executable harness checks turn generated work into feedback that can guide a revision.
- Project harness requires a declared Reproducible environment
A harness needs a declared environment so its checks can be run by another agent or maintainer.
- Project harness provides evidence for Acceptance criteria
Harness checks provide repeatable evidence for acceptance criteria, while a named owner remains accountable for acceptance.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (2)
- Project harness: connections
Project harness and its 7 neighboring concepts. Labels state the authored relationships.
- Knowledge and artifact ownership
Reusable source knowledge stays external; Slideotter and Kirjolab own their artifact-specific decisions.
Follow the idea
- Development: the project harness
Connect instructions with executable controls.
- Kirjolab: prepare before feature pressure
See a harness support rapid delivery.
Connect the concepts
- Project harness supplies controls for Loop engineering
The project harness supplies maintained instructions, environments, and checks that loop engineering connects to task initiation, progress, repair, and acceptance.
- Decision log Project harness accepted context
Decision records preserve accepted project context, while current specifications and executable harness checks must reflect the implemented choice.
- Project harness supplies checks for Agent evaluation
The project harness supplies reusable checks and setup, while the evaluation harness provisions and scores trials.
- Project harness supplies context for Coding agent
An agent's useful capability depends on the project context, tools, checks, and commands supplied by its harness.
- Project harness provides checks for Feedback loop
Executable harness checks turn generated work into feedback that can guide a revision.
- Project harness requires a declared Reproducible environment
A harness needs a declared environment so its checks can be run by another agent or maintainer.
- Project harness provides evidence for Acceptance criteria
Harness checks provide repeatable evidence for acceptance criteria, while a named owner remains accountable for acceptance.
Find this idea across the book (14)
QueueOperations Work waiting for a resource or a next stage. Explore concept Group member
Operations
Queue
- Definition
- Work waiting for a resource or a next stage. A queue may contain events awaiting a worker or changes awaiting review; work in progress also includes work currently being processed.
- Assumptions
- Name what enters, what leaves, capacity, and the policy for full or abandoned work. A sustained arrival rate above completion capacity cannot produce a stable backlog.
- Worked example
- Admitting 120 events/s to a worker completing 100 events/s adds 20 pending events/s under a constant-rate model without loss or retries. Six changes arriving per hour with four accepted per hour add two unfinished changes per hour if none leave through rejection or withdrawal. These illustrative rates are not measured capacity.
- Common mistake
- Adding a queue creates processing capacity. It can absorb a bounded burst or decouple stages, but it also creates waiting, recovery, and admission obligations.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Queue · 6 connections
Read the relationships
- Queue can add waiting time to Latency
Waiting in a queue contributes to latency when the queue is inside the timing boundary.
- Throughput Queue arrivals and exits
Compare admissions with all departures at the queue boundary to explain backlog growth. Useful throughput separately counts completions that meet the declared outcome criteria.
- Queue can signal Saturation
A growing queue can expose pressure above completion capacity, even while acknowledgments remain fast.
- Little's Law accounts for work in Queue
Little's Law connects stable work in progress, including queued and processing work, to rate and average time.
- Review capacity Queue review backlog
Candidate changes waiting for review form a queue. Its growth depends on submissions and all departures, including rejection or withdrawal; accepted-change throughput counts only successful acceptance.
- Admission and backpressure can bound admission to Queue
A bounded queue requires a policy for slowing or rejecting new work when downstream capacity cannot keep up.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (3)
- Queue: connections
Queue and its 6 neighboring concepts. Labels state the authored relationships.
- Three connected scalability loops
Pressure becomes development work; accepted agent-assisted change alters the application and its next likely limit.
- Saturation boundary lab
Compare offered, admitted and completed event rates and move the binding limit.
Predict first. If you raise only the database capacity, which stage will limit completion next?
Follow the idea
Explore through a course task (1)
- Vary human work in progress
Keep the same worker limit while changing how many unfinished changes enter the workflow. Plan a bounded comparison.
- Measurement: transfer the boundary to review work
Apply the same relationship with different work and units.
- Recap: a queue changes three loops
Connect application backlog to implementation and review work.
Connect the concepts
- Queue can add waiting time to Latency
Waiting in a queue contributes to latency when the queue is inside the timing boundary.
- Throughput Queue arrivals and exits
Compare admissions with all departures at the queue boundary to explain backlog growth. Useful throughput separately counts completions that meet the declared outcome criteria.
- Queue can signal Saturation
A growing queue can expose pressure above completion capacity, even while acknowledgments remain fast.
- Little's Law accounts for work in Queue
Little's Law connects stable work in progress, including queued and processing work, to rate and average time.
- Review capacity Queue review backlog
Candidate changes waiting for review form a queue. Its growth depends on submissions and all departures, including rejection or withdrawal; accepted-change throughput counts only successful acceptance.
- Admission and backpressure can bound admission to Queue
A bounded queue requires a policy for slowing or rejecting new work when downstream capacity cannot keep up.
Find this idea across the book (4)
RecoveryOperations The prepared path from a disrupted state back to useful, correct service, including restored capacity, authoritative state, and backlog handling. Explore concept Group member
Operations
Recovery
- Definition
- The prepared path from a disrupted state back to useful, correct service, including restored capacity, authoritative state, and backlog handling.
- Assumptions
- Check whether recovery tools depend on the failed service. Preserve operation identity and state integrity while replaying or draining work.
- Worked example
- Restore the worker, then observe queue age and visible event freshness until the backlog drains. A healthy process alone does not establish recovery.
- Common mistake
- Restarting the endpoint ends the incident. Stale copies, duplicates, blocked tools, and pending work may persist.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Recovery · 5 connections
Read the relationships
- Decision reversibility Recovery safe reversal
Reversing a decision after durable effects may require migration or reconciliation; restoring code alone does not establish safe recovery.
- Observability provides evidence for Recovery
Recovery needs evidence about authoritative state, pending work, and user-visible outcomes, not only process health.
- Retry policy supports bounded replay in Recovery
Bounded retry and backlog replay policies must protect state integrity and capacity during recovery.
- Durable workflow preserves progress for Recovery
Preserved workflow progress helps interrupted coordination resume, but recovery must still audit its effects.
- Recovery reconciles histories after Network partition
Recovery from a partition may require reconciling divergent histories and draining pending work.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (6)
- Recovery: connections
Recovery and its 5 neighboring concepts. Labels state the authored relationships.
- An external quota becomes the availability boundary
Production traffic was amplified into GitHub API traffic until one external quota became the availability boundary for the whole site.
- ACID transaction lab
Inspect lifecycle and ledger records under failed writes, concurrency, and restart.
Predict first. Which invariant could fail between two application-managed writes?
- Orchestration control loop
Follow controller actions that reconcile observed replicas with desired state.
Predict first. After losing a replica, what discrepancy should the controller observe and what action should follow?
- Durable effect retry lab
Stop a worker after an external effect but before its completion enters durable history.
Predict first. If the receiver applied the effect but completion was not recorded, what could make a retry apply it twice?
- CAP partition lab
Compare conflicting writes across a network split under quorum and local-acceptance policies.
Predict first. Can both sides acknowledge a conflicting start operation while preserving the declared invariant?
Follow the idea
Explore through a course task (1)
- Follow a fix into running systems
A release succeeds and every health check passes. Decide what the runtime inventory still requires you to investigate.
- Pressure: recovery is architecture
Prepare the path before the disturbance.
- Thesis tracker: recovery features
See recovery become part of the product.
Connect the concepts
- Decision reversibility Recovery safe reversal
Reversing a decision after durable effects may require migration or reconciliation; restoring code alone does not establish safe recovery.
- Observability provides evidence for Recovery
Recovery needs evidence about authoritative state, pending work, and user-visible outcomes, not only process health.
- Retry policy supports bounded replay in Recovery
Bounded retry and backlog replay policies must protect state integrity and capacity during recovery.
- Durable workflow preserves progress for Recovery
Preserved workflow progress helps interrupted coordination resume, but recovery must still audit its effects.
- Recovery reconciles histories after Network partition
Recovery from a partition may require reconciling divergent histories and draining pending work.
Find this idea across the book (4)
ReliabilityModels The probability or observed proportion of successful outcomes under a declared workload, environment, time horizon, and success criterion. Explore concept Group member
Models
Reliability
- Definition
- The probability or observed proportion of successful outcomes under a declared workload, environment, time horizon, and success criterion.
- Assumptions
- Include all eligible attempts in the denominator and state uncertainty. Agent first-attempt success and eventual success with retries answer different questions.
- Worked example
- A task succeeds on 18 of 20 independent trials under one fixed configuration. Report the trials and uncertainty rather than claiming a general 90% guarantee.
- Common mistake
- One successful run establishes reliability, or success after repeated attempts implies first-attempt reliability.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Reliability · 3 connections
Read the relationships
- Agent evaluation estimates Reliability
Repeated agent evaluation distinguishes a successful example from evidence about success frequency and uncertainty.
- Lusser's Law calculates chain Reliability
Lusser's Law calculates a required-stage chain's reliability under a declared independence assumption.
- Reliability requires a declared Measurement boundary
A reliability claim needs a declared eligible-attempt denominator and end-to-end success boundary.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (3)
- Reliability: connections
Reliability and its 3 neighboring concepts. Labels state the authored relationships.
- An external quota becomes the availability boundary
Production traffic was amplified into GitHub API traffic until one external quota became the availability boundary for the whole site.
- Reliability chain lab
Calculate a required-stage chain's reliability under explicit independence and repair assumptions.
Predict first. How will doubling the required step count affect end-to-end success if per-step behavior stays fixed?
Follow the idea
- Appendix A: uncertainty and trials
Choose a success summary that matches the question.
- Appendix E: eligible attempts
Preserve the denominator across the journey.
Connect the concepts
- Agent evaluation estimates Reliability
Repeated agent evaluation distinguishes a successful example from evidence about success frequency and uncertainty.
- Lusser's Law calculates chain Reliability
Lusser's Law calculates a required-stage chain's reliability under a declared independence assumption.
- Reliability requires a declared Measurement boundary
A reliability claim needs a declared eligible-attempt denominator and end-to-end success boundary.
Find this idea across the book (2)
Rendering and activationArchitecture Rendering creates a representation; activation connects that representation to interactive behavior. Explore concept Group member
Architecture
Rendering and activation
- Definition
- Rendering creates a representation; activation connects that representation to interactive behavior. Their work can occur at different times and locations.
- Assumptions
- Trace data authority, representation freshness, delivered assets, and activation cost separately. A visible interface is not necessarily ready to act.
- Worked example
- A static activity page arrives quickly, but client listeners and data must initialize before its filter works. Move work only after measuring the user journey.
- Common mistake
- Server rendering, client rendering, or hydration is universally fastest. The workload and interaction boundary determine the result.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Rendering and activation · 3 connections
Read the relationships
- Rendering and activation can affect Latency
Moving rendering or activation changes which work lies on the measured user journey.
- Rendering and activation Cache freshness and activation
A cached representation needs freshness and activation policies in addition to a fast delivery path.
- Rendering and activation Authoritative state view vs durable state
Rendering a representation must remain distinct from committing the durable action it displays.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (3)
- Rendering and activation: connections
Rendering and activation and its 3 neighboring concepts. Labels state the authored relationships.
- Web architecture lens
Compare page navigation, HTML fragments, and browser-built views for the same operation.
Predict first. Which local state might be lost when an action causes a full-page navigation?
- Browser performance workbench
Measure total time and instrumented JavaScript slices while yielding or blocking the main thread.
Predict first. Which strategy will have the shorter total time, and which the shorter longest JavaScript slice?
Follow the idea
- Architecture: move rendering work
Compare representation delivery choices.
- Appendix C: activate an interface
Distinguish rendering from activation.
Connect the concepts
- Rendering and activation can affect Latency
Moving rendering or activation changes which work lies on the measured user journey.
- Rendering and activation Cache freshness and activation
A cached representation needs freshness and activation policies in addition to a fast delivery path.
- Rendering and activation Authoritative state view vs durable state
Rendering a representation must remain distinct from committing the durable action it displays.
Find this idea across the book (2)
Reproducible environmentDevelopment A declared setup that allows another run or maintainer to recreate the dependencies and conditions relevant to a result. Explore concept Group member
Development
Reproducible environment
- Definition
- A declared setup that allows another run or maintainer to recreate the dependencies and conditions relevant to a result.
- Assumptions
- Choose the necessary strength: pinned versions, containers, or stronger isolation as the claim requires. Seeds and versions do not remove all nondeterminism.
- Worked example
- The auditor uses the documented runtime, lockfile, database seed, and test commands to reproduce an event-feed failure from a clean checkout.
- Common mistake
- It works on one laptop, so the result is reproducible. Hidden services, mutable dependencies, and undeclared state can invalidate that inference.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Reproducible environment · 4 connections
Read the relationships
- Reproducible environment can reduce Development friction
A declared, reproducible environment can reduce setup friction and reveal hidden inputs rather than relying on undocumented repairs.
- Reproducible environment supports repeatable Benchmark protocol
Reproducible environments help separate implementation differences from setup differences in a benchmark.
- Reproducible environment supports repeatable Maintainability assessment
An unfamiliar auditor needs a reproducible starting environment to distinguish setup friction from change difficulty.
- Project harness requires a declared Reproducible environment
A harness needs a declared environment so its checks can be run by another agent or maintainer.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (1)
- Reproducible environment: connections
Reproducible environment and its 4 neighboring concepts. Labels state the authored relationships.
Follow the idea
- Friction: version the environment
Treat setup as part of the development boundary.
- Appendix B: choose the strength
Match reproducibility to the experiment.
Connect the concepts
- Reproducible environment can reduce Development friction
A declared, reproducible environment can reduce setup friction and reveal hidden inputs rather than relying on undocumented repairs.
- Reproducible environment supports repeatable Benchmark protocol
Reproducible environments help separate implementation differences from setup differences in a benchmark.
- Reproducible environment supports repeatable Maintainability assessment
An unfamiliar auditor needs a reproducible starting environment to distinguish setup friction from change difficulty.
- Project harness requires a declared Reproducible environment
A harness needs a declared environment so its checks can be run by another agent or maintainer.
Retry policyOperations The rules for attempting work again after failure or an ambiguous result, including limits, delay, deadlines, and operation identity. Explore concept Group member
Operations
Retry policy
- Definition
- The rules for attempting work again after failure or an ambiguous result, including limits, delay, deadlines, and operation identity.
- Assumptions
- Distinguish transient failure from permanent rejection and unknown completion. Bound attempts and preserve retry-safe semantics before adding retries.
- Worked example
- A timeout after commit leaves the client uncertain. Reuse the command key and delay a bounded retry; synchronized immediate retries can overload the recovering dependency.
- Common mistake
- Retrying always improves availability. It can duplicate effects or amplify the pressure that caused the failure.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Retry policy · 4 connections
Read the relationships
- Feedback loop Retry policy reinforcing load
Overload can cause timeouts that trigger retries and add more load. A bounded retry policy with delay and admission control can limit this reinforcing feedback; retry-safe effects are still required.
- Idempotency guards repeated effects of Retry policy
A deduplicated command reuses its logical operation identity after an ambiguous outcome so the retry cannot invent another durable action.
- Retry policy can amplify load at Saturation
Retries can amplify pressure on an already saturated dependency instead of improving useful completion.
- Retry policy supports bounded replay in Recovery
Bounded retry and backlog replay policies must protect state integrity and capacity during recovery.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (3)
- Retry policy: connections
Retry policy and its 4 neighboring concepts. Labels state the authored relationships.
- OpenTelemetry trace explorer
Inspect spans, timing, and retries within a simulated server request trace.
Predict first. Which span would account for the additional time in the slow or retried request?
- Durable effect retry lab
Stop a worker after an external effect but before its completion enters durable history.
Predict first. If the receiver applied the effect but completion was not recorded, what could make a retry apply it twice?
Follow the idea
- Pressure: production assumptions
Account for network ambiguity and retry amplification.
- Appendix F: retry-safe effects
Distinguish workflow progress from effect safety.
Connect the concepts
- Feedback loop Retry policy reinforcing load
Overload can cause timeouts that trigger retries and add more load. A bounded retry policy with delay and admission control can limit this reinforcing feedback; retry-safe effects are still required.
- Idempotency guards repeated effects of Retry policy
A deduplicated command reuses its logical operation identity after an ambiguous outcome so the retry cannot invent another durable action.
- Retry policy can amplify load at Saturation
Retries can amplify pressure on an already saturated dependency instead of improving useful completion.
- Retry policy supports bounded replay in Recovery
Bounded retry and backlog replay policies must protect state integrity and capacity during recovery.
Find this idea across the book (2)
Review capacityDevelopment The finite human attention and integration effort available to evaluate and accept candidate changes. Explore concept Group member
Development
Review capacity
- Definition
- The finite human attention and integration effort available to evaluate and accept candidate changes.
- Usage in this book
- Review capacity applies capacity and queueing ideas to human review and integration. It is not a fixed personal productivity rating; task complexity, review depth, interruptions, and correction work affect the observed capacity.
- Assumptions
- Record review, correction, waiting, acceptance, rejection, and withdrawal at a declared boundary. Human tasks vary; one observation of backlog or accepted output does not establish sustainable capacity.
- Worked example
- In one hour, agents submit six changes and the maintainer accepts four. If none leave through rejection or withdrawal, unfinished work increases by two. Measure over time before treating four accepted changes/hour as sustainable capacity.
- Common mistake
- Review is an overhead that disappears with better generation. Understanding and accountable acceptance remain part of useful throughput.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Review capacity · 6 connections
Read the relationships
- Review capacity constrains admission in Loop engineering
Loop design must account for the owner's capacity to review, correct, and accept work; more autonomous runs can otherwise accumulate an unreviewed backlog.
- Agent fleet Review capacity candidate vs accepted
Additional agents can increase candidate output faster than human review can accept it.
- Review capacity Queue review backlog
Candidate changes waiting for review form a queue. Its growth depends on submissions and all departures, including rejection or withdrawal; accepted-change throughput counts only successful acceptance.
- Review capacity can limit accepted Throughput
Reviewer attention and correction effort can limit accepted-change throughput even when generation speeds up.
- Review capacity Amdahl's Law sequential fraction
Review or integration that must remain sequential belongs in Amdahl's sequential fraction for a fixed task. A growing review queue asks a separate question about ongoing arrival and completion rates.
- Review capacity can be a limit at Saturation
Human review capacity can be the binding limit when candidate work arrives faster than it can be understood, integrated, and accepted. Increasing generation alone does not expand that capacity.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (3)
- Review capacity: connections
Review capacity and its 6 neighboring concepts. Labels state the authored relationships.
- Three connected scalability loops
Pressure becomes development work; accepted agent-assisted change alters the application and its next likely limit.
- Sequential work bound
Inspect the ideal speedup bound when part of a fixed workload stays sequential.
Predict first. With 80% parallelizable work, will increasing from four to eight agents double speedup?
Follow the idea
Explore through a course task (1)
- Vary human work in progress
Keep the same worker limit while changing how many unfinished changes enter the workflow. Plan a bounded comparison.
- Development: generation outruns comprehension
Locate the human constraint.
- Introduction: editorial acceptance
Separate publishing checks from editorial judgment.
Connect the concepts
- Review capacity constrains admission in Loop engineering
Loop design must account for the owner's capacity to review, correct, and accept work; more autonomous runs can otherwise accumulate an unreviewed backlog.
- Agent fleet Review capacity candidate vs accepted
Additional agents can increase candidate output faster than human review can accept it.
- Review capacity Queue review backlog
Candidate changes waiting for review form a queue. Its growth depends on submissions and all departures, including rejection or withdrawal; accepted-change throughput counts only successful acceptance.
- Review capacity can limit accepted Throughput
Reviewer attention and correction effort can limit accepted-change throughput even when generation speeds up.
- Review capacity Amdahl's Law sequential fraction
Review or integration that must remain sequential belongs in Amdahl's sequential fraction for a fixed task. A growing review queue asks a separate question about ongoing arrival and completion rates.
- Review capacity can be a limit at Saturation
Human review capacity can be the binding limit when candidate work arrives faster than it can be understood, integrated, and accepted. Increasing generation alone does not expand that capacity.
SaturationOperations The point at which a limiting resource or capability can no longer absorb more pressure while maintaining the declared goal. Explore concept Group member
Operations
Saturation
- Definition
- The point at which a limiting resource or capability can no longer absorb more pressure while maintaining the declared goal. In this book, the limit can be a physical resource, quota, dependency, or human review capacity.
- Usage in this book
- The book uses saturation across technical and human limits, drawing on resilience engineering's treatment of finite adaptive capacity. Name the limiting capacity in each example; resource utilization alone does not describe every limit.
- Assumptions
- Identify the workload, maintained goal, and limiting resource. Expanding one limit can expose another; rejection or retries can change the observed rates.
- Worked example
- A request visits stages with capacities of 180, 110, 150, and 130 requests/s. With one visit per stage and no retries, the ceiling is 110/s. Raising that stage to 150/s moves the limit to the 130/s stage.
- Common mistake
- Adding capacity to one component removes the system's limit. Another stage can bind first, and a quicker acknowledgment can conceal a growing backlog.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Saturation · 7 connections
Read the relationships
- Saturation bounds sustainable Throughput
The saturated stage bounds the sustainable completion rate for the declared workload.
- Queue can signal Saturation
A growing queue can expose pressure above completion capacity, even while acknowledgments remain fast.
- Saturation can threaten Scalability
Saturation identifies the current limit that threatens the maintained scalability goal.
- Review capacity can be a limit at Saturation
Human review capacity can be the binding limit when candidate work arrives faster than it can be understood, integrated, and accepted. Increasing generation alone does not expand that capacity.
- Retry policy can amplify load at Saturation
Retries can amplify pressure on an already saturated dependency instead of improving useful completion.
- Admission and backpressure can protect capacity at Saturation
Admission controls can protect a saturated boundary while making rejected or delayed work explicit.
- Contention can expose Saturation
Contention can expose a binding shared-resource limit before every worker is fully utilized.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (5)
- Saturation: connections
Saturation and its 7 neighboring concepts. Labels state the authored relationships.
- From pressure to bounded evidence
A scaling response remains a hypothesis until bounded evidence challenges the maintained goal, limit, and trade-off.
- An external quota becomes the availability boundary
Production traffic was amplified into GitHub API traffic until one external quota became the availability boundary for the whole site.
- Saturation boundary lab
Compare offered, admitted and completed event rates and move the binding limit.
Predict first. If you raise only the database capacity, which stage will limit completion next?
- Contention curve lab
Explore a modeled capacity curve as contention and coherency costs change.
Predict first. Will adding workers always increase capacity when coherency cost is nonzero?
Follow the idea
- Pressure: name the binding limit
Connect a disturbance to the limit and its signals.
- Scaling: move the saturation boundary
Test which constraint appears after an intervention.
Connect the concepts
- Saturation bounds sustainable Throughput
The saturated stage bounds the sustainable completion rate for the declared workload.
- Queue can signal Saturation
A growing queue can expose pressure above completion capacity, even while acknowledgments remain fast.
- Saturation can threaten Scalability
Saturation identifies the current limit that threatens the maintained scalability goal.
- Review capacity can be a limit at Saturation
Human review capacity can be the binding limit when candidate work arrives faster than it can be understood, integrated, and accepted. Increasing generation alone does not expand that capacity.
- Retry policy can amplify load at Saturation
Retries can amplify pressure on an already saturated dependency instead of improving useful completion.
- Admission and backpressure can protect capacity at Saturation
Admission controls can protect a saturated boundary while making rejected or delayed work explicit.
- Contention can expose Saturation
Contention can expose a binding shared-resource limit before every worker is fully utilized.
Find this idea across the book (3)
ScalabilityOperations The ability to maintain a declared goal as a relevant pressure changes, within stated constraints. Explore concept Group member
Operations
Scalability
- Definition
- The ability to maintain a declared goal as a relevant pressure changes, within stated constraints.
- Usage in this book
- The book applies scalability to runtime capacity and to development work. For contributors and change, relate the claim to maintainability, evolvability, or coordination as appropriate; name the goal rather than assuming one shared measure of scale.
- Assumptions
- Name the goal, changing pressure, workload, and resources allowed to change. A scalability claim is conditional on these choices.
- Worked example
- The tracker must keep valid-event p95 below 200 ms as offered traffic doubles, without exceeding its operating budget. This is a testable claim; ‘handles many users’ is not.
- Common mistake
- Scalability means maximum traffic. Data growth, more contributors, and frequent change can also threaten the maintained goal.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Scalability · 4 connections
Read the relationships
- Scalability is assessed under Scaling pressure
A scalability claim states which goal must hold as a particular pressure changes.
- Saturation can threaten Scalability
Saturation identifies the current limit that threatens the maintained scalability goal.
- Benchmark protocol tests claims of Scalability
A benchmark protocol makes a conditional scalability claim testable.
- Scalability Trade-off response obligations
A scaling response must justify the costs and obligations it introduces alongside the maintained goal.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (3)
- Scalability: connections
Scalability and its 4 neighboring concepts. Labels state the authored relationships.
- From pressure to bounded evidence
A scaling response remains a hypothesis until bounded evidence challenges the maintained goal, limit, and trade-off.
- Three connected scalability loops
Pressure becomes development work; accepted agent-assisted change alters the application and its next likely limit.
Follow the idea
- Scalability: begin with the goal
State the property that pressure must not break.
- Scaling: choose a response
Connect the changing pressure to an intervention.
Connect the concepts
- Scalability is assessed under Scaling pressure
A scalability claim states which goal must hold as a particular pressure changes.
- Saturation can threaten Scalability
Saturation identifies the current limit that threatens the maintained scalability goal.
- Benchmark protocol tests claims of Scalability
A benchmark protocol makes a conditional scalability claim testable.
- Scalability Trade-off response obligations
A scaling response must justify the costs and obligations it introduces alongside the maintained goal.
Find this idea across the book (7)
Scaling pressureOperations A change in demand, data, contributors, or rate of change that tests the system's ability to maintain its goal. Explore concept Group member
Operations
Scaling pressure
- Definition
- A change in demand, data, contributors, or rate of change that tests the system's ability to maintain its goal.
- Usage in this book
- Scaling pressure is the book's organizing label. Demand, data, contributors, and change are four useful dimensions for this course, not an exhaustive or universally adopted taxonomy.
- Assumptions
- Separate the pressure from its symptom and from the proposed response. Describe the distribution of work, not only its total volume.
- Worked example
- A reconnect burst increases event arrivals while the database size stays constant. A growing activity history can slow queries even with unchanged traffic.
- Common mistake
- ‘We need caching’ names the pressure. It names a response whose relevance still needs evidence.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Scaling pressure · 4 connections
Read the relationships
- Scalability is assessed under Scaling pressure
A scalability claim states which goal must hold as a particular pressure changes.
- Scaling pressure can expose Technical debt
Change pressure can expose future change cost from earlier shortcuts, compromises, or unmanaged coupling. A necessary compatibility obligation alone does not establish technical debt.
- Agent fleet can create Scaling pressure
Adding contributors or agents increases coordination pressure as well as possible parallelism.
- Scaling pressure can motivate Cache
Data or demand pressure may motivate caching, but the cache introduces a freshness and access contract.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (6)
- Scaling pressure: connections
Scaling pressure and its 4 neighboring concepts. Labels state the authored relationships.
- From pressure to bounded evidence
A scaling response remains a hypothesis until bounded evidence challenges the maintained goal, limit, and trade-off.
- An external quota becomes the availability boundary
Production traffic was amplified into GitHub API traffic until one external quota became the availability boundary for the whole site.
- Three connected scalability loops
Pressure becomes development work; accepted agent-assisted change alters the application and its next likely limit.
- Saturation boundary lab
Compare offered, admitted and completed event rates and move the binding limit.
Predict first. If you raise only the database capacity, which stage will limit completion next?
- Orchestration control loop
Follow controller actions that reconcile observed replicas with desired state.
Predict first. After losing a replica, what discrepancy should the controller observe and what action should follow?
Follow the idea
- Scalability: four pressures
Distinguish demand, data, contributors, and change.
- Pressure: identify the binding limit
Trace a disturbance to its signals and limit.
Connect the concepts
- Scalability is assessed under Scaling pressure
A scalability claim states which goal must hold as a particular pressure changes.
- Scaling pressure can expose Technical debt
Change pressure can expose future change cost from earlier shortcuts, compromises, or unmanaged coupling. A necessary compatibility obligation alone does not establish technical debt.
- Agent fleet can create Scaling pressure
Adding contributors or agents increases coordination pressure as well as possible parallelism.
- Scaling pressure can motivate Cache
Data or demand pressure may motivate caching, but the cache introduces a freshness and access contract.
Find this idea across the book (6)
Tail latencyEvidence The slow end of the elapsed-time distribution, often described by a percentile such as p95 or p99. Explore concept Group member
Evidence
Tail latency
- Definition
- The slow end of the elapsed-time distribution, often described by a percentile such as p95 or p99.
- Assumptions
- State the percentile convention, population, sample size, and failure treatment. A small sample cannot precisely characterize rare slow outcomes.
- Worked example
- Eighteen requests at 40 ms and two at 240 ms have a 60 ms mean and a nearest-rank p95 of 240 ms. The mean hides the slow minority.
- Common mistake
- A good mean implies a good tail, or p95 can replace average time in Little's Law. These statistics answer different questions.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Tail latency · 3 connections
Read the relationships
- Benchmark protocol declares how to measure Tail latency
A benchmark needs a declared latency population and percentile convention to support a tail-latency claim.
- Latency Tail latency mean vs tail
Tail latency describes slow outcomes that an average elapsed time can hide.
- Observability can help explain Tail latency
Latency distributions reveal a slow population; traces and event records help investigate its path.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (2)
- Tail latency: connections
Tail latency and its 3 neighboring concepts. Labels state the authored relationships.
- Tail latency simulator
Compare average latency and p95 when a minority of requests take a slow path.
Predict first. Will the average and p95 cross the objective together when only a minority of requests become slow?
Follow the idea
- Measurement: compare mean and tail
Calculate how a slow minority affects the result.
- Scaling: budget latency
Account for the journey across stages.
Connect the concepts
- Benchmark protocol declares how to measure Tail latency
A benchmark needs a declared latency population and percentile convention to support a tail-latency claim.
- Latency Tail latency mean vs tail
Tail latency describes slow outcomes that an average elapsed time can hide.
- Observability can help explain Tail latency
Latency distributions reveal a slow population; traces and event records help investigate its path.
Find this idea across the book (3)
Task graphDevelopment A representation of work units and their dependencies, ownership, outputs, and integration points. Explore concept Group member
Development
Task graph
- Definition
- A representation of work units and their dependencies, ownership, outputs, and integration points.
- Assumptions
- Dependencies must reflect shared contracts and actual acceptance order. Independent files do not necessarily mean independent behavior.
- Worked example
- Fix the event schema before parallel API and UI tasks; reunite them in a shared-contract integration test.
- Common mistake
- Tasks that merge without conflicts were independent. A clean merge can still combine incompatible assumptions.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Task graph · 3 connections
Read the relationships
- Task graph organizes work in Agent fleet
A fleet's task graph states what can proceed independently and where contracts or integration impose order.
- Application contract constrains independence in Task graph
Task independence depends on compatible shared contracts, not merely separate files.
- Task graph requires Acceptance criteria
Integration points in a task graph need acceptance checks that cover the combined behavior.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (1)
- Task graph: connections
Task graph and its 3 neighboring concepts. Labels state the authored relationships.
Follow the idea
- Fleets: define the task graph
Separate parallel work from ordered integration.
- Appendix D: task and resource control
Keep task dependencies distinct from access permissions.
Connect the concepts
- Task graph organizes work in Agent fleet
A fleet's task graph states what can proceed independently and where contracts or integration impose order.
- Application contract constrains independence in Task graph
Task independence depends on compatible shared contracts, not merely separate files.
- Task graph requires Acceptance criteria
Integration points in a task graph need acceptance checks that cover the combined behavior.
Find this idea across the book (4)
Technical debtDevelopment Future change cost or reduced practical options created by earlier design or process shortcuts, compromises, or unmanaged coupling. Explore concept Group member
Development
Technical debt
- Definition
- Future change cost or reduced practical options created by earlier design or process shortcuts, compromises, or unmanaged coupling.
- Assumptions
- Identify the earlier choice, future change it obstructs, and evidence of its cost. A necessary hard commitment is not automatically debt; deliberately accepted debt can be justified when its future cost is visible and owned.
- Worked example
- An undocumented schema assumption spreads into the API and UI. Adding one state later requires coordinated changes whose boundaries are hard to find.
- Common mistake
- Debt is merely untidy code. Coupled contracts, environments, and missing ownership can reduce optionality even when the code is neat.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Technical debt · 7 connections
Read the relationships
- Decision log can document Technical debt
A record makes deliberately accepted debt and its future change cost visible so an owner can review it instead of letting the obligation disappear from view.
- Decision reversibility Technical debt commitment vs debt
Technical debt can reduce future options, but a hard decision is not automatically debt; its dependencies and reversal cost may be necessary and justified.
- Development friction Technical debt change cost
Friction can expose the practical cost of technical debt, but protective checks and necessary commitments are not automatically debt.
- Scaling pressure can expose Technical debt
Change pressure can expose future change cost from earlier shortcuts, compromises, or unmanaged coupling. A necessary compatibility obligation alone does not establish technical debt.
- Maintainability assessment can reveal Technical debt
A bounded change probe can expose coupling or earlier shortcuts that make a later modification costly even when current behavior tests pass. Use that evidence to distinguish debt from necessary compatibility work.
- Feedback loop Technical debt omitted future cost
Feedback that omits the cost of later changes can allow technical debt to grow while current tasks pass.
- Technical debt Application contract coupled contracts
Unclear or tightly coupled contracts can make one local change require coordinated changes elsewhere.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (2)
- Technical debt: connections
Technical debt and its 7 neighboring concepts. Labels state the authored relationships.
- Knowledge and artifact ownership
Reusable source knowledge stays external; Slideotter and Kirjolab own their artifact-specific decisions.
Follow the idea
- Challenge: reduced optionality
Connect commitments with future choices.
- Kirjolab: revise the architecture
Follow consolidation after rapid generation.
- Friction: find the commitment point
Distinguish the cost of reversing a commitment from technical debt.
Connect the concepts
- Decision log can document Technical debt
A record makes deliberately accepted debt and its future change cost visible so an owner can review it instead of letting the obligation disappear from view.
- Decision reversibility Technical debt commitment vs debt
Technical debt can reduce future options, but a hard decision is not automatically debt; its dependencies and reversal cost may be necessary and justified.
- Development friction Technical debt change cost
Friction can expose the practical cost of technical debt, but protective checks and necessary commitments are not automatically debt.
- Scaling pressure can expose Technical debt
Change pressure can expose future change cost from earlier shortcuts, compromises, or unmanaged coupling. A necessary compatibility obligation alone does not establish technical debt.
- Maintainability assessment can reveal Technical debt
A bounded change probe can expose coupling or earlier shortcuts that make a later modification costly even when current behavior tests pass. Use that evidence to distinguish debt from necessary compatibility work.
- Feedback loop Technical debt omitted future cost
Feedback that omits the cost of later changes can allow technical debt to grow while current tasks pass.
- Technical debt Application contract coupled contracts
Unclear or tightly coupled contracts can make one local change require coordinated changes elsewhere.
Find this idea across the book (6)
ThroughputEvidence The rate of completed work at a declared boundary. Explore concept Group member
Evidence
Throughput
- Definition
- The rate of completed work at a declared boundary. Useful throughput counts completions that meet the stated correctness and quality criteria.
- Assumptions
- Name the completion event, units, and window. Offered, admitted, and completed work are different rates, especially during overload or asynchronous processing.
- Worked example
- A service acknowledges 150 events/s while its worker makes 100 events/s visible. Acknowledgment throughput is 150/s; visible-event throughput is 100/s. If all admitted events remain pending until processed, backlog grows by 50 events/s.
- Common mistake
- More acknowledgments or generated changes mean more useful output. Pending events and unreviewed changes have not yet crossed their completion boundary.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Throughput · 6 connections
Read the relationships
- Throughput Queue arrivals and exits
Compare admissions with all departures at the queue boundary to explain backlog growth. Useful throughput separately counts completions that meet the declared outcome criteria.
- Saturation bounds sustainable Throughput
The saturated stage bounds the sustainable completion rate for the declared workload.
- Throughput Amdahl's Law ideal gain vs output
An Amdahl speedup bound does not guarantee accepted-change throughput; review, coordination, and correctness still matter.
- Goodhart's Law warns about targeting Throughput
Counting generated or acknowledged work can become a misleading target when useful accepted completions are the intended outcome.
- Review capacity can limit accepted Throughput
Reviewer attention and correction effort can limit accepted-change throughput even when generation speeds up.
- Contention can reduce Throughput
Competition for a shared resource can make throughput plateau or decline as workers are added.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (5)
- Throughput: connections
Throughput and its 6 neighboring concepts. Labels state the authored relationships.
- Three connected scalability loops
Pressure becomes development work; accepted agent-assisted change alters the application and its next likely limit.
- Sequential work bound
Inspect the ideal speedup bound when part of a fixed workload stays sequential.
Predict first. With 80% parallelizable work, will increasing from four to eight agents double speedup?
- Saturation boundary lab
Compare offered, admitted and completed event rates and move the binding limit.
Predict first. If you raise only the database capacity, which stage will limit completion next?
- Contention curve lab
Explore a modeled capacity curve as contention and coherency costs change.
Predict first. Will adding workers always increase capacity when coherency cost is nonzero?
Follow the idea
Explore through a course task (1)
- Vary human work in progress
Keep the same worker limit while changing how many unfinished changes enter the workflow. Plan a bounded comparison.
- Measurement: count outcomes separately
Separate offered, admitted, completed, and timed-out work.
- Fleets: sequential review limits speedup
Measure accepted changes rather than generation activity.
Connect the concepts
- Throughput Queue arrivals and exits
Compare admissions with all departures at the queue boundary to explain backlog growth. Useful throughput separately counts completions that meet the declared outcome criteria.
- Saturation bounds sustainable Throughput
The saturated stage bounds the sustainable completion rate for the declared workload.
- Throughput Amdahl's Law ideal gain vs output
An Amdahl speedup bound does not guarantee accepted-change throughput; review, coordination, and correctness still matter.
- Goodhart's Law warns about targeting Throughput
Counting generated or acknowledged work can become a misleading target when useful accepted completions are the intended outcome.
- Review capacity can limit accepted Throughput
Reviewer attention and correction effort can limit accepted-change throughput even when generation speeds up.
- Contention can reduce Throughput
Competition for a shared resource can make throughput plateau or decline as workers are added.
Trade-offArchitecture A choice that improves one desired property while imposing a cost, risk, or obligation elsewhere. Explore concept Group member
Architecture
Trade-off
- Definition
- A choice that improves one desired property while imposing a cost, risk, or obligation elsewhere.
- Assumptions
- State which goal improves, who pays the cost, and under which conditions the choice remains worthwhile. Compare alternatives under compatible conditions.
- Worked example
- Acknowledging events before processing shortens acknowledgment latency, but creates a pending state, queue, drain procedure, and a second completion boundary.
- Common mistake
- A faster benchmark establishes the best design. Correctness, recovery, operating cost, and maintainability may change the decision.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Trade-off · 5 connections
Read the relationships
- Decision log records rationale for Trade-off
The log preserves the alternatives, rationale, and consequences that justified a trade-off under the conditions known at the time.
- Decision reversibility Trade-off option value
Planning a trade-off includes the value of keeping an uncertain choice soft and the obligations introduced by committing to it.
- Scalability Trade-off response obligations
A scaling response must justify the costs and obligations it introduces alongside the maintained goal.
- Cache introduces Trade-off
Caching can reduce dependency load while introducing invalidation, freshness, and access obligations.
- Admission and backpressure can introduce Trade-off
Bounding admission can preserve useful service while sacrificing immediate acceptance of some work.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (6)
- Trade-off: connections
Trade-off and its 5 neighboring concepts. Labels state the authored relationships.
- One application, three development systems
The task stays comparatively stable while the development system changes. Learning accumulates; application code does not.
- From pressure to bounded evidence
A scaling response remains a hypothesis until bounded evidence challenges the maintained goal, limit, and trade-off.
- Cache decision lab
Trace reuse, validation, and stale responses under different HTTP cache policies.
Predict first. Which policy can reuse a response without contacting the origin, and what freshness promise does that make?
- Web architecture lens
Compare page navigation, HTML fragments, and browser-built views for the same operation.
Predict first. Which local state might be lost when an action causes a full-page navigation?
- Latency budget map
Estimate latency contributions from geography, round trips, and execution time.
Predict first. Which will matter more in your scenario: faster query execution or fewer sequential remote round trips?
Follow the idea
- Scaling: assess the obligations
Explain the operating contract each response introduces.
- Recap: make a decision
Use evidence and constraints to justify a preference.
Connect the concepts
- Decision log records rationale for Trade-off
The log preserves the alternatives, rationale, and consequences that justified a trade-off under the conditions known at the time.
- Decision reversibility Trade-off option value
Planning a trade-off includes the value of keeping an uncertain choice soft and the obligations introduced by committing to it.
- Scalability Trade-off response obligations
A scaling response must justify the costs and obligations it introduces alongside the maintained goal.
- Cache introduces Trade-off
Caching can reduce dependency load while introducing invalidation, freshness, and access obligations.
- Admission and backpressure can introduce Trade-off
Bounding admission can preserve useful service while sacrificing immediate acceptance of some work.
TransactionArchitecture A unit of state change with declared atomicity, isolation, and durability guarantees used to preserve invariants across concurrency and failure. Explore concept Group member
Architecture
Transaction
- Definition
- A unit of state change with declared atomicity, isolation, and durability guarantees used to preserve invariants across concurrency and failure.
- Assumptions
- Check the actual store and isolation behavior. A database transaction does not automatically make effects in an external service atomic with its commit.
- Worked example
- Commit the event and its reusable idempotency result together so a retried command cannot observe only half of the intended state.
- Common mistake
- Using a transaction makes every distributed action exactly once. External effects and ambiguous outcomes still need their own protocol.
Explore this topic's connections
Explore the connections
Select a topic to read its definition and discover connections beyond this reading.
Read arrows as topic → relationship → topic. Plain lines connect comparisons and associations.
Transaction · 3 connections
Read the relationships
- Transaction protects changes to Authoritative state
Transactions protect related changes at the durable authority under the store's actual guarantees.
- Transaction must preserve Invariant
The chosen transaction and isolation behavior must preserve the domain invariant under concurrent transitions.
- Transaction can support Idempotency
A key-based command protocol can atomically enforce operation identity with the promised effects and a reusable result at their authority. A transaction alone does not prevent repeated commands.
Try explaining a connection
Hide the labels and choose two connected topics. Write a linking phrase and decide whether the statement needs a direction. Read it as a complete sentence, then compare it with the authored label and explanation. Which assumption makes it hold, and when might it fail?
Diagrams and experiments (2)
- Transaction: connections
Transaction and its 3 neighboring concepts. Labels state the authored relationships.
- ACID transaction lab
Inspect lifecycle and ledger records under failed writes, concurrency, and restart.
Predict first. Which invariant could fail between two application-managed writes?
Follow the idea
- Architecture: preserve invariants
Explain why the state changes belong together.
- Appendix C: transaction guarantees
Test concurrency and failure assumptions.
Connect the concepts
- Transaction protects changes to Authoritative state
Transactions protect related changes at the durable authority under the store's actual guarantees.
- Transaction must preserve Invariant
The chosen transaction and isolation behavior must preserve the domain invariant under concurrent transitions.
- Transaction can support Idempotency
A key-based command protocol can atomically enforce operation identity with the promised effects and a reusable result at their authority. A transaction alone does not prevent repeated commands.
Find this idea across the book (3)